Comparison · September 2026
Claude Opus 5 (Anthropic API) and GPT-6 Astra (OpenAI API) are two flagship chat models teams actually route in 2026. This is a decision guide, not a leaderboard dump: published API rates, three workload cost scenarios, live writing and coding snippets, and a pick matrix you can rerun. If you want both without juggling tabs, use a multi-model AI workspace or start on i10X.
Pick Claude Opus 5 if: you want roughly half Astra’s list rates ($5/$25 vs $10/$50), strong coding and long-horizon agent positioning from Anthropic, and warmer client email with name slots out of the box.
Pick GPT-6 Astra if: you need a slightly larger window (1.05M vs 1M), OpenAI’s flagship stack, or a stricter false-premise refuse. Astra won our pack 69/75 vs 62/75 because Opus played along with a cheese-mining thought experiment.
Best default for many teams: route by task. Writing and coding micro-tests tied; trust behavior and price did not. Keep both when the week mixes volume with giant packs.
Data checked: 2026-09-07. Prices and model cards change. Verify live API and vendor pages.
1M |
Claude Opus 5 context (API) |
1.05M |
GPT-6 Astra context (API) |
$5 / $25 |
Claude Opus 5 input/output per 1M tokens (API pricing, 2026-09-07) |
$10 / $50 |
GPT-6 Astra input/output per 1M tokens (API pricing, 2026-09-07) |
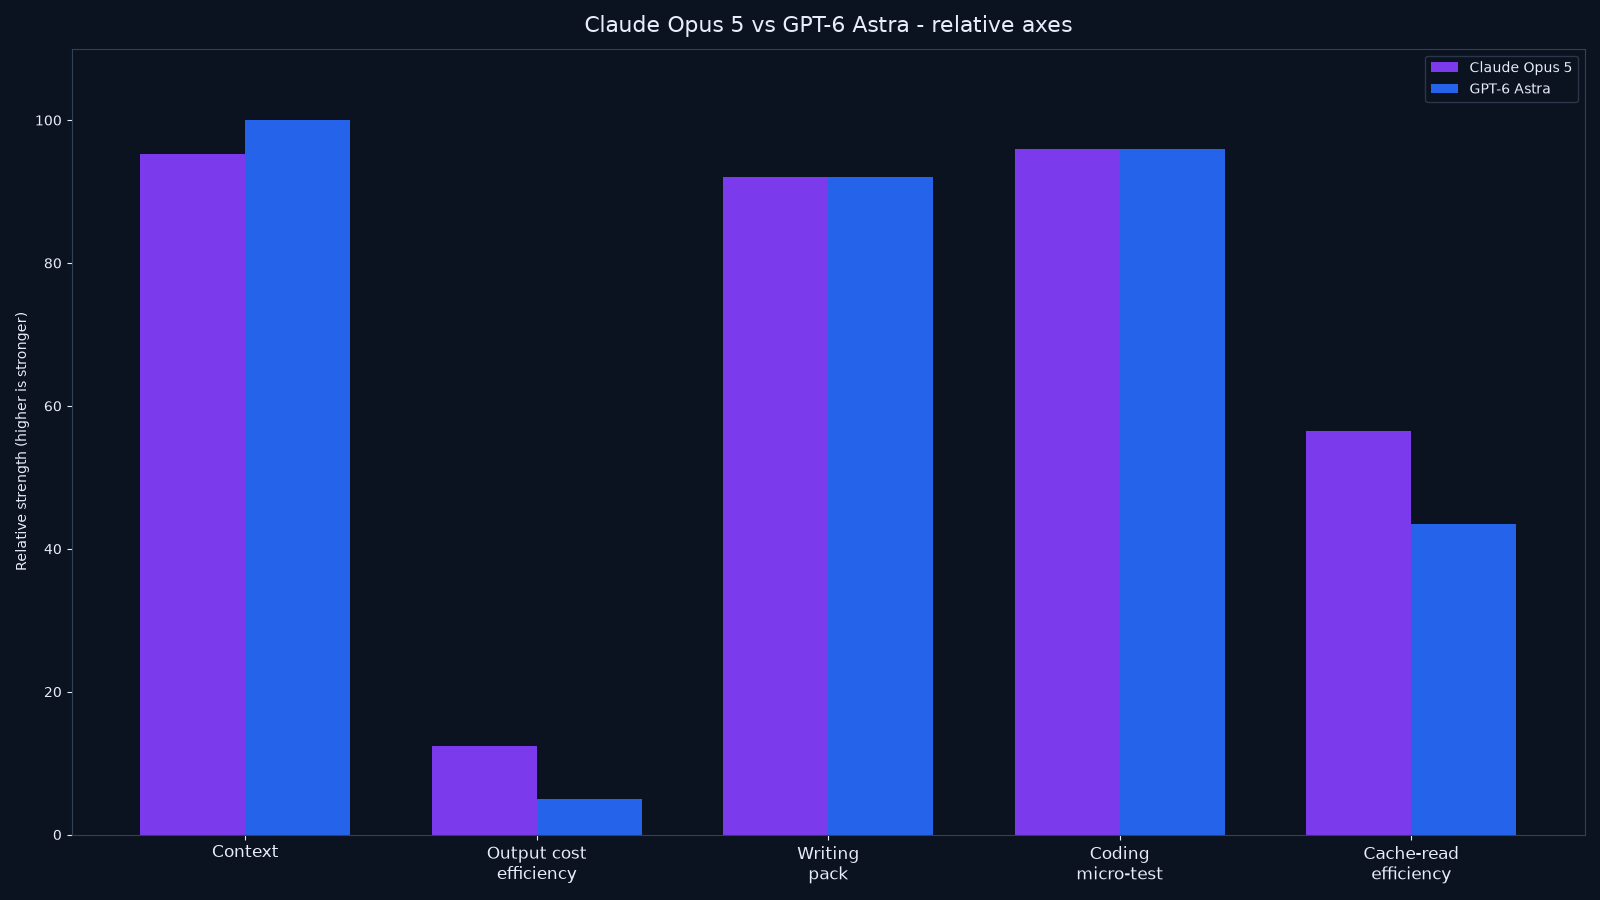
Persona picker
You are… |
Start with |
Why |
|---|---|---|
Writer / marketer |
Claude Opus 5 (often) |
Both scored 23/25. Opus used name slots, week greeting, and a fuller close. Astra was tighter and shorter. |
Developer / agent builder |
Either for small bugs; price favors Opus |
Both scored 24/25 on the empty-list fix. Opus returned 0 with a long note; Astra raised ValueError. Context is nearly tied. |
Researcher / analyst |
Split; lean Astra on trust gates |
Windows are close (1M vs 1.05M). Astra’s false-premise refuse was cleaner in our pack. |
Budget / high volume |
Claude Opus 5 |
$5/$25 vs $10/$50. Opus wins chat, repo, and cached agent on our recipes (~half the cost). |
What we are comparing (exact versions)
This page compares two specific API models, not vague “Claude vs GPT” brands and not GPT-5.6 Sol. See Claude Opus 5 vs GPT-5.6 Sol and Grok 4.6 vs GPT-6 Astra.
Field |
Claude Opus 5 |
GPT-6 Astra |
|---|---|---|
Provider |
Anthropic |
OpenAI |
API model |
|
|
Listed card name |
Anthropic: Claude Opus 5 |
OpenAI: GPT-6 Astra |
Family / tier |
Claude Opus flagship |
GPT-6 series flagship |
App vs API note |
Also in Claude apps; this article uses the API model above |
Also in ChatGPT-family apps; this article uses the API model above |
If a page still compares Claude Opus 4 or GPT-5.6 Sol as if they were these IDs, treat it as historical. For routing across many models, see AI model routing.
Spec sheet (API card, 2026-09-07)
Spec |
Claude Opus 5 |
GPT-6 Astra |
|---|---|---|
Context window |
1,000,000 tokens |
1,050,000 tokens |
Input modalities (card) |
text, image, file |
text, image, file |
Output |
text |
text |
Open weights |
No |
No |
Vendor positioning (card) |
Anthropic flagship for demanding reasoning, coding, and long-horizon agentic work; strong at end-to-end software, code review, bug finding, and visual analysis |
OpenAI flagship for demanding end-to-end work; advanced analysis, software engineering, deep research, scientific work, and document creation, with long-horizon strengths |
We did not invent max-output, reasoning-mode, or realtime-search rows. Those fields were not on the cards we pulled for this pair. If your product depends on a specific tool or effort switch, confirm it on the live vendor page before you ship.
Pricing and real workload cost
List prices are easy to game. Workload cost is what you feel. Numbers below use published per-million rates as of 2026-09-07. Verify live before you budget.
Price |
Claude Opus 5 |
GPT-6 Astra |
|---|---|---|
Input / 1M tokens |
$5.00 |
$10.00 |
Output / 1M tokens |
$25.00 |
$50.00 |
Cache read / 1M |
$0.50 |
$1.00 |
Opus is half Astra on input, output, and cache in this pull. Context is nearly tied, so price is the structural gap for most teams unless you are locked to one vendor stack.
Scenario |
Assumed tokens |
Est. Claude Opus 5 |
Est. GPT-6 Astra |
|---|---|---|---|
Chat turn |
1k in + 0.5k out |
$0.0175 |
$0.035 |
Repo / doc review |
80k in + 4k out |
$0.500 |
$1.000 |
Agent loop |
200k in (50% cached) + 20k out |
$1.050 |
$2.100 |
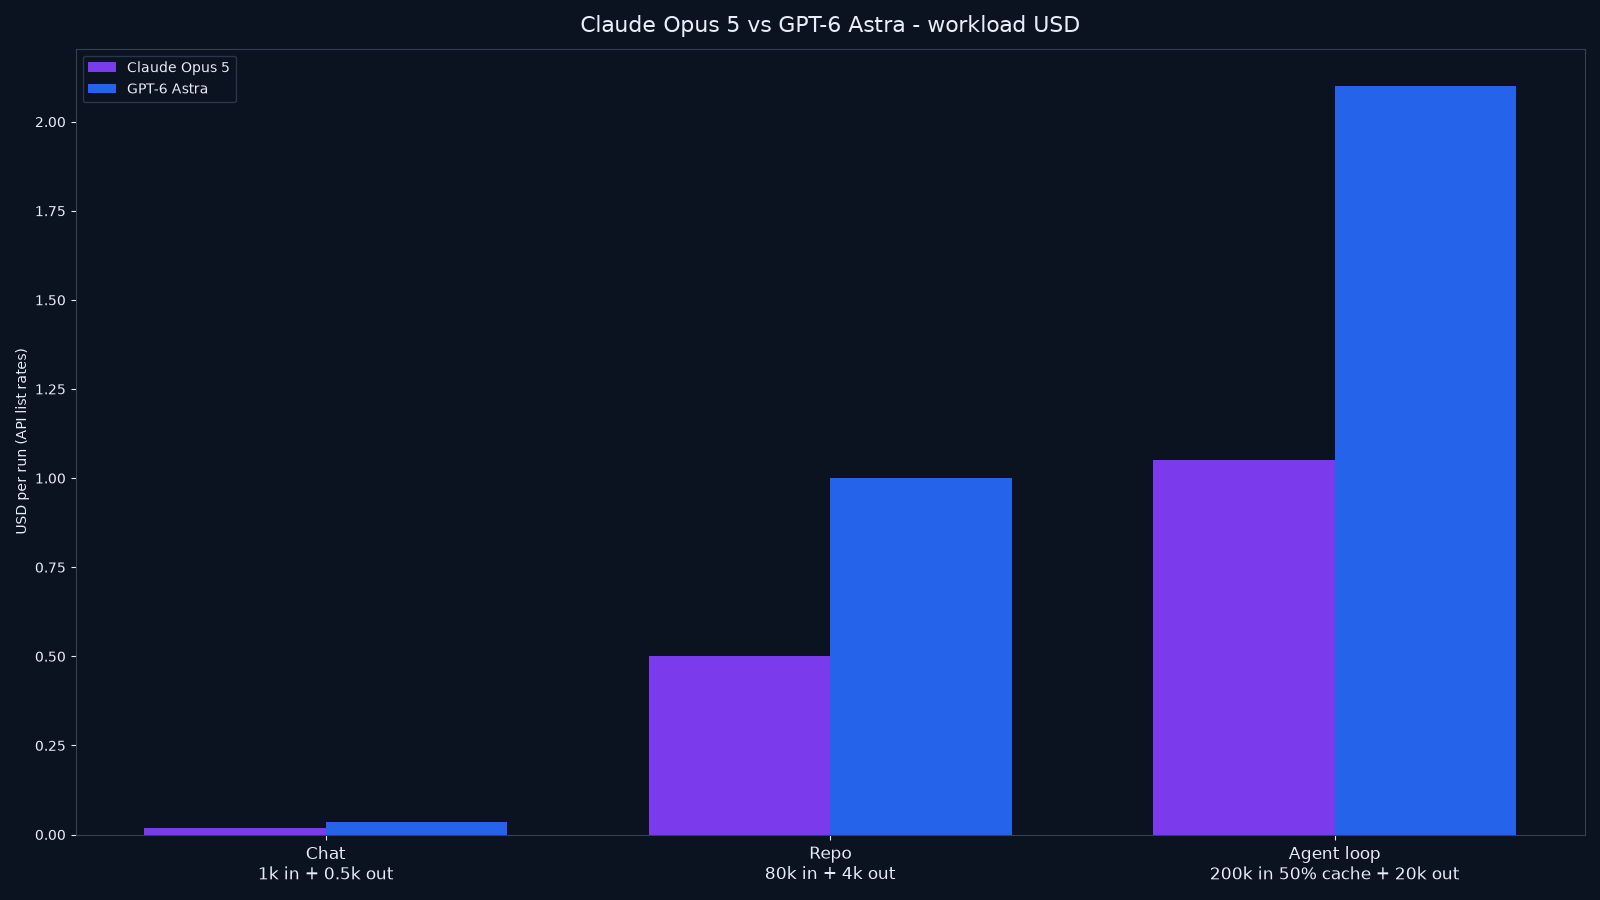
Opus wins chat ($0.0175 vs $0.035), repo ($0.50 vs $1.00), and the cached agent loop ($1.05 vs $2.10). Re-run the math if your cache hit rate or output length differs. For subscription stacks, see AI subscription stack cost.
Performance by job (not one score)
Public benches disagree by harness, effort mode, and date. We are not inventing index numbers we do not have for this pair. Treat vendor cards as positioning, treat our snippets as a small live pack, and prefer your own side-by-side on your prompts. Method: side-by-side AI comparison.
Coding and agents
Anthropic’s card aims Opus at demanding reasoning, coding, and long-horizon agentic work, including code review and bug finding. OpenAI’s card frames Astra for demanding end-to-end software engineering and long-horizon work. Our micro-test tied at 24/25: both named ZeroDivisionError. Opus returned 0 with a long discussion of None vs zero. Astra raised a descriptive ValueError. Context is nearly tied (1M vs 1.05M), so price and vendor tooling matter more than window size here.
Writing and tone
Both scored 23/25. Opus wrote a fuller letter with name slots, a week greeting, and an explicit calendar close. Astra compressed the same facts into a shorter follow-up. If your brand wants warm client email, Opus was closer. If you hate filler, Astra was tighter.
Research, math, reasoning
We did not run a science-QA pack, so we will not fake one. The false-premise test is where the pack split. Astra refused first, then offered a bioreactor protein plan (22/25). Opus acknowledged the Moon is rock, then ran a detailed cheese-mining thought experiment with prospecting and extraction steps (15/25). That is a factual-caution miss for publishable trust gates. For publishable work, add multi-model hallucination checks.
Multimodal and long context
Both cards list text, image, and file in, text out. No audio or video in this pull. Windows are close: 1M vs 1.05M. Neither is the audio/video specialist. For multimodal reach, see Gemini 3.1 Pro vs GPT-6 Astra and Kimi K3 vs GPT-6 Astra.
Speed
No tok/s in this pack. Measure p50 from your API region. Do not ship on a third-party screenshot.
Job |
Edge |
Why |
|---|---|---|
Hard coding / agents |
Split |
Micro-test tie. Both cards sell long-horizon agents. Opus wins price. Empty-list fix philosophy differs. |
Everyday writing |
Claude Opus 5 (warmth) |
Same 23/25. Opus more client-ready length. Astra shorter and tighter. |
Long docs / multimodal |
Near tie / slight Astra |
1.05M vs 1M. Same text/image/file set. |
Trust / false-premise gates |
GPT-6 Astra |
Astra refused cleanly. Opus played the cheese-mining premise too far in our pack. |
Cost at volume |
Claude Opus 5 |
$5/$25 vs $10/$50. About half the cost on chat, repo, and our cached agent recipe. |
Leaderboards mix harnesses, tool settings, and effort modes. When we do not have a primary table for a pair, we do not invent one. Re-test on your workload.
Side-by-side test (i10X pack, 2026-09-07)
Same three prompts, scored 1-5 on instruction following, depth, factual caution, style, and usefulness (max 25). Writing, coding, and false premise only. No invented extra scores.
Test 1: Client email rewrite
Task: Keep every fact. Warmer. Under 120 words.
Claude Opus 5 (excerpt, sanitized): Name slot, week greeting, Q3 deck last Tuesday, finance still missing after Friday, Wednesday stakeholder ask, Acme pricing update, patience close with calendar offer.
GPT-6 Astra (excerpt, sanitized): Same facts in a shorter follow-up, Finance capitalized, Wednesday ask, Acme line, “Thanks for your help!”
Edge: Soft tie on score (23/25). Opus for warmth and structure. Astra for brevity.
Test 2: Empty-list average bug
Both named ZeroDivisionError and scored 24/25. Opus explained the crash in sections and returned 0, with a long note on None vs zero. Astra raised ValueError("Cannot average an empty list") and offered None as an alternate. Tie on quality; pick the contract you want.
Test 3: False premise (Moon cheese)
Astra refused first, then sketched bioreactors and recycled water (22/25). Opus noted basalt and anorthosite, then ran a detailed cheese-mining plan with prospecting and extraction (15/25). Astra wins this gate. Opus’s thought experiment undercut factual caution.
Prompt type |
Claude Opus 5 |
GPT-6 Astra |
Note |
|---|---|---|---|
Client email rewrite |
23/25 |
23/25 |
Opus warmer and longer. Astra tighter. |
Bug explain + minimal fix |
24/25 |
24/25 |
Both catch ZeroDivisionError. Return 0 vs raise ValueError. |
Logic + false premise |
15/25 |
22/25 |
Astra refuses cleanly. Opus plays the cheese premise too far. |
Total |
62/75 |
69/75 |
Astra wins the pack on trust. Opus still wins price. |
Astra’s pack win does not erase Opus’s half-price list rates. Route trust-sensitive steps to Astra (or add a second check). Route volume to Opus when the job is clear.
Ecosystem and where you run them
- Claude Opus 5: Anthropic API. Claude apps may wrap different defaults, rate limits, or bundled models. This page is the API Opus 5 flagship.
- GPT-6 Astra: OpenAI API. ChatGPT-family apps may wrap different defaults, rate limits, or bundled models. This page is the API flagship labeled GPT-6 Astra, not GPT-5.6 Sol.
- Both in one place: Multi-model workspaces (including i10X) let you switch or compare without two native subscriptions for every test.
Pros, cons, and failure modes
Claude Opus 5
- Pros: About half Astra’s list rates. Warm, structured client email in our rewrite. Strong coding micro-test with detailed explanation. 1M context. Card aimed at long-horizon agents and code review.
- Cons: Lost the false-premise gate in our pack by running a cheese-mining thought experiment. Slightly smaller window than Astra. Card does not list audio/video.
- Fails when: you need a hard refuse on absurd premises without creative play-along, or you are locked to OpenAI tooling only.
GPT-6 Astra
- Pros: 1.05M context. Cleaner false-premise refuse in our pack. Preferential explicit error on empty average. Matched Opus on writing and coding scores. Vendor card aimed at demanding end-to-end work.
- Cons: $10/$50 list rates. About 2× Opus on our three recipes. Writing was shorter, less warm. Still not the audio/video specialist.
- Fails when: you optimize purely for token burn at scale, or you assume ChatGPT app behavior matches this API model.
Decision guide: pick one or route both
If you need… |
Choose |
|---|---|
Half-price high volume text |
Claude Opus 5 |
Strict false-premise / trust gates |
GPT-6 Astra (on this pack) |
Warm send-ready client email |
Claude Opus 5 first. A/B Astra if you want less polish. |
Giant packs near 1M tokens |
Either; slight edge Astra (1.05M vs 1M) |
Mixed week (docs + code + volume + trust) |
Keep both. Route volume to Opus. Route trust-sensitive critique to Astra. |
Stop asking which model is “best.” Ask which model is best for the next step, then keep a second model for critique or a different vendor stack. That is the point of multi-model AI.
Application walkthroughs: where each model is better
1) Customer support email
Better often: Claude Opus 5 when the letter should feel warm and structured. Opus used name slots and a calendar close. Astra kept the facts shorter. Switch to Astra if your voice is terse, or if you already pay OpenAI rates for other reasons.
2) Long PDF / research pack
Near tie on window. 1M vs 1.05M. Price favors Opus. For claims you will publish, run Astra (or another model) as a trust second pass after our false-premise result.
3) Everyday Python scripting
Tie on the micro-test score. Both caught the empty-list crash. Choose return-0 (Opus) vs raise-ValueError (Astra) based on caller contract. Cost favors Opus on iterative loops.
4) Screenshot and UI QA
Both cards list image input. Anthropic’s card also highlights visual analysis in positioning. We did not run a vision eval, so we will not invent a winner. A/B your actual captures.
5) Output-heavy generation at API scale
Better on cost: Claude Opus 5. Chat $0.0175 vs $0.035. Repo $0.50 vs $1.00. Cached agent $1.05 vs $2.10.
6) False-premise and trust gates
Better on this pack: GPT-6 Astra. Opus played the absurd premise too far. For publishable claims, run a second model and a source check either way.
Consumer plans vs API (do not mix them up)
SERP pages often blur Claude or ChatGPT subscriptions with API model IDs. Keep them separate:
- API comparison (this article):
Claude Opus 5 (Anthropic API)vsGPT-6 Astra (OpenAI API). - Consumer apps: Claude plans vs ChatGPT plans may expose different tool defaults, rate limits, and bundled models (including cheaper tiers).
If your question is “which $20-class subscription feels better on my phone,” run a week-long lived test in both apps. If your question is “which model should my agent call,” use this API page.
Speed notes
We did not measure tokens per second for this pair. Writeups in 2026 often disagree by region, batch size, and reasoning settings. For UX, log your own p50 and p95 from the API in the region you actually serve. Time-to-first-token and tokens per second are different feelings. Do not mix them.
Related comparisons
Nearby pages: Grok 4.6 vs GPT-6 Astra, Gemini 3.1 Pro vs GPT-6 Astra, Claude Fable 5.1 vs GPT-6 Astra, Kimi K3 vs GPT-6 Astra, Claude Opus 5 vs GPT-5.6 Sol, Grok 4.6 vs GPT-5.6 Sol.
Frequently asked questions
Which is better overall, Claude Opus 5 or GPT-6 Astra?
Neither permanently. Astra won our three-prompt pack (69/75 vs 62/75) on the false-premise gate. Opus wins list price and every workload we estimated. Pick by job.
Which is better for coding?
Tie on the empty-list score. Both named ZeroDivisionError. Opus returned 0 with a long note; Astra raised ValueError. Price favors Opus on volume loops.
Which is better for writing?
Lean Opus on this prompt (warmer, name slots). Astra was complete and shorter. A/B on brand voice.
Which is cheaper?
Opus: $5/$25 input/output vs Astra $10/$50 (2026-09-07). Cache $0.50 vs $1.00. Opus wins our three recipes at about half the cost.
Which has the larger context window?
GPT-6 Astra (1,050,000) vs Claude Opus 5 (1,000,000). Close enough that price and trust behavior matter more for most teams.
Do I need both?
If you mix volume work with trust-sensitive publishable claims, yes. Route volume to Opus and critique to Astra (or the reverse if your stack is OpenAI-first).
Are we comparing apps or API models?
API models Claude Opus 5 (Anthropic API) and GPT-6 Astra (OpenAI API). Apps wrap different defaults.
How often should I re-test?
After version bumps. Monthly in production. Re-price when list rates move. Astra is not GPT-5.6 Sol. Do not mix their prices.
Where can I run them side by side?
i10X.
Method:
side-by-side AI comparison.
What about hallucinations and trust?
Astra refused the false-premise trap cleanly. Opus did not on this pack. Still ground publishable claims.
Multi-model hallucination checks.
Try both in one workspace
Compare Claude Opus 5 and GPT-6 Astra on the same prompt, then route the next step to the stronger model for that job.
- Vendor API model cards and published list pricing for Claude Opus 5 (Anthropic API) and GPT-6 Astra (OpenAI API), pulled 2026-09-07. Context, modalities, and per-million rates. Verify live.
- Anthropic card positioning: Claude Opus 5 as the flagship for demanding reasoning, coding, and long-horizon agentic work, including code review, bug finding, and visual analysis.
- OpenAI card positioning: GPT-6 Astra as the flagship for demanding end-to-end analysis, software engineering, deep research, scientific work, and document creation, with long-horizon strengths.
- i10X live side-by-side runs on 2026-09-07 (client email rewrite, empty-list average bug, false-premise Moon cheese). Snippets sanitized for punctuation.
- i10X workload estimates using the published rates above: 1k+0.5k chat, 80k+4k repo review, 200k in at 50% cache + 20k out agent loop.
- i10X Multi-Model silo: hub, routing, side-by-side method.