Comparison · October 2026
Claude Opus 5.5 (Anthropic API) and GPT-6.1 Sol (OpenAI API) are two chat models teams actually route in 2026. This is a decision guide, not a leaderboard dump: published API rates, three workload cost scenarios, live writing and coding snippets, and a pick matrix you can rerun. If you want both without juggling tabs, use a multi-model AI workspace or start on i10X.
Pick Claude Opus 5.5 if: you want a deeper empty-list coding writeup.
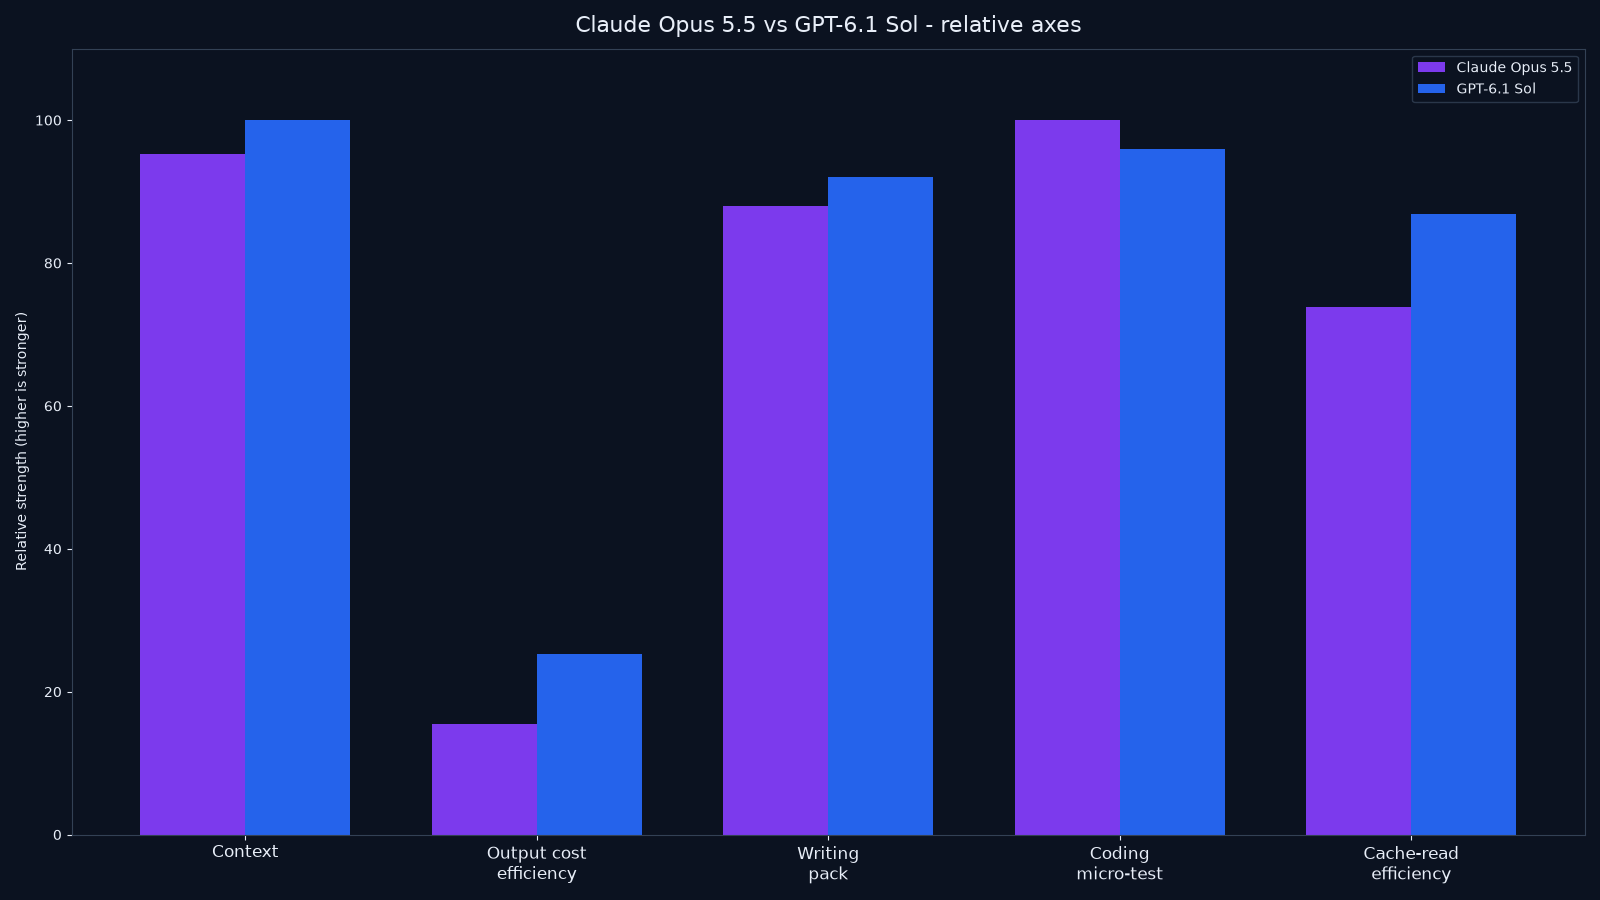
Pick GPT-6.1 Sol if: you want cheaper output ($10.00 vs $20.00 per 1M), cheaper input ($2.00 vs $4.00), the larger window (1.05M vs 1M), and cheaper cache reads ($0.10 vs $0.20).
Best default for many teams: route by task and keep both available. See the decision matrix below.
Data checked: 2026-10-12. Prices and model cards change. Verify live API and vendor pages.
1M |
Claude Opus 5.5 context (API) |
1.05M |
GPT-6.1 Sol context (API) |
$4.00 / $20.00 |
Claude Opus 5.5 input/output per 1M tokens (API pricing, 2026-10-12) |
$2.00 / $10.00 |
GPT-6.1 Sol input/output per 1M tokens (API pricing, 2026-10-12) |
Persona picker
You are… |
Start with |
Why |
|---|---|---|
Writer / marketer |
GPT-6.1 Sol |
Two tight paragraphs, all facts, no greeting filler, under 120 words. |
Developer / agent builder |
GPT-6.1 Sol for huge repos; Claude Opus 5.5 for cheap loops |
Window 1.05M vs 1M. Micro-test: Named ZeroDivisionError. Two options (None vs ValueError), warns that 0 hides bugs, notes statistics.mean. / Named ZeroDivisionError. Minimal ValueError guard. Clear empty-list contract. |
Researcher / analyst |
GPT-6.1 Sol |
1M vs 1.05M on the cards we pulled. |
Budget / high volume |
GPT-6.1 Sol |
Cheaper on our chat recipe (Claude Opus 5.5 $0.014 vs GPT-6.1 Sol $0.0070). |
What we are comparing (exact versions)
This page compares two specific API models, not vague brand names and not last quarter’s IDs. Nearby versioned pages: Claude Opus 5 vs GPT-5.6 Sol, Claude Opus 5 vs GPT-6 Astra, Grok 4.7 vs Claude Opus 5.5, Grok 4.7 vs GPT-6.1 Sol, Claude Sonnet 5.5 vs GPT-6.1 Sol, and Qwen3.8 Max Prime vs Claude Opus 5.5.
Field |
Claude Opus 5.5 |
GPT-6.1 Sol |
|---|---|---|
Provider |
Anthropic |
OpenAI |
API model |
|
|
Listed card name |
Anthropic: Claude Opus 5.5 |
OpenAI: GPT-6.1 Sol |
Family / tier |
Claude 5.5 flagship |
GPT-6.1 series flagship |
App vs API note |
Also in Claude apps; this article uses the API model above |
Also in ChatGPT-family apps; this article uses the API model above |
If a page still compares older IDs as if they were these cards, treat it as historical. For routing across many models, see AI model routing.
Spec sheet (API card, 2026-10-12)
Spec |
Claude Opus 5.5 |
GPT-6.1 Sol |
|---|---|---|
Context window |
1,000,000 tokens |
1,050,000 tokens |
Input modalities (card) |
text, image, file |
text, image, file |
Output |
text |
text |
Open weights |
No |
No |
Vendor positioning (card) |
Anthropic flagship succeeding Opus 5; demanding reasoning, coding, long-horizon agents, multi-step changes in large codebases |
Upgrade to GPT-6 Sol, below Astra in the GPT-6 series; agentic coding, computer use, document-heavy professional work |
We did not invent max-output, reasoning-mode, or realtime-search rows. Those fields were not on the cards we pulled for this pair. If your product depends on a specific tool or effort switch, confirm it on the live vendor page before you ship.
Pricing and real workload cost
List prices are easy to game. Workload cost is what you feel. Numbers below use published per-million rates as of 2026-10-12. Verify live before you budget.
Price |
Claude Opus 5.5 |
GPT-6.1 Sol |
|---|---|---|
Input / 1M tokens |
$4.00 |
$2.00 |
Output / 1M tokens |
$20.00 |
$10.00 |
Cache read / 1M |
$0.20 |
$0.10 |
Input $4.00 vs $2.00. GPT-6.1 Sol is cheaper on output ($10.00 vs $20.00). GPT-6.1 Sol is cheaper on cache reads ($0.10 vs $0.20). If your agent stack actually hits cache, that gap matters.
Scenario |
Assumed tokens |
Est. Claude Opus 5.5 |
Est. GPT-6.1 Sol |
|---|---|---|---|
Chat turn |
1k in + 0.5k out |
$0.014 |
$0.0070 |
Repo / doc review |
80k in + 4k out |
$0.400 |
$0.200 |
Agent loop |
200k in (50% cached) + 20k out |
$0.820 |
$0.410 |
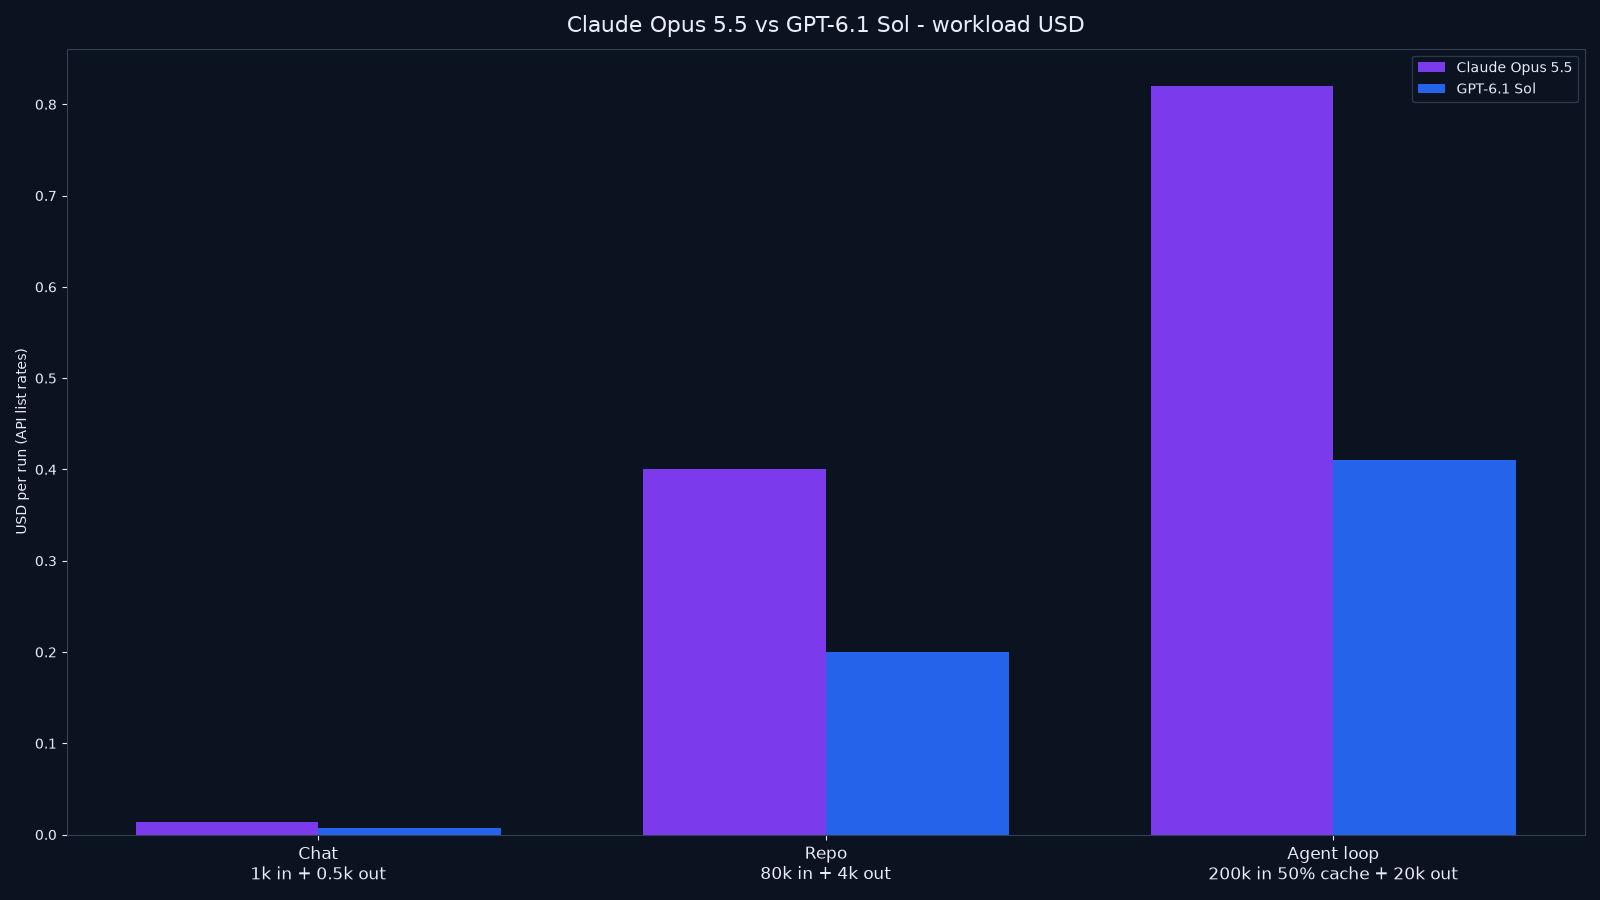
On the cached agent recipe, GPT-6.1 Sol wins ($0.820 vs $0.410). Re-run the math if you cache harder. For subscription stacks, see AI subscription stack cost.
Performance by job (not one score)
Public benches disagree by harness, effort mode, and date. We are not inventing index numbers we do not have for this pair. Treat vendor cards as positioning, treat our snippets as a small live pack, and prefer your own side-by-side on your prompts. Method: side-by-side AI comparison.
Coding and agents
Anthropic flagship succeeding Opus 5; demanding reasoning, coding, long-horizon agents, multi-step changes in large codebases. Upgrade to GPT-6 Sol, below Astra in the GPT-6 series; agentic coding, computer use, document-heavy professional work. Those are positioning lines, not benches. Our micro-test: Named ZeroDivisionError. Two options (None vs ValueError), warns that 0 hides bugs, notes statistics.mean. Named ZeroDivisionError. Minimal ValueError guard. Clear empty-list contract. Window size and cache price matter more on long agent loops than this snippet.
Writing and tone
GPT-6.1 Sol on tightness. Name slots, week-greeting opener, all facts, longer and more ceremonial than the brief asked. Two tight paragraphs, all facts, no greeting filler, under 120 words. If your brand wants send-ready client email, prefer the tighter letter. If you hate filler, prefer the shorter note.
Research, math, reasoning
We did not run a science-QA pack, so we will not fake one. False-premise: Refused, then a long playful cheese-mining skit, then a real ice-and-microbe redirect. Refuse, then a four-step bioreactor plan. Protein on the Moon, not cheese mining. For publishable work, add multi-model hallucination checks.
Multimodal and long context
Claude Opus 5.5 lists text, image, file in, text out. GPT-6.1 Sol lists text, image, file in, text out. Context is 1,000,000 tokens vs 1,050,000 tokens. Giant packs go to the larger window. Audio or video only if the card actually lists it.
Speed
No tok/s in this pack. Measure p50 from your API region. Do not ship on a third-party screenshot.
Job |
Edge |
Why |
|---|---|---|
Hard coding / agents |
Claude Opus 5.5 |
Named ZeroDivisionError. Two options (None vs ValueError), warns that 0 hides bugs, notes statistics.mean. Named ZeroDivisionError. Minimal ValueError guard. Clear empty-list contract. |
Everyday writing |
GPT-6.1 Sol |
Name slots, week-greeting opener, all facts, longer and more ceremonial than the brief asked. Two tight paragraphs, all facts, no greeting filler, under 120 words. |
Long docs / multimodal |
GPT-6.1 Sol |
1.05M vs 1M. Input set: text, image, file vs text, image, file. |
Realtime / conversational |
Product-dependent |
Product-dependent. Confirm tools, voice, and search in the app you actually ship. Not measured here. |
Cost at volume |
GPT-6.1 Sol |
Chat Claude Opus 5.5 $0.014 vs GPT-6.1 Sol $0.0070. Repo $0.400 vs $0.200. Cached agent $0.820 vs $0.410. |
Leaderboards mix harnesses, tool settings, and effort modes. When we do not have a primary table for a pair, we do not invent one. Re-test on your workload.
Side-by-side test (i10X pack, 2026-10-12)
Same three prompts, scored 1-5 on instruction following, depth, factual caution, style, and usefulness (max 25). Writing, coding, and false premise only. No invented extra scores.
Test 1: Client email rewrite
Task: Keep every fact. Warmer. Under 120 words.
Claude Opus 5.5 (excerpt, sanitized): Name slots, week-greeting opener, all facts, longer and more ceremonial than the brief asked.
GPT-6.1 Sol (excerpt, sanitized): Two tight paragraphs, all facts, no greeting filler, under 120 words.
Edge: GPT-6.1 Sol. A/B on brand voice. Neither is allowed to drop Q3, Tuesday, Friday, Wednesday, finance, or Acme.
Test 2: Empty-list average bug
Named ZeroDivisionError. Two options (None vs ValueError), warns that 0 hides bugs, notes statistics.mean. Named ZeroDivisionError. Minimal ValueError guard. Clear empty-list contract. Claude Opus 5.5.
Test 3: False premise (Moon cheese)
Refused, then a long playful cheese-mining skit, then a real ice-and-microbe redirect. Refuse, then a four-step bioreactor plan. Protein on the Moon, not cheese mining. Split.
Prompt type |
Claude Opus 5.5 |
GPT-6.1 Sol |
Note |
|---|---|---|---|
Client email rewrite |
22/25 |
23/25 |
Name slots, week-greeting opener, all facts, longer and more ceremonial than the brief asked. |
Bug explain + minimal fix |
25/25 |
24/25 |
Named ZeroDivisionError. Two options (None vs ValueError), warns that 0 hides bugs, notes statistics.mean. |
Logic + false premise |
23/25 |
23/25 |
Refused, then a long playful cheese-mining skit, then a real ice-and-microbe redirect. |
Total |
70/75 |
70/75 |
Our three-prompt pack tied at 70/75. Jobs still split on price, window, and modalities. |
Our three-prompt pack tied at 70/75. Jobs still split on price, window, and modalities.
Ecosystem and where you run them
- Claude Opus 5.5: Anthropic API. Also in Claude apps; this article uses the API model above.
- GPT-6.1 Sol: OpenAI API. Also in ChatGPT-family apps; this article uses the API model above.
- Both in one place: Multi-model workspaces (including i10X) let you switch or compare without two native subscriptions for every test.
Pros, cons, and failure modes
Claude Opus 5.5
- Pros: Anthropic flagship succeeding Opus 5; demanding reasoning, coding, long-horizon agents, multi-step changes in large codebases. Context 1M. List rates $4.00 / $20.00. Cache $0.20. Input text, image, file.
- Cons: Smaller window than GPT-6.1 Sol. Live writing: Name slots, week-greeting opener, all facts, longer and more ceremonial than the brief asked.
- Fails when: you treat the card as a bench, skip a false-premise gate, or assume the consumer app matches this API ID.
GPT-6.1 Sol
- Pros: Upgrade to GPT-6 Sol, below Astra in the GPT-6 series; agentic coding, computer use, document-heavy professional work. Context 1.05M. List rates $2.00 / $10.00. Cache $0.10. Input text, image, file.
- Cons: Matched window, so the split is price and tone. Live writing: Two tight paragraphs, all facts, no greeting filler, under 120 words.
- Fails when: you optimize purely for one axis (price, or window, or a single writing sample) and never re-test after a version bump.
Decision guide: pick one or route both
If you need… |
Choose |
|---|---|
Output-cheap high volume text |
GPT-6.1 Sol |
Long PDF / giant repo packs |
GPT-6.1 Sol |
Send-ready client email |
GPT-6.1 Sol |
Cache-heavy agent loops |
Re-price. Cache $0.20 vs $0.10. Our 50% cache recipe: $0.820 vs $0.410. |
Mixed week (docs + code + volume) |
Keep both. Route long context to GPT-6.1 Sol. Route volume text to GPT-6.1 Sol. |
Stop asking which model is “best.” Ask which model is best for the next step, then keep a second model for critique or a different window size. That is the point of multi-model AI.
Application walkthroughs: where each model is better
1) Customer support email
Better often: GPT-6.1 Sol Two tight paragraphs, all facts, no greeting filler, under 120 words. Switch to Claude Opus 5.5 if you want Name slots, week-greeting opener, all facts, longer and more ceremonial than the brief asked.
2) Long PDF / research pack
Better: GPT-6.1 Sol. 1,000,000 tokens vs 1,050,000 tokens. Start the larger window on diligence rooms. Use the cheaper model as a second-pass critic.
3) Everyday Python scripting
Claude Opus 5.5. Named ZeroDivisionError. Two options (None vs ValueError), warns that 0 hides bugs, notes statistics.mean. Named ZeroDivisionError. Minimal ValueError guard. Clear empty-list contract. Huge doc-plus-code packs favor the larger window. Cheap iterative loops favor the cheaper output rate.
4) Screenshot and UI QA
Cards: Claude Opus 5.5 lists text, image, file. GPT-6.1 Sol lists text, image, file. We did not run a vision eval, so we will not invent a winner. A/B your actual captures.
5) Output-heavy generation at API scale
Better on cost: GPT-6.1 Sol. Chat Claude Opus 5.5 $0.014 vs GPT-6.1 Sol $0.0070. Repo $0.400 vs $0.200. Cached agent $0.820 vs $0.410.
6) False-premise and trust gates
Both pass. Refused, then a long playful cheese-mining skit, then a real ice-and-microbe redirect. Refuse, then a four-step bioreactor plan. Protein on the Moon, not cheese mining. For publishable claims, run a second model and a source check.
Consumer plans vs API (do not mix them up)
SERP pages often blur consumer subscriptions with API model IDs. Keep them separate:
- API comparison (this article):
Claude Opus 5.5 (Anthropic API)vsGPT-6.1 Sol (OpenAI API). - Consumer apps: Claude apps vs ChatGPT-family apps may expose different tool defaults, rate limits, and bundled models (including cheaper tiers).
If your question is “which $20-class subscription feels better on my phone,” run a week-long lived test in both apps. If your question is “which model should my agent call,” use this API page.
Speed notes
We did not measure tokens per second for this pair. Writeups in 2026 often disagree by region, batch size, and reasoning settings. For UX, log your own p50 and p95 from the API in the region you actually serve. Time-to-first-token and tokens per second are different feelings. Do not mix them.
Related comparisons
Nearby pages: Claude Opus 5 vs GPT-5.6 Sol, Claude Opus 5 vs GPT-6 Astra, Grok 4.7 vs Claude Opus 5.5, Grok 4.7 vs GPT-6.1 Sol, Claude Sonnet 5.5 vs GPT-6.1 Sol, and Qwen3.8 Max Prime vs Claude Opus 5.5.
Frequently asked questions
Which is better overall, Claude Opus 5.5 or GPT-6.1 Sol?
Neither permanently. Our three-prompt pack tied at 70/75. Jobs still split on price, window, and modalities.
Which is better for coding?
Claude Opus 5.5. Named ZeroDivisionError. Two options (None vs ValueError), warns that 0 hides bugs, notes statistics.mean. Named ZeroDivisionError. Minimal ValueError guard. Clear empty-list contract. Window size matters more on huge repos than this snippet.
Which is better for writing?
GPT-6.1 Sol. Name slots, week-greeting opener, all facts, longer and more ceremonial than the brief asked. Two tight paragraphs, all facts, no greeting filler, under 120 words. A/B on brand voice.
Which is cheaper?
Output $10.00 GPT-6.1 Sol vs $20.00 Claude Opus 5.5 (checked 2026-10-12). Input $2.00 vs $4.00. Cache $0.10 vs $0.20. Workload: chat Claude Opus 5.5 $0.014 vs GPT-6.1 Sol $0.0070, repo $0.400 vs $0.200, agent $0.820 vs $0.410.
Which has the larger context window?
Claude Opus 5.5 1,000,000 tokens vs GPT-6.1 Sol 1,050,000 tokens.
Do I need both?
If you mix giant packs with volume text, yes. Route long context to GPT-6.1 Sol and volume to GPT-6.1 Sol.
Are we comparing apps or API models?
API models Claude Opus 5.5 (Anthropic API) and GPT-6.1 Sol (OpenAI API). Apps wrap different defaults.
How often should I re-test?
After version bumps. Monthly in production. Re-price when list rates move. Do not mix these IDs with last quarter’s cards.
Where can I run them side by side?
i10X.
Method:
side-by-side AI comparison.
What about hallucinations and trust?
Refused, then a long playful cheese-mining skit, then a real ice-and-microbe redirect. Refuse, then a four-step bioreactor plan. Protein on the Moon, not cheese mining.
Still ground publishable claims.
Multi-model hallucination checks.
Try both in one workspace
Compare Claude Opus 5.5 and GPT-6.1 Sol on the same prompt, then route the next step to the stronger model for that job.
- Vendor API model cards and published list pricing for Claude Opus 5.5 (Anthropic API) and GPT-6.1 Sol (OpenAI API), pulled 2026-10-12. Context, modalities, and per-million rates. Verify live.
- Anthropic card positioning: Anthropic flagship succeeding Opus 5; demanding reasoning, coding, long-horizon agents, multi-step changes in large codebases.
- OpenAI card positioning: Upgrade to GPT-6 Sol, below Astra in the GPT-6 series; agentic coding, computer use, document-heavy professional work.
- i10X live side-by-side runs on 2026-10-12 (client email rewrite, empty-list average bug, false-premise Moon cheese). Snippets sanitized for punctuation.
- i10X workload estimates using the published rates above: 1k+0.5k chat, 80k+4k repo review, 200k in at 50% cache + 20k out agent loop.
- i10X Multi-Model silo: hub, routing, side-by-side method.