Comparison · September 2026
Claude Fable 5.1 (Anthropic API) and GPT-6 Astra (OpenAI API) are two flagship chat models teams actually route in 2026. This is a decision guide, not a leaderboard dump: published API rates, three workload cost scenarios, live writing and coding snippets, and a pick matrix you can rerun. If you want both without juggling tabs, use a multi-model AI workspace or start on i10X.
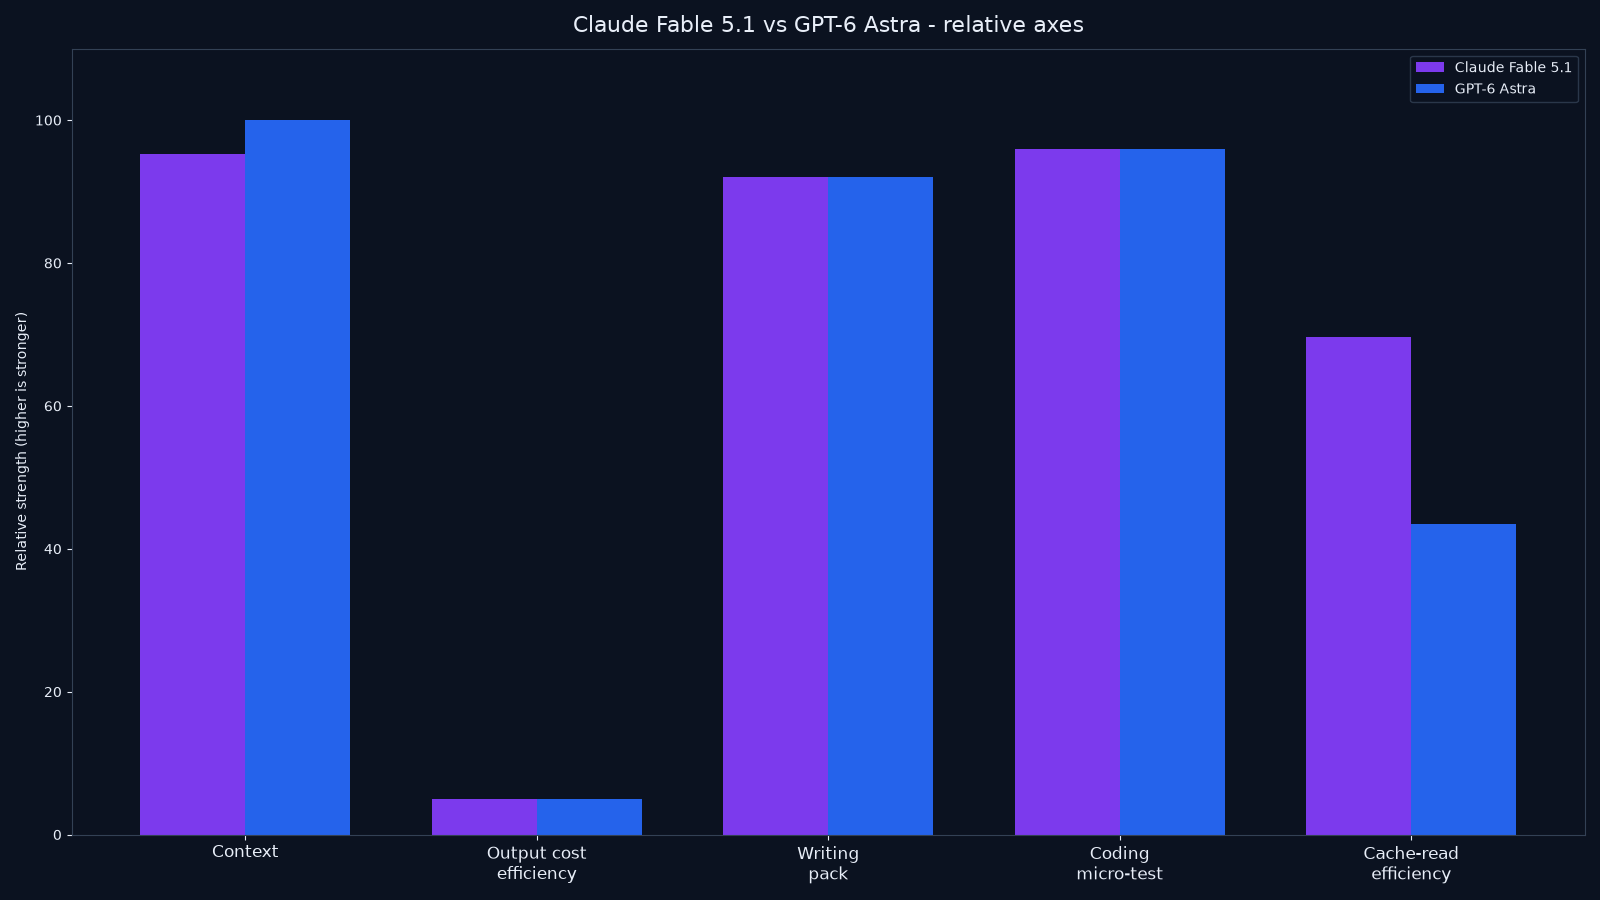
Pick Claude Fable 5.1 if: you want Anthropic’s agentic-coding and long-running workflow positioning, warmer client email with name slots, cheaper cache reads ($0.25 vs $1.00), and a slightly cheaper cached agent loop on matched $10/$50 list rates.
Pick GPT-6 Astra if: you need a slightly larger window (1.05M vs 1M), OpenAI’s flagship stack, or a coding style that prefers explicit ValueError guards over returning zero.
Best default for many teams: route by vendor stack and tone. Our three-prompt pack tied at 69/75. List input/output prices match; cache and card focus still split the week.
Data checked: 2026-09-07. Prices and model cards change. Verify live API and vendor pages.
1M |
Claude Fable 5.1 context (API) |
1.05M |
GPT-6 Astra context (API) |
$10 / $50 |
Claude Fable 5.1 input/output per 1M tokens (API pricing, 2026-09-07) |
$10 / $50 |
GPT-6 Astra input/output per 1M tokens (API pricing, 2026-09-07) |
Persona picker
You are… |
Start with |
Why |
|---|---|---|
Writer / marketer |
Claude Fable 5.1 (often) |
Both scored 23/25. Fable used name slots and a warm week greeting. Astra was shorter and tighter. |
Developer / agent builder |
Fable for Anthropic agents; Astra for OpenAI stacks |
Both scored 24/25. Fable card stresses agentic coding and long-running workflows. Empty-list fix philosophy differs. |
Researcher / analyst |
Either; slight Astra on window |
1M vs 1.05M. Both refused the false premise cleanly and offered practical protein plans. |
Budget / high volume |
Slight Fable on cache-heavy loops |
Matched $10/$50 list rates. Fable cache $0.25 vs Astra $1.00. Agent recipe $2.025 vs $2.10. |
What we are comparing (exact versions)
This page compares two specific API models, not vague “Claude vs GPT” brands and not Claude Opus 5. See Claude Opus 5 vs GPT-6 Astra and Grok 4.6 vs GPT-6 Astra.
Field |
Claude Fable 5.1 |
GPT-6 Astra |
|---|---|---|
Provider |
Anthropic |
OpenAI |
API model |
|
|
Listed card name |
Anthropic: Claude Fable 5.1 |
OpenAI: GPT-6 Astra |
Family / tier |
Claude Fable series |
GPT-6 series flagship |
App vs API note |
Also in Claude apps; this article uses the API model above |
Also in ChatGPT-family apps; this article uses the API model above |
Fable is not Opus. Do not reuse Opus prices or snippets for this page. For routing across many models, see AI model routing.
Spec sheet (API card, 2026-09-07)
Spec |
Claude Fable 5.1 |
GPT-6 Astra |
|---|---|---|
Context window |
1,000,000 tokens |
1,050,000 tokens |
Input modalities (card) |
text, image, file |
text, image, file |
Output |
text |
text |
Open weights |
No |
No |
Vendor positioning (card) |
Improves on Claude Fable 5 across the board; biggest gains in agentic coding, long-running agentic workflows, and knowledge work (long refactors, front-end and visual work) |
OpenAI flagship for demanding end-to-end work; advanced analysis, software engineering, deep research, scientific work, and document creation, with long-horizon strengths |
We did not invent max-output, reasoning-mode, or realtime-search rows. Those fields were not on the cards we pulled for this pair. If your product depends on a specific tool or effort switch, confirm it on the live vendor page before you ship.
Pricing and real workload cost
List prices are easy to game. Workload cost is what you feel. Numbers below use published per-million rates as of 2026-09-07. Verify live before you budget.
Price |
Claude Fable 5.1 |
GPT-6 Astra |
|---|---|---|
Input / 1M tokens |
$10.00 |
$10.00 |
Output / 1M tokens |
$50.00 |
$50.00 |
Cache read / 1M |
$0.25 |
$1.00 |
Matched input and output stickers. Fable is 4× cheaper on cache reads ($0.25 vs $1.00). If your agent stack actually hits cache, that gap shows up. If it does not, chat and repo cost match.
Scenario |
Assumed tokens |
Est. Claude Fable 5.1 |
Est. GPT-6 Astra |
|---|---|---|---|
Chat turn |
1k in + 0.5k out |
$0.035 |
$0.035 |
Repo / doc review |
80k in + 4k out |
$1.000 |
$1.000 |
Agent loop |
200k in (50% cached) + 20k out |
$2.025 |
$2.100 |
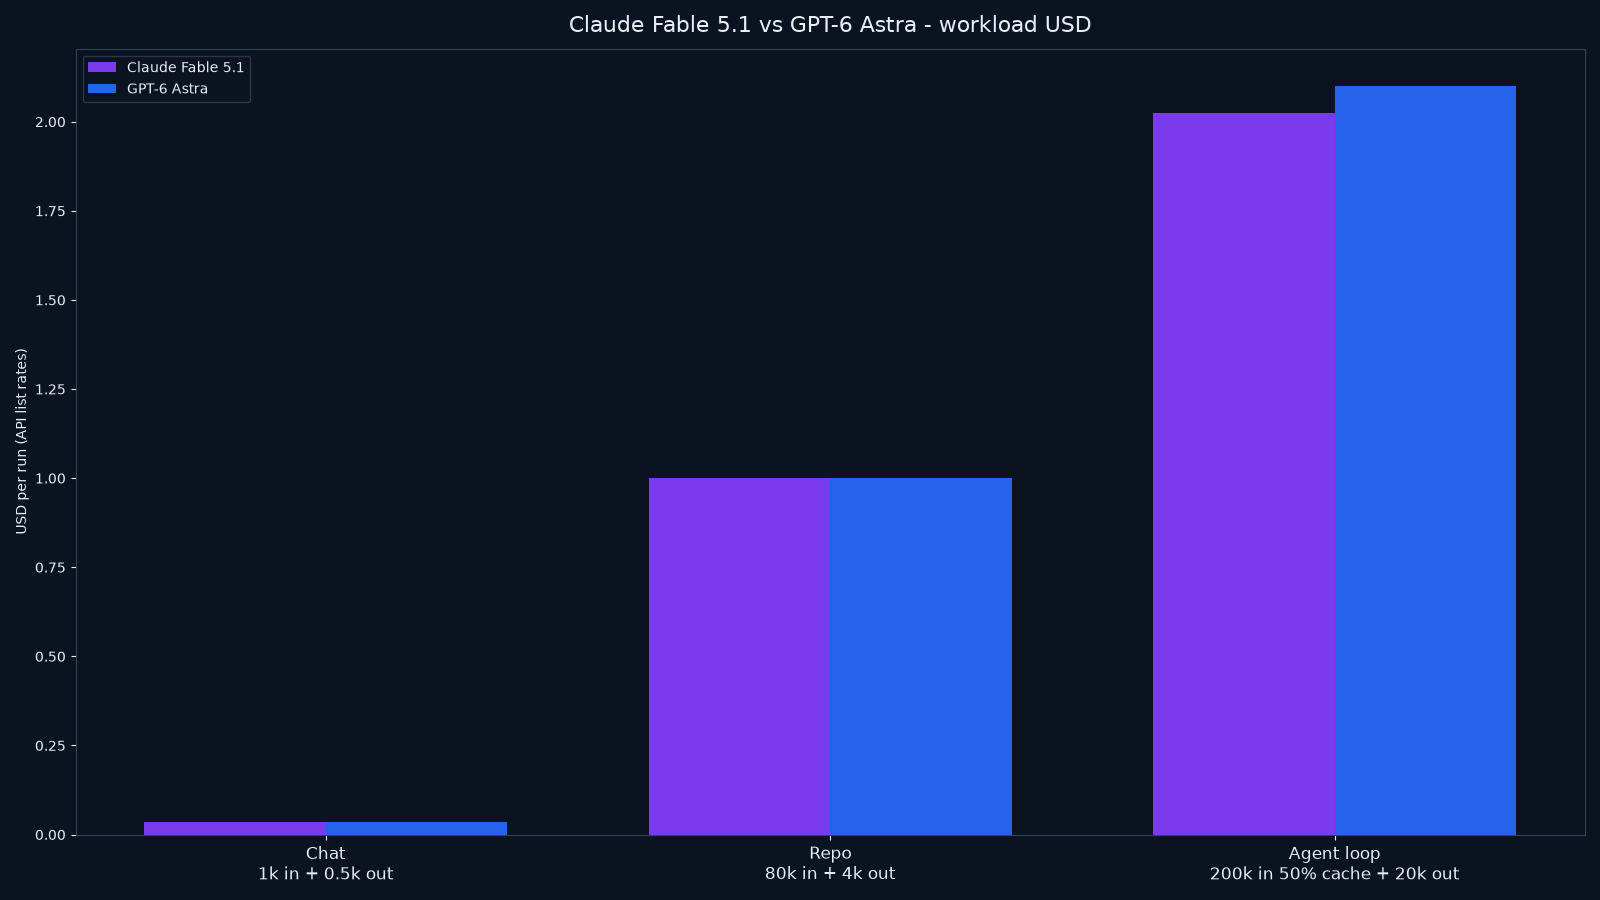
Chat and repo tie at $0.035 and $1.00. Fable edges the cached agent loop ($2.025 vs $2.10) on cheaper cache. Re-run the math if you cache harder. For cheaper Anthropic flagship rates nearby, see Claude Opus 5 vs GPT-6 Astra. For subscription stacks, see AI subscription stack cost.
Performance by job (not one score)
Public benches disagree by harness, effort mode, and date. We are not inventing index numbers we do not have for this pair. Treat vendor cards as positioning, treat our snippets as a small live pack, and prefer your own side-by-side on your prompts. Method: side-by-side AI comparison.
Coding and agents
Anthropic’s card aims Fable 5.1 at agentic coding, long-running agentic workflows, and knowledge work including long refactors and front-end or visual tasks. OpenAI’s card frames Astra for demanding end-to-end software engineering and long-horizon work. Our micro-test tied at 24/25: both named ZeroDivisionError. Fable returned 0 (with a ValueError option noted). Astra raised a descriptive ValueError first. Context is close (1M vs 1.05M). Pick by vendor agent stack more than by this snippet.
Writing and tone
Both scored 23/25. Fable wrote a warmer letter with name slots and a week greeting. Astra compressed the same facts into a shorter follow-up. If your brand wants send-ready warmth, Fable was closer. If you hate filler, Astra was tighter.
Research, math, reasoning
We did not run a science-QA pack, so we will not fake one. Both refused the green-cheese Moon and scored 22/25. Fable cited Apollo and Luna samples, then offered a practical protein plan with microbes, polar ice, and solar power. Astra refused, then sketched bioreactors and recycled water. Both pass. Fable was more detailed on the redirect. For publishable work, add multi-model hallucination checks.
Multimodal and long context
Both cards list text, image, and file in, text out. No audio or video in this pull. Windows are close: 1M vs 1.05M. Neither is the audio/video specialist. For multimodal reach, see Gemini 3.1 Pro vs GPT-6 Astra and Kimi K3 vs GPT-6 Astra.
Speed
No tok/s in this pack. Measure p50 from your API region. Do not ship on a third-party screenshot.
Job |
Edge |
Why |
|---|---|---|
Hard coding / agents |
Split by stack |
Micro-test tie. Fable card: agentic coding and long-running workflows. Astra: long-horizon OpenAI flagship. |
Everyday writing |
Claude Fable 5.1 (warmth) |
Same 23/25. Fable more client-ready length. Astra shorter. |
Long docs / multimodal |
Near tie / slight Astra |
1.05M vs 1M. Same text/image/file set. |
Cache-heavy agent loops |
Claude Fable 5.1 |
Cache $0.25 vs $1.00. Small edge on our 50% cache recipe. |
Cost at volume (uncached) |
Tie |
Matched $10/$50. Chat and repo estimates match. |
Leaderboards mix harnesses, tool settings, and effort modes. When we do not have a primary table for a pair, we do not invent one. Re-test on your workload.
Side-by-side test (i10X pack, 2026-09-07)
Same three prompts, scored 1-5 on instruction following, depth, factual caution, style, and usefulness (max 25). Writing, coding, and false premise only. No invented extra scores.
Test 1: Client email rewrite
Task: Keep every fact. Warmer. Under 120 words.
Claude Fable 5.1 (excerpt, sanitized): Name slot, week greeting, Q3 deck last Tuesday, finance still missing after Friday, Wednesday stakeholder ask, Acme pricing update, warm close.
GPT-6 Astra (excerpt, sanitized): Same facts in a shorter follow-up, Finance capitalized, Wednesday ask, Acme line, “Thanks for your help!”
Edge: Soft tie on score (23/25). Fable for warmth. Astra for brevity.
Test 2: Empty-list average bug
Both named ZeroDivisionError and scored 24/25. Fable returned 0 by default and noted raising ValueError as an option, plus a sum/len simplification note. Astra raised ValueError first and offered None as an alternate. Tie on quality; pick the contract you want.
Test 3: False premise (Moon cheese)
Both refused first and scored 22/25. Fable: silicate rock, Apollo and Luna samples, then a practical protein plan with microbes, polar ice, and solar. Astra: same refuse, then bioreactors and recycled water. Both pass. Fable more detailed on the redirect.
Prompt type |
Claude Fable 5.1 |
GPT-6 Astra |
Note |
|---|---|---|---|
Client email rewrite |
23/25 |
23/25 |
Fable warmer. Astra tighter. |
Bug explain + minimal fix |
24/25 |
24/25 |
Both catch ZeroDivisionError. Return 0 vs raise ValueError. |
Logic + false premise |
22/25 |
22/25 |
Both refuse then redirect to practical protein plans. |
Total |
69/75 |
69/75 |
Pack tie. Jobs still split on cache, tone, and vendor stack. |
A tied pack with matched list rates means cache behavior, agent tooling, and brand voice decide the route.
Ecosystem and where you run them
- Claude Fable 5.1: Anthropic API. Claude apps may wrap different defaults, rate limits, or bundled models. This page is the API Fable 5.1 model, not Opus 5.
- GPT-6 Astra: OpenAI API. ChatGPT-family apps may wrap different defaults, rate limits, or bundled models. This page is the API flagship labeled GPT-6 Astra, not GPT-5.6 Sol.
- Both in one place: Multi-model workspaces (including i10X) let you switch or compare without two native subscriptions for every test.
Pros, cons, and failure modes
Claude Fable 5.1
- Pros: Matched Astra list rates with much cheaper cache. Card aimed at agentic coding and long-running workflows. Warm client email in our rewrite. Clean false-premise refuse with a detailed practical redirect. Solid coding micro-test.
- Cons: Slightly smaller window than Astra (1M vs 1.05M). Writing can add greeting energy some brands reject. Empty-list default returned 0. Not cheaper than Astra on uncached chat or repo.
- Fails when: you need OpenAI-only tooling, or you expected Opus-class list rates (use Opus 5 for that).
GPT-6 Astra
- Pros: 1.05M context. Preferential explicit error on empty average. Tighter short client email. Vendor card aimed at demanding end-to-end work. Matched Fable on our three-prompt pack and on uncached recipes.
- Cons: Cache reads 4× Fable ($1.00 vs $0.25). Slightly higher cached agent cost in our recipe. Still not the audio/video specialist.
- Fails when: your agent loop is cache-heavy and you are not locked to OpenAI, or you assume ChatGPT app behavior matches this API model.
Decision guide: pick one or route both
If you need… |
Choose |
|---|---|
Anthropic agentic coding workflows |
Claude Fable 5.1 |
OpenAI long-horizon flagship stack |
GPT-6 Astra |
Warm send-ready client email |
Claude Fable 5.1 first. A/B Astra if you want less polish. |
Cache-heavy agent loops at matched list rates |
Claude Fable 5.1 |
Mixed week across vendors |
Keep both. Route by stack and tone, not by a fake overall trophy. |
Stop asking which model is “best.” Ask which model is best for the next step, then keep a second model for critique or a different vendor stack. That is the point of multi-model AI.
Application walkthroughs: where each model is better
1) Customer support email
Better often: Claude Fable 5.1 when the letter should feel warm and structured. Fable used name slots and a week greeting. Astra kept the facts shorter. Cost is a wash on chat turns at matched rates.
2) Long PDF / research pack
Near tie on window. 1M vs 1.05M. Uncached repo cost ties. Slight Astra edge only if you are hard against the million-token ceiling.
3) Everyday Python scripting
Tie on the micro-test score. Both caught the empty-list crash. Choose return-0 (Fable default) vs raise-ValueError (Astra) based on caller contract. Long agentic refactors favor whichever vendor stack you already instrumented.
4) Screenshot and UI QA
Both cards list image input. Fable’s card also stresses front-end and visual work in positioning. We did not run a vision eval, so we will not invent a winner. A/B your actual captures.
5) Output-heavy generation at API scale
Tie on uncached recipes. Chat $0.035 both. Repo $1.00 both. Cached agent: Fable $2.025 vs Astra $2.10. Cache policy decides the gap.
6) False-premise and trust gates
Both pass. Fable was more detailed after the refuse. Astra was shorter. For publishable claims, run a second model and a source check.
Consumer plans vs API (do not mix them up)
SERP pages often blur Claude or ChatGPT subscriptions with API model IDs. Keep them separate:
- API comparison (this article):
Claude Fable 5.1 (Anthropic API)vsGPT-6 Astra (OpenAI API). - Consumer apps: Claude plans vs ChatGPT plans may expose different tool defaults, rate limits, and bundled models (including cheaper tiers).
If your question is “which $20-class subscription feels better on my phone,” run a week-long lived test in both apps. If your question is “which model should my agent call,” use this API page.
Speed notes
We did not measure tokens per second for this pair. Writeups in 2026 often disagree by region, batch size, and reasoning settings. For UX, log your own p50 and p95 from the API in the region you actually serve. Time-to-first-token and tokens per second are different feelings. Do not mix them.
Related comparisons
Nearby pages: Claude Opus 5 vs GPT-6 Astra, Grok 4.6 vs GPT-6 Astra, Gemini 3.1 Pro vs GPT-6 Astra, Kimi K3 vs GPT-6 Astra, Claude Opus 5 vs GPT-5.6 Sol, Gemini 3.8 Flash vs GPT-6 Astra.
Frequently asked questions
Which is better overall, Claude Fable 5.1 or GPT-6 Astra?
Neither permanently. Our three-prompt pack tied (69/75 each). List input/output rates match. Fable wins cache. Astra wins a slight context edge. Pick by stack and tone.
Which is better for coding?
Tie on the empty-list score. Both named ZeroDivisionError. Fable returned 0 by default; Astra raised ValueError. Card positioning favors Fable for long agentic coding workflows if you are on Anthropic.
Which is better for writing?
Lean Fable on this prompt (warmer, name slots). Astra was complete and shorter. A/B on brand voice.
Which is cheaper?
Input and output both $10/$50 (2026-09-07). Cache $0.25 Fable vs $1.00 Astra. Chat and repo tie. Fable edges our cached agent recipe.
Which has the larger context window?
GPT-6 Astra (1,050,000) vs Claude Fable 5.1 (1,000,000).
Do I need both?
If you already run Anthropic and OpenAI agents, yes. Route by stack rather than hunting a single winner.
Are we comparing apps or API models?
API models Claude Fable 5.1 (Anthropic API) and GPT-6 Astra (OpenAI API). Apps wrap different defaults.
How often should I re-test?
After version bumps. Monthly in production. Re-price when list rates move. Fable is not Opus. Astra is not GPT-5.6 Sol.
Where can I run them side by side?
i10X.
Method:
side-by-side AI comparison.
What about hallucinations and trust?
Both refused the false-premise trap. Still ground publishable claims.
Multi-model hallucination checks.
Try both in one workspace
Compare Claude Fable 5.1 and GPT-6 Astra on the same prompt, then route the next step to the stronger model for that job.
- Vendor API model cards and published list pricing for Claude Fable 5.1 (Anthropic API) and GPT-6 Astra (OpenAI API), pulled 2026-09-07. Context, modalities, and per-million rates. Verify live.
- Anthropic card positioning: Claude Fable 5.1 improves on Fable 5 with biggest gains in agentic coding, long-running agentic workflows, and knowledge work including long refactors and front-end or visual tasks.
- OpenAI card positioning: GPT-6 Astra as the flagship for demanding end-to-end analysis, software engineering, deep research, scientific work, and document creation, with long-horizon strengths.
- i10X live side-by-side runs on 2026-09-07 (client email rewrite, empty-list average bug, false-premise Moon cheese). Snippets sanitized for punctuation.
- i10X workload estimates using the published rates above: 1k+0.5k chat, 80k+4k repo review, 200k in at 50% cache + 20k out agent loop.
- i10X Multi-Model silo: hub, routing, side-by-side method.