Comparison · September 2026
Claude Sonnet 5 (Anthropic API) and GPT-6 Astra (OpenAI API) are two models teams actually route in 2026. This is a decision guide, not a leaderboard dump: published API rates, three workload cost scenarios, live writing and coding snippets, and a pick matrix you can rerun. If you want both without juggling tabs, use a multi-model AI workspace or start on i10X.
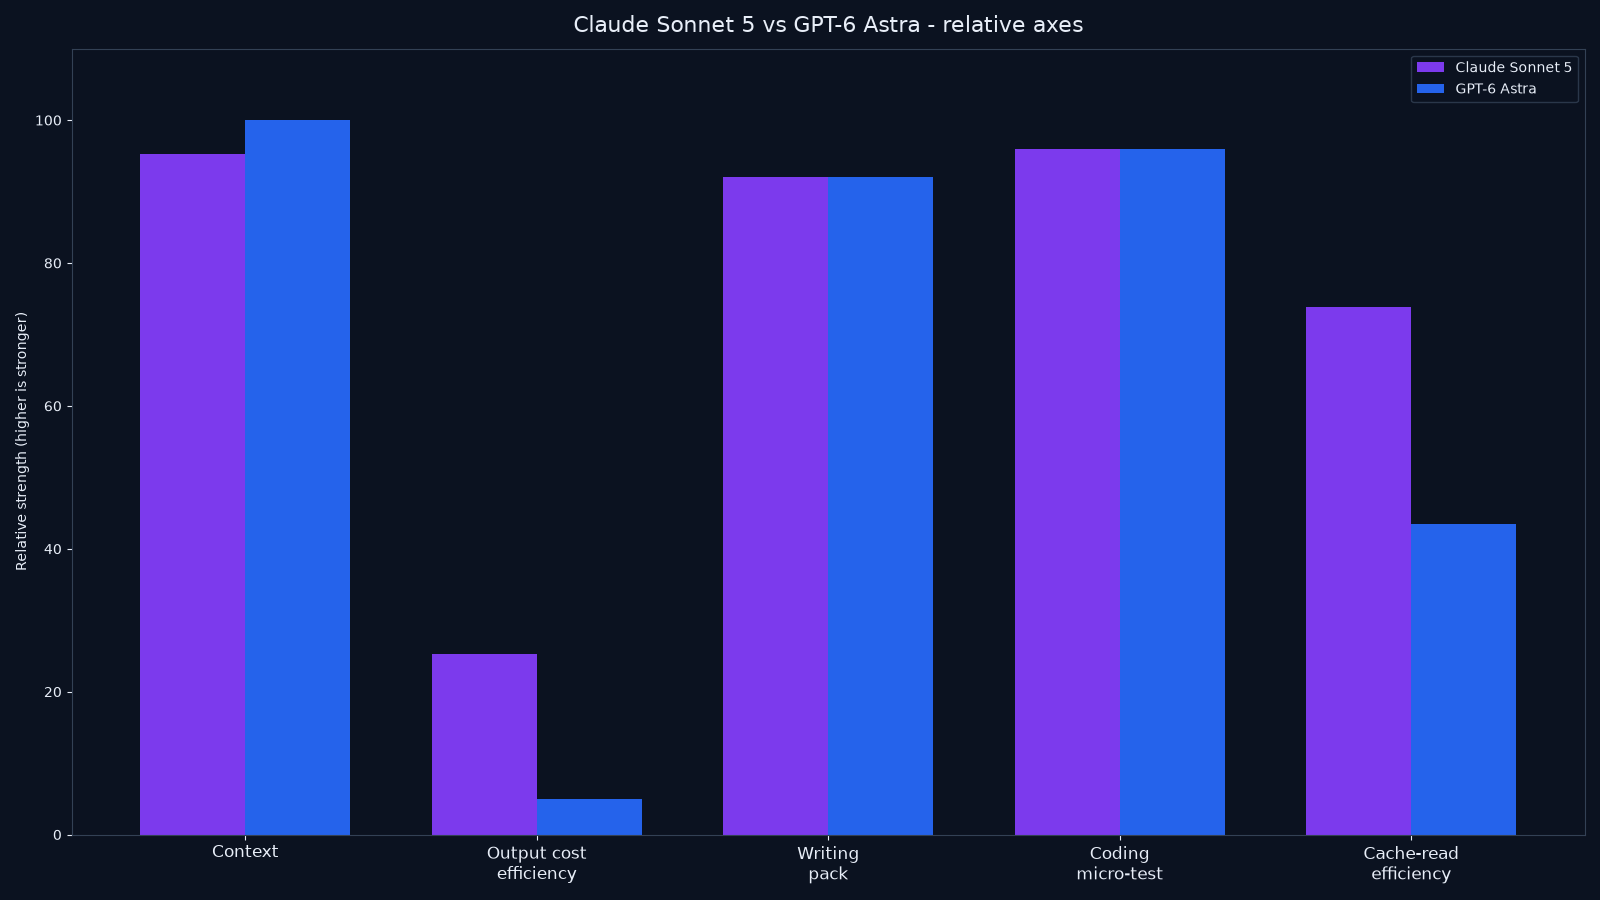
Pick Claude Sonnet 5 if: you want Anthropic Sonnet-class frontier coding and professional work at $2 / $10, adaptive thinking effort levels on the card, ~1M context, and much cheaper workloads than Astra.
Pick GPT-6 Astra if: you want OpenAI’s GPT-6 flagship for the hardest end-to-end analysis and research narratives, and budget allows $10 / $50.
Best default for many teams: route by task and keep both available. See the decision matrix below.
Data checked: 2026-09-07. Prices and model cards change. Verify live API test and vendor pages.
1M |
Claude Sonnet 5 context (API) |
1.05M |
GPT-6 Astra context (API) |
$2 / $10 |
Claude Sonnet 5 input/output per 1M tokens (API pricing, 2026-09-07) |
$10 / $50 |
GPT-6 Astra input/output per 1M tokens (API pricing, 2026-09-07) |
Persona picker
You are… |
Start with |
Why |
|---|---|---|
Writer / marketer |
Either (23/25); Claude for warmer named tone |
Claude wrote a warm named follow-up with breathing-room language. Astra was shorter. Same score. |
Developer / agent builder |
Either for everyday bugs; split on ecosystem |
Micro-test tied 24/25. Claude discussed 0 / None / ValueError options. Astra led with ValueError. |
Researcher / analyst |
Split; windows nearly matched |
1M Claude vs 1.05M Astra. Astra’s card stresses deep research; Claude’s card stresses Sonnet-class professional work with adaptive thinking. |
Budget / high volume |
Claude Sonnet 5 |
Large gap vs Astra on chat, repo, and cached agent estimates. |
What we are comparing (exact versions)
This page compares two specific API models, not vague brand labels. Sibling GPT-6 Astra pairs live in the related list below. For routing across many models, see AI model routing.
Field |
Claude Sonnet 5 |
GPT-6 Astra |
|---|---|---|
Provider |
Anthropic |
OpenAI |
API model |
|
|
Listed card name |
Anthropic: Claude Sonnet 5 |
OpenAI: GPT-6 Astra |
Family / tier |
Anthropic Claude Sonnet 5 (most capable Sonnet-class) |
OpenAI GPT-6 flagship (Astra) |
App vs API note |
Also in Claude apps; this article uses the API model above |
Also in ChatGPT-family apps; this article uses the API model above |
If a page still compares older IDs as if they were these models, treat it as historical.
Spec sheet (API card, 2026-09-07)
Spec |
Claude Sonnet 5 |
GPT-6 Astra |
|---|---|---|
Context window |
1,000,000 tokens |
1,050,000 tokens |
Input modalities (card) |
text, image, file |
file, image, text |
Output |
text |
text |
Open weights |
No |
No |
Vendor positioning (card) |
Most capable Sonnet-class model; frontier performance across coding, agents, and professional work; adaptive thinking with selectable reasoning effort levels |
OpenAI flagship for demanding end-to-end work: advanced analysis, software engineering, deep research, scientific work, and document creation, with long-horizon strengths |
We did not invent max-output, tok/s, or leaderboard rows. Those fields were not used for this pair. If your product depends on a specific tool or effort switch, confirm it on the live vendor page before you ship.
Pricing and real workload cost
List prices are easy to game. Workload cost is what you feel. Numbers below use published per-million rates as of 2026-09-07. Verify live before you budget.
Price |
Claude Sonnet 5 |
GPT-6 Astra |
|---|---|---|
Input / 1M tokens |
$2 |
$10 |
Output / 1M tokens |
$10 |
$50 |
Cache read / 1M |
$0.2 |
$1 |
Sonnet 5 is mid-premium ($2 / $10). Astra is ultra-premium ($10 / $50). Cache $0.20 vs $1.00.
Scenario |
Assumed tokens |
Est. Claude Sonnet 5 |
Est. GPT-6 Astra |
|---|---|---|---|
Chat turn |
1k in + 0.5k out |
$0.007 |
$0.035 |
Repo / doc review |
80k in + 4k out |
$0.2 |
$1 |
Agent loop |
200k in (50% cached) + 20k out |
$0.42 |
$2.1 |
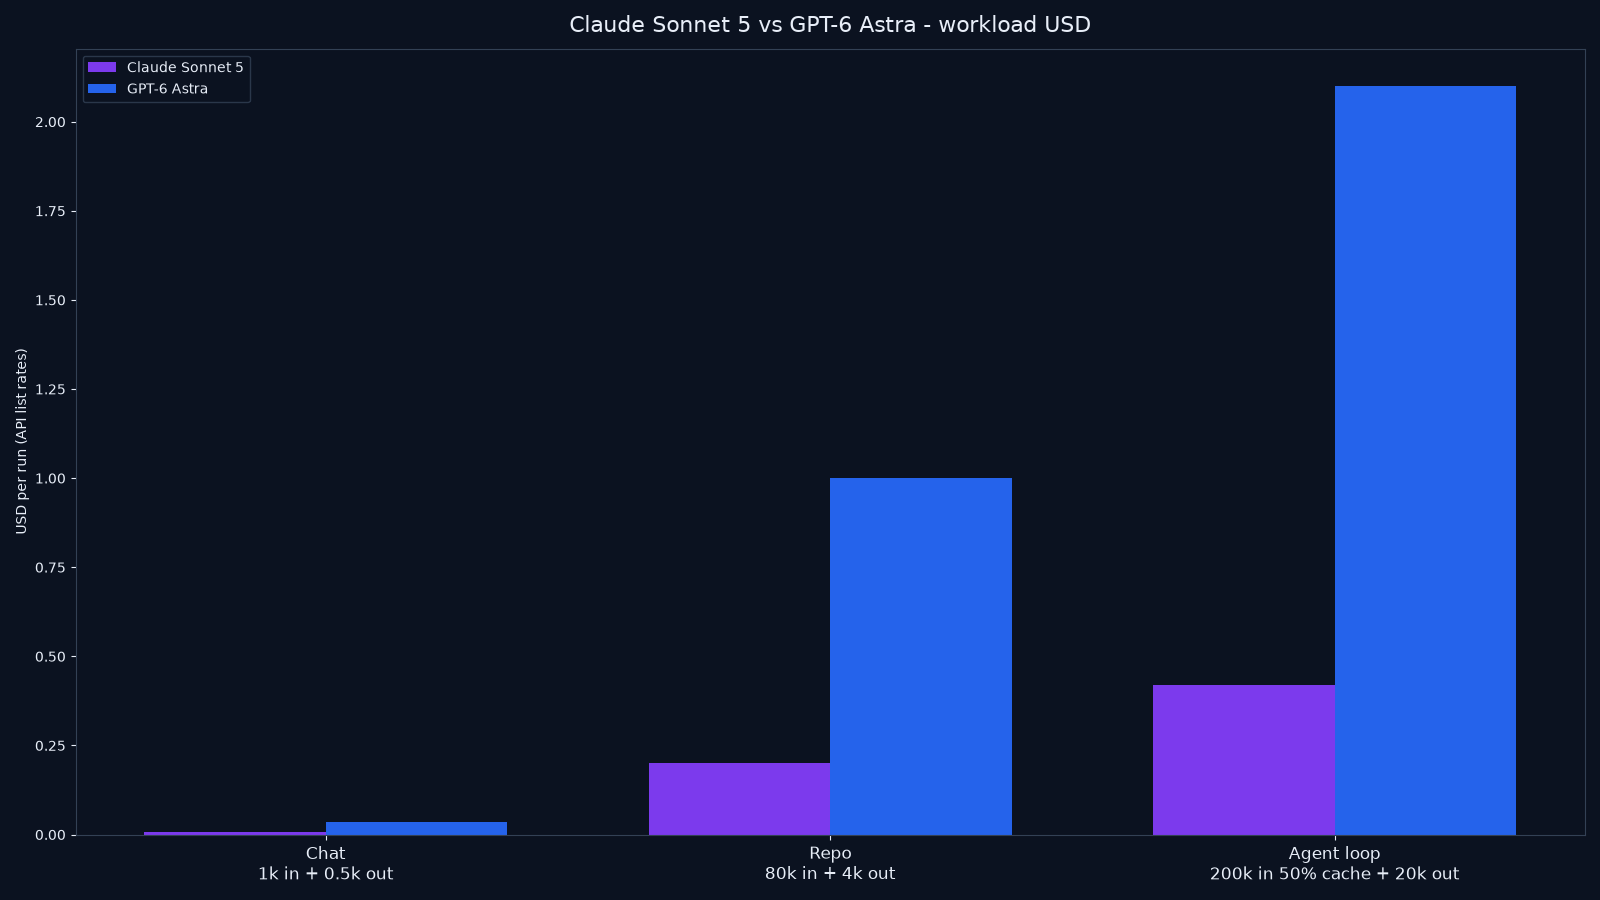
Claude wins the cached agent loop (~$0.42 vs $2.10) even though Astra’s cache is discounted versus Astra input. For subscription stacks, see AI subscription stack cost.
Performance by job (not one score)
Public benches disagree by harness, effort mode, and date. We are not inventing index numbers we do not have for this pair. Treat vendor cards as positioning, treat our snippets as a small live pack, and prefer your own side-by-side on your prompts. Method: side-by-side AI comparison.
Coding and agents
Tie at 24/25. Both named ZeroDivisionError. Claude outlined return 0, None, or ValueError (mirroring statistics.mean behavior as an option). Astra led with ValueError and mentioned None. Pick team conventions.
Writing and tone
Tie at 23/25. Claude: warm named letter with patience close. Astra: compressed follow-up. Both kept every fact under the limit.
Research, math, reasoning
Both refused the cheese Moon. Claude labeled the myth and offered a playful hypothetical plan. Astra redirected to bioreactors. Windows nearly match. For publishable work, add multi-model hallucination checks.
Multimodal and long context
Both list text, image, and file. No video/audio in this pull. Context: 1M vs 1.05M.
Speed
No tok/s in this pack. Measure p50 from your API region. Do not ship on a third-party screenshot.
Job |
Edge |
Why |
|---|---|---|
Hard coding / agents |
Split |
Micro-test tie. Ecosystem and effort-mode controls may decide. |
Everyday writing |
Split |
Same score. Claude warmer. Astra tighter. |
Long docs / multimodal |
Split |
1M vs 1.05M. Effectively matched for many packs. |
Realtime / conversational |
Product-dependent |
Claude and ChatGPT apps differ. Not measured on API tok/s. |
Cost at volume |
Claude Sonnet 5 |
Chat ~$0.007 vs $0.035. Repo ~$0.20 vs $1.00. Agent ~$0.42 vs $2.10. |
Leaderboards mix harnesses, tool settings, and effort modes. When we do not have a primary table for a pair, we do not invent one. Re-test on your workload.
Side-by-side test (i10X pack, 2026-09-07)
Same three prompts, scored 1-5 on instruction following, depth, factual caution, style, and usefulness (max 25). Writing, coding, and false premise only. No invented extra scores. Pack tied 69/75.
Test 1: Client email rewrite
Task: Keep every fact. Warmer. Under 120 words.
Claude Sonnet 5 (excerpt, sanitized): Hi there, warm hope-you-are-well, Q3 deck Tuesday, finance still missing, push stakeholders to next week maybe Wednesday, Acme pricing note, thanks for patience.
GPT-6 Astra (excerpt, sanitized): Short follow-up with the same operational facts.
Edge: Tie on score. Claude warmer. Astra more compact.
Test 2: Empty-list average bug
Tie 24/25. Both teach empty-list handling. Claude enumerates policy options more explicitly.
Test 3: False premise (Moon cheese)
Both pass at 22/25. Claude: myth note plus playful plan. Astra: practical protein plan.
Prompt type |
Claude Sonnet 5 |
GPT-6 Astra |
Note |
|---|---|---|---|
Client email rewrite |
23/25 |
23/25 |
Tie on score. Claude warmer. Astra more compact. |
Bug explain + minimal fix |
24/25 |
24/25 |
Tie 24/25. Both teach empty-list handling. Claude enumerates policy options more explicitly. |
Logic + false premise |
22/25 |
22/25 |
Both pass at 22/25. Claude: myth note plus playful plan. Astra: practical protein plan. |
Total |
69/75 |
69/75 |
Jobs still split on cost, context, and vendor fit. |
A writing or coding edge does not erase a cost or context win. Route the next step.
Ecosystem and where you run them
- Claude Sonnet 5: Anthropic API. Claude apps may expose different effort defaults. Card mentions adaptive thinking levels; confirm in your account.
- GPT-6 Astra: OpenAI API. ChatGPT apps may wrap different defaults. This page is GPT-6 Astra.
- Both in one place: Multi-model workspaces (including i10X) let you switch or compare without two native subscriptions for every test.
Pros, cons, and failure modes
Claude Sonnet 5
- Pros: $2 / $10 with ~1M context. Cache $0.20. Sonnet-class coding/agents card with adaptive thinking. Matched pack 69/75. Text/image/file.
- Cons: Not GPT-6 flagship positioning. Playful false-premise coda may need trimming for strict gates. Still pricier than flash models.
- Fails when: you standardize on OpenAI-only stacks, or you need Astra’s ultra-flagship narrative regardless of cost.
GPT-6 Astra
- Pros: GPT-6 flagship card. Tight writing. Clear coding style. 1.05M context. Strong practical redirect on false premises.
- Cons: $10 / $50 rates. Cache $1/M. Workloads several times Sonnet 5 in our recipes.
- Fails when: you already clear the bar on Sonnet 5 and only burn tokens at scale.
Decision guide: pick one or route both
If you need… |
Choose |
|---|---|
Sonnet-class pro work on a budget vs Astra |
Claude Sonnet 5 |
OpenAI GPT-6 flagship narrative |
GPT-6 Astra |
Adaptive thinking effort controls (card) |
Claude Sonnet 5; confirm live |
Send-ready short email |
Either; Claude warmer, Astra tighter |
Mixed week |
Keep both. Route everyday pro work to Sonnet 5. Keep Astra for OpenAI-standard flagship jobs. |
Stop asking which model is “best.” Ask which model is best for the next step, then keep a second model for critique or a different window size. That is the point of multi-model AI.
Application walkthroughs: where each model is better
1) Customer support email
Split. Claude warmer with name energy. Astra shorter. Cost favors Claude at volume.
2) Long PDF / research pack
Near tie on window. 1M vs 1.05M. Choose by vendor standard and effort controls.
3) Everyday Python scripting
Tie on the micro-test. Both solid. Align empty-list policy.
4) Screenshot and UI QA
Both list image and file. No vision eval here. A/B captures.
5) Output-heavy generation at API scale
Better on cost: Claude Sonnet 5. Still verify against flash tiers if volume explodes.
6) False-premise and trust gates
Both pass. Astra’s redirect is more practical. Claude’s playful plan needs a trim for strict policies.
Consumer plans vs API (do not mix them up)
SERP pages often blur consumer subscriptions with API model names. Keep them separate:
- API comparison (this article):
Claude Sonnet 5 (Anthropic API)vsGPT-6 Astra (OpenAI API). - Consumer apps: Claude.ai / Anthropic consumer plans vs ChatGPT-family plans may expose different tool defaults, rate limits, and bundled models.
If your question is “which subscription feels better on my phone,” run a week-long lived test in both apps. If your question is “which model should my agent call,” use this API page.
Speed notes
We did not measure tokens per second for this pair. Writeups in 2026 often disagree by region, batch size, and reasoning settings. For UX, log your own p50 and p95 from the API in the region you actually serve. Time-to-first-token and tokens per second are different feelings. Do not mix them.
Related comparisons
Nearby pages: Qwen3.8 Flash vs GPT-6 Astra, GLM 5.3 Flash vs GPT-6 Astra, Seed 2.1 Turbo vs GPT-6 Astra, Qwen3.8 Max 0902 vs GPT-6 Astra, Grok 4.20 vs GPT-6 Astra, Grok 4.6 vs GPT-6 Astra.
Frequently asked questions
Which is better overall, Claude Sonnet 5 or GPT-6 Astra?
Pack tied 69/75. Claude wins cost for Sonnet-class work. Astra wins GPT-6 flagship positioning. Pick by job and vendor standard.
Which is better for coding?
Tie (24/25). Ecosystem and effort modes may matter more than this snippet.
Which is better for writing?
Tie (23/25). Claude warmer. Astra tighter.
Which is cheaper?
Claude Sonnet 5 ($2 / $10 vs $10 / $50; cache $0.20 vs $1.00 on 2026-09-07).
Which has the larger context window?
GPT-6 Astra (1,050,000) vs Claude Sonnet 5 (1,000,000). Nearly matched.
Do I need both?
If you mix flagship jobs with volume or multimodal intake, yes. Route by task and keep a second model for critique.
Are we comparing apps or API models?
API models Claude Sonnet 5 (Anthropic API) and GPT-6 Astra (OpenAI API). Apps wrap different defaults.
How often should I re-test?
After version bumps. Monthly in production. Re-price when list rates move. Do not mix older GPT-5.x prices with GPT-6 Astra.
Where can I run them side by side?
i10X.
Method:
side-by-side AI comparison.
What about hallucinations and trust?
Both models faced the false-premise trap in our pack. Still ground publishable claims.
Multi-model hallucination checks.
Try both in one workspace
Compare Claude Sonnet 5 and GPT-6 Astra on the same prompt, then route the next step to the stronger model for that job.
- Vendor API model cards and published list pricing for Claude Sonnet 5 (Anthropic API) and GPT-6 Astra (OpenAI API), pulled 2026-09-07. Context, modalities, and per-million rates. Verify live.
- Anthropic card positioning: Most capable Sonnet-class model; frontier performance across coding, agents, and professional work; adaptive thinking with selectable reasoning effort levels.
- OpenAI card positioning: OpenAI flagship for demanding end-to-end work: advanced analysis, software engineering, deep research, scientific work, and document creation, with long-horizon strengths.
- i10X live side-by-side runs on 2026-09-07 (client email rewrite, empty-list average bug, false-premise Moon cheese). Snippets sanitized for punctuation.
- i10X workload estimates using the published rates above: 1k+0.5k chat, 80k+4k repo review, 200k in at 50% cache + 20k out agent loop.
- i10X Multi-Model silo: hub, routing, side-by-side method.