Comparison · August 2026
Gemini 3.7 Flash and Claude Sonnet 5 are the mismatch pair a lot of stacks still need: a cheap multimodal Flash SKU versus Anthropic’s most capable Sonnet. Flash is Google’s fast model for agentic work, coding, and mixed media. Sonnet 5 is the professional-work Claude with image and file input plus selectable reasoning effort. This is a decision guide, not a leaderboard dump: exact versions, published API rates, three workload costs, and a live side-by-side pack. Keep both in a multi-model AI workspace or start on i10X.
Pick Gemini 3.7 Flash if: you want audio and video on the card, a ~1M window, and Flash-tier rates. Our agent-loop estimate is $0.0788 vs Sonnet’s $0.42.
Pick Claude Sonnet 5 if: you want effort knobs (low, medium, high, max), Anthropic’s professional-work positioning, and the cleaner “already a letter” rewrite we saw in the live pack.
Best default for many teams: Flash for volume and media, Sonnet for brand-safe drafts and effort-controlled reasoning. Route. Do not crown a permanent overall winner.
Data checked: 2026-08-24. Prices and model cards change. Verify live API test and vendor pages.
1,048,576 |
Gemini 3.7 Flash context (API) |
1,000,000 |
Claude Sonnet 5 context (API) |
$0.375 / $1.875 |
Gemini 3.7 Flash input/output per 1M tokens (API pricing, 2026-08-24) |
$2 / $10 |
Claude Sonnet 5 input/output per 1M tokens (API pricing, 2026-08-24) |
Persona picker
You are… |
Start with |
Why |
|---|---|---|
Writer / marketer |
Claude Sonnet 5 (often) |
Sonnet’s rewrite read like a letter. Flash added greeting energy (“hope you’re having a great week”) around the same facts. |
Developer / agent builder |
Flash for cheap loops; Sonnet when you need effort max |
Both fixed the empty-list bug with |
Researcher / analyst |
Flash for audio/video; Sonnet for effort-controlled reading |
Context is close. Flash lists audio and video. Sonnet lists file and named effort. |
Budget / high volume |
Gemini 3.7 Flash |
$0.375/$1.875 vs $2/$10. Chat $0.0013 vs $0.0070. |
Need a runbook dial |
Claude Sonnet 5 |
Adaptive thinking with selectable effort is on the Sonnet card. Flash’s card in this pull does not name those knobs. |
What we are comparing (exact versions)
Multi-model AI means using more than one LLM in your stack. This page compares two specific API models, not Gemini 3.1 Pro and not Claude Opus 5.
Field |
Gemini 3.7 Flash |
Claude Sonnet 5 |
|---|---|---|
Provider |
Anthropic |
|
API model |
|
|
Listed API name |
Google: Gemini 3.7 Flash |
Anthropic: Claude Sonnet 5 |
Family / tier |
Gemini Flash (fast / volume) |
Most capable Sonnet-class model |
App vs API note |
Also in Gemini apps; this article uses the API model above, not Pro |
Also in Claude apps; this article uses the API model above, not Opus |
If a page still compares Gemini 2.5 Flash to Claude Sonnet 4, treat it as historical. For routing across many models, see AI model routing.
Spec sheet (API card, 2026-08-24)
Spec |
Gemini 3.7 Flash |
Claude Sonnet 5 |
|---|---|---|
Context window |
1,048,576 tokens |
1,000,000 tokens |
Max output (if published) |
Not published on this card |
Not published on this card |
Input modalities |
text, image, video, file, audio |
text, image, file |
Output |
text |
text |
Reasoning / effort modes |
Positioned for complex multi-step reasoning; effort knobs not listed on this card |
Adaptive thinking with selectable effort (low, medium, high, max) |
Realtime / search |
Not listed on this card; confirm tools in your app |
Not listed on this card; confirm tools in your app |
Open weights |
No |
No |
Vendor positioning (short) |
Fast agentic workflows, coding, complex multi-step reasoning; responsive performance |
Frontier Sonnet-class coding, agents, and professional work |
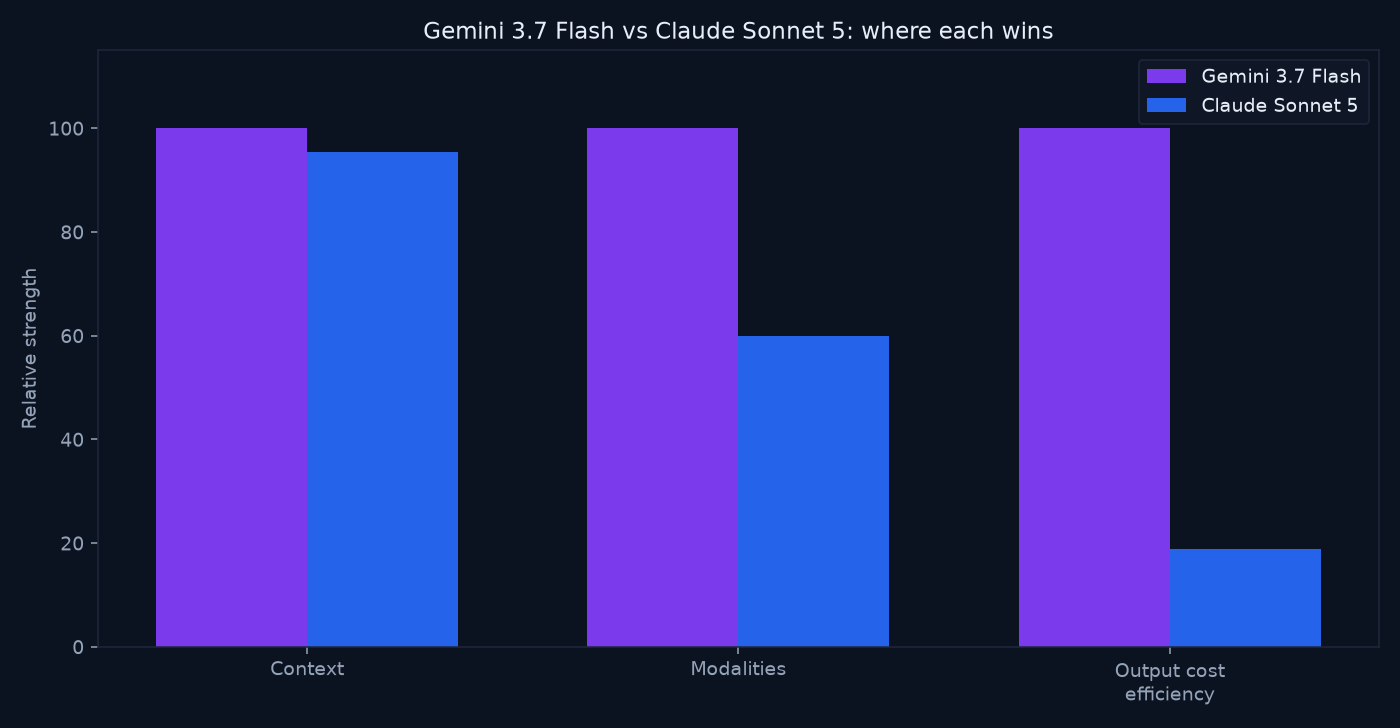
Figure 1 looks lopsided because context, modality count, and output-cost efficiency all lean Flash. Sonnet’s case is qualitative: effort control, Claude ecosystem, and live-test tone. Those are not bars on Figure 1.
Pricing and real workload cost
This is the largest price gap in this batch. Numbers below use published per-million rates as of 2026-08-24. Verify live before you budget. Output is $1.875 vs $10. That is the line that makes “always Sonnet” an expensive habit.
Price |
Gemini 3.7 Flash |
Claude Sonnet 5 |
|---|---|---|
Input / 1M tokens |
$0.375 |
$2.00 |
Output / 1M tokens |
$1.875 |
$10.00 |
Cache read / 1M |
$0.0375 |
$0.20 |
Scenario |
Assumed tokens |
Est. Gemini 3.7 Flash |
Est. Claude Sonnet 5 |
|---|---|---|---|
Chat turn |
1k in + 0.5k out |
$0.0013 |
$0.0070 |
Repo / doc review |
80k in + 4k out |
$0.0375 |
$0.20 |
Agent loop |
200k in (50% cached if available) + 20k out |
$0.0788 |
$0.42 |
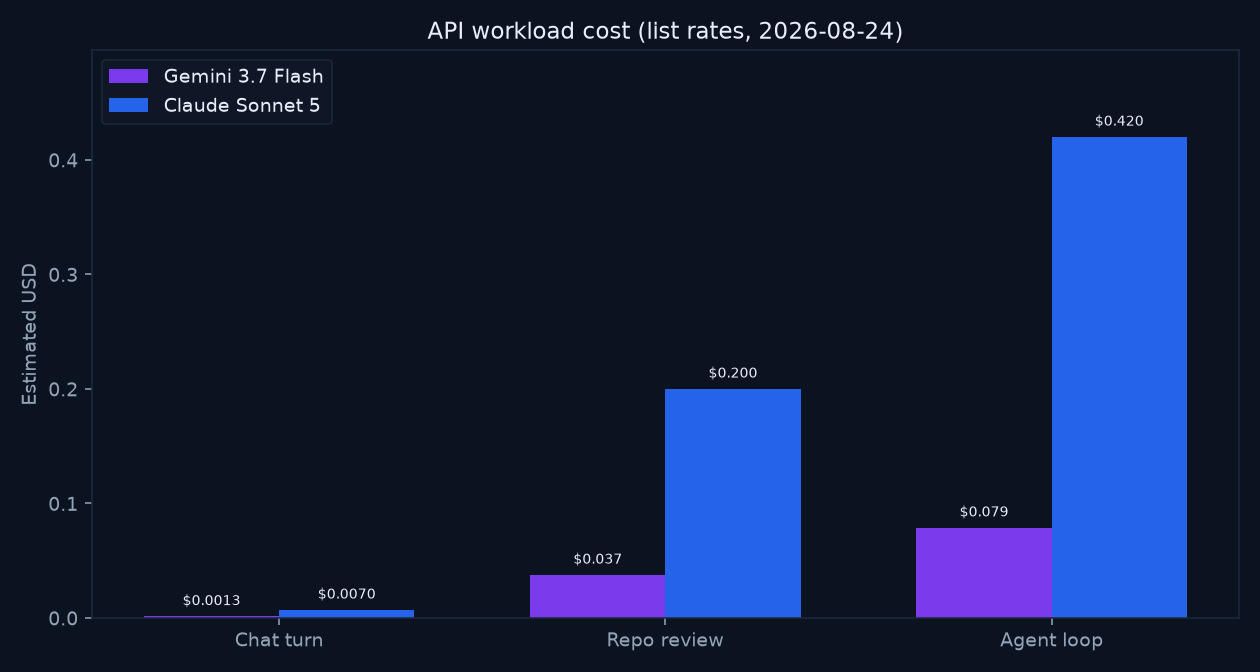
Chat, repo, and agent loop are all about 5x. Pinning cache on Sonnet does not close it. Use Sonnet when the step is worth 5x, not because you standardized on Claude. For seats vs API, see AI subscription stack cost.
Performance by job (not one score)
We are not inventing a Flash-vs-Sonnet public bench. Google pitches Flash as fast and agentic. Anthropic pitches Sonnet 5 as frontier Sonnet-class for coding, agents, and professional work. Those are different promises. Confirm with your prompts. Method: side-by-side AI comparison.
Coding and agents
The live bug was a tie on the fix. Both named ZeroDivisionError on empty nums. Both added if not nums: return 0. Sonnet’s comment offered ValueError as an alternative. That does not tell you who wins a 40-file refactor. It tells you this micro-task is not why you pay 5x. Pay Sonnet when the runbook says effort=max, when the ticket is merge-blocking, or when Flash retries more than the price gap. Otherwise Flash is the default agent SKU in this pair.
Writing and tone
Flash went warm: subject, “hope you’re having a great week,” complete facts including Acme. Sonnet went operational: subject about a reschedule, Finance missed Friday, Wednesday please, competitive slide still open. If your brand already sounds like Flash, keep Flash and save the 5x. If managers reject “having a great week” in a status mail, start on Sonnet. Taste is a real routing feature. It is not a benchmark.
Research, math, reasoning
No scored science set. On the false-premise trap, Flash refused and stayed with real ISRU (ice, oxygen, metals). Sonnet refused, named basalt/anorthosite and a giant impact, then offered a playful “mining cheese” coda. Both pass the refuse. Flash is cleaner inside an agent that should not entertain the joke. Sonnet is the model you can turn up to max when the pack is actually hard; we did not score those effort levels here. For publishable claims, still use multi-model hallucination checks.
Multimodal and long context
Context is close (1,048,576 vs 1,000,000). Inputs are not. Flash: text, image, video, file, audio. Sonnet: text, image, file. Route recordings and clips to Flash. Route PDFs and screenshots to whoever wins your quality eval; both cards list those, and Flash is cheaper. Sonnet still wins if the file loop lives in Claude Projects and switching tools costs more than tokens.
Speed
Flash is named Flash. We still did not publish tok/s. Sonnet on max effort will not behave like Flash on a default. Measure the setting you will ship, from your region.
Job |
Edge |
Why |
|---|---|---|
Hard coding / agents |
Flash on cost; Sonnet when effort=max matters |
Live bug tied. Sonnet card names effort levels. |
Everyday writing |
Sonnet for operational letters; Flash for warmer notes |
Same facts; different cadence in the live rewrite. |
Long docs / multimodal |
Flash for audio/video; split on files |
Flash lists two extra inputs. Context close. |
Realtime / conversational |
Not scored here |
Flash pitches responsive performance; we did not cite tok/s. |
Cost at volume |
Gemini 3.7 Flash |
About 5x cheaper on the three workloads we priced. |
A 5x price gap is a routing bug if quality is tied. It is a bargain if Sonnet prevents one incident. Re-test on the jobs that actually fail. That is multi-model AI.
Side-by-side test (i10X pack, 2026-08-24)
We ran the same three prompts on Gemini 3.7 Flash and Claude Sonnet 5 and scored 1-5 on instruction following, depth, factual caution, style, and usefulness (max 25 per prompt). Excerpts are sanitized and truncated. Add a long-paste summary and a refuse-if-unknown research prompt in your workspace; those were not in this capture.
Test 1: Client email rewrite
Task: Keep every fact. Warmer. Short enough to send.
Gemini 3.7 Flash (excerpt): Subject “Update on Q3 Deck & Stakeholder Meeting.” Greeting energy. Last Tuesday’s deck. Finance expected Friday, still waiting. Competitive slide needs new Acme pricing. Ask to push to next week / Wednesday.
Claude Sonnet 5 (excerpt): Subject “Q3 Deck Update & Meeting Reschedule Request.” Direct follow-up. Finance promised Friday, nothing through. Push to next Wednesday so finance has time. Competitive slide still needs work. No extra cheer.
Edge: Taste. Flash warmer and named Acme in the capture. Sonnet more operational, less greeting.
Test 2: Empty-list average bug
Both named ZeroDivisionError and shipped if not nums: return 0. Sonnet noted ValueError as an optional strict path. Tie on the micro-task.
Test 3: False premise (Moon cheese)
Both refused. Flash stayed with real geology and real mining. Sonnet added a playful coda after a clean refuse. Both pass the refuse. Flash slightly cleaner for agents.
Prompt type |
Gemini 3.7 Flash |
Claude Sonnet 5 |
Note |
|---|---|---|---|
Client email rewrite |
22/25 |
23/25 |
Flash warmer + Acme; Sonnet more operational |
Bug explain + minimal fix |
23/25 |
23/25 |
Tie |
Logic + false premise |
24/25 |
22/25 |
Both refuse; Sonnet then plays along |
Total |
69/75 |
68/75 |
Editorial near tie; 5x cost still favors Flash for volume |
One point is not a reason to pay Sonnet for every hop. Keep it for writing jobs that reject Flash’s greeting, and for effort=max work this pack did not measure. Volume drafts should follow Figure 2.
Ecosystem and where you run them
- Gemini 3.7 Flash: Google AI / Gemini apps / Workspace adjacency. Strength: audio + video + file + image at Flash prices.
- Claude Sonnet 5: Anthropic API and Claude apps. Strength: Projects, file uploads, effort controls your runbook can name.
- Both in one place: Multi-model workspaces (including i10X) let you switch without two native subscriptions for every test.
Pros, cons, and failure modes
Gemini 3.7 Flash
- Pros: Five input types; ~1.05M context; $0.375/$1.875 list rates; ~5x cheaper on our workloads; named Acme in the rewrite; stayed practical on the false premise.
- Cons: Not a Sonnet-class “professional work” card; no effort knobs in this pull; greeting energy some brands will reject.
- Fails when: the job needed max-effort reasoning, or you treat Flash as Opus because it handled one bug.
Claude Sonnet 5
- Pros: Effort levels low/medium/high/max; image + file + text; operational rewrite; Claude app path; Sonnet-class positioning for coding and professional work.
- Cons: About 5x the list cost in this pair; no audio/video on this card; playful coda after refusing a false premise.
- Fails when: you leave it on the default route for classification, chat, and every agent retry.
Decision guide: pick one or route both
If you need… |
Choose |
|---|---|
Cheap volume at ~1M context |
Gemini 3.7 Flash |
Audio or video in |
Gemini 3.7 Flash |
Named reasoning effort (low to max) |
Claude Sonnet 5 |
Operational stakeholder email |
Claude Sonnet 5 (A/B; Flash if you want warmth) |
Claude Projects / Anthropic compliance path |
Claude Sonnet 5 |
Mixed week (docs + code + research) |
Keep both; route by task in a multi-model workspace |
Stop asking which model is “best.” Ask which model is best for the next step. Keep a second model for critique or a different modality. That is multi-model AI.
Application walkthroughs: where each model is better
1) Customer support email
Sonnet if the voice is dry. Flash if it is warm (and you want Acme, which showed up in the Flash excerpt). Do not pay 5x for a greeting you will delete.
2) High-volume text agent
Flash on cost ($0.0788 vs $0.42). Sonnet is the escalation model, not the default hop.
3) Meeting recording to notes
Flash (audio listed). Transcribe-then-Sonnet only if you need Sonnet prose.
4) PDF and screenshot
Both cards match. Flash is cheaper ($0.0375 vs $0.20). Use Sonnet if OCR eval says Flash misses layout.
5) Effort-controlled reasoning
Sonnet. Low / medium / high / max is the runbook feature Flash did not list.
6) When to leave this pair
Opus-class reviews and Pro-class research may need a flagship. This page exists so you do not pay Sonnet for every cheap hop, and so you do not pretend Flash is Opus.
Consumer plans vs API (do not mix them up)
Gemini app defaults and Claude seats are not these IDs.
- API comparison (this article):
Gemini 3.7 FlashvsClaude Sonnet 5at the list rates above. - Consumer apps: may bundle other Flash/Pro or Sonnet/Opus cousins with different tools and rate limits.
If your question is “which $20-class app feels better,” run a week in both products. If your question is “which ID should the agent call,” use this API page.
Frequently asked questions
Which is better overall, Gemini 3.7 Flash or Claude Sonnet 5?
Neither permanently. Our three-prompt card was 69-68 for Flash. Sonnet wins effort knobs and operational tone. Flash wins list cost and audio/video.
Which is better for coding?
Tie on the empty-list micro-test. Flash is the cheaper default. Sonnet is the effort-controlled fallback. Run your repo.
Which is better for writing?
Taste. Flash was warmer and named Acme. Sonnet was more operational. A/B on brand voice.
Which is cheaper?
Gemini 3.7 Flash at published API rates (2026-08-24): $0.375 vs $2 input, $1.875 vs $10 output, $0.0375 vs $0.20 cache read. All three workloads favor Flash by about 5x.
Which has the larger context window?
Gemini 3.7 Flash (1,048,576) vs Claude Sonnet 5 (1,000,000). Practically close.
Do I need both?
If some jobs are cheap media/volume and some jobs need named effort or Claude-stack files, yes.
Are we comparing apps or API models?
This page uses API models Gemini 3.7 Flash and Claude Sonnet 5. Consumer apps may wrap different defaults.
How often should I re-test?
After any major version bump. Monthly is sane. Re-price when list rates move. A 5x gap can shrink or grow.
Where can I run them side by side?
A multi-model workspace such as
i10X.
Method:
side-by-side AI comparison.
What about hallucinations and trust?
Both refused the Moon-cheese premise. Sonnet then offered a playful coda. Still ground publishable claims. See
multi-model hallucination checks.
Is this Gemini Pro or Claude Opus?
No. Pro and Opus are dearer flagships. This page is Flash vs Sonnet 5.
Try both in one workspace
Compare Gemini 3.7 Flash and Claude Sonnet 5 on the same prompt, then route the next step to the stronger model for that job.
- Vendor / API model cards / pricing for
Gemini 3.7 FlashandClaude Sonnet 5(checked 2026-08-24). Verify live. - Google positioning for Gemini 3.7 Flash: multimodal model for fast agentic workflows, coding, and complex multi-step reasoning; input text/image/video/file/audio.
- Anthropic positioning for Claude Sonnet 5: most capable Sonnet-class model for coding, agents, and professional work; adaptive thinking with low/medium/high/max effort; input text/image/file.
- i10X live side-by-side pack on 2026-08-24: client email rewrite, empty-list average bug, false-premise Moon cheese. Editorial scores, not a public benchmark.
- Workload cost model: 1k in + 0.5k out chat; 80k in + 4k out repo; 200k in (50% cache read) + 20k out agent, using published per-million rates from the same date.
- i10X Multi-Model silo: hub, routing, side-by-side method.