
Quick Take
The era of unbounded API calls is colliding with the physical limits of silicon and grid power, shifting the AI industry from brute-force scaling to strict compute rationing.
Summary: Severe AI hardware shortages are forcing cloud providers to throttle access and impose quotas on frontier models, fundamentally rewriting how enterprises budget and plan for AI integration.
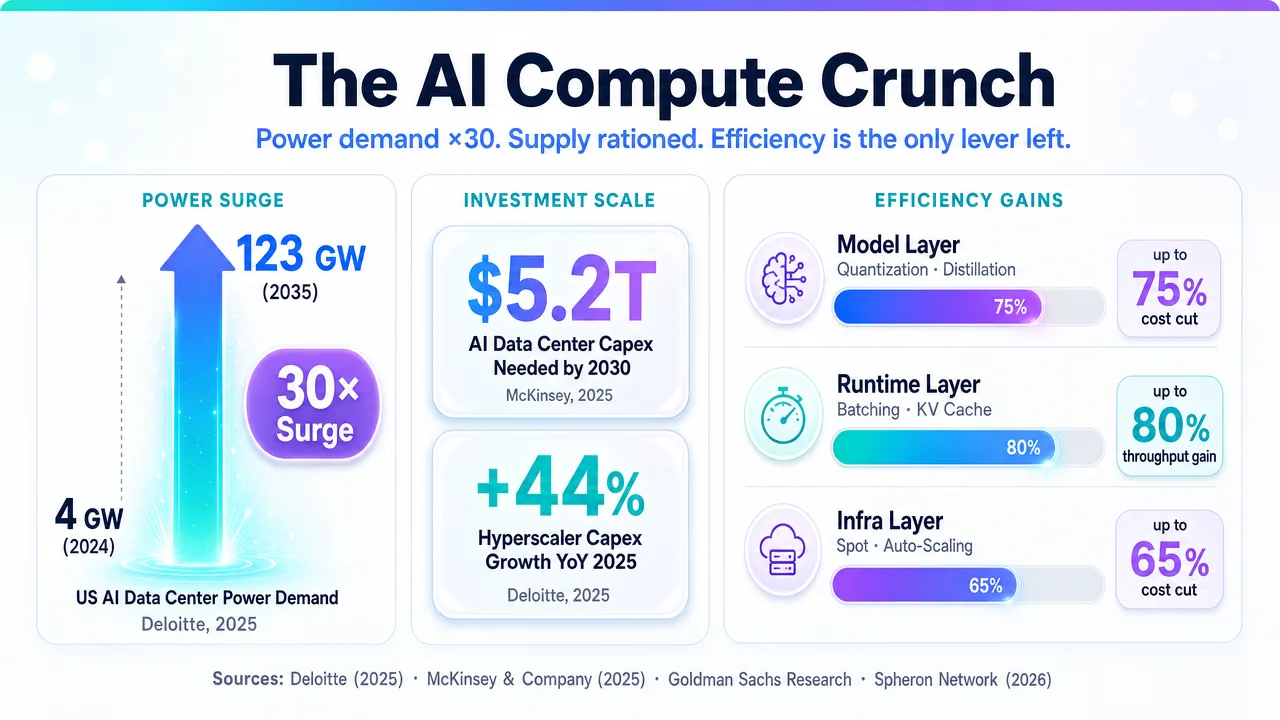
What happened: A persistent supply crunch in high-end GPUs – exacerbated by packaging bottlenecks and data center power limits – has led platforms to cap access to major LLMs like Gemini, ending the “tokenmaxxing” mentality of infinite, cheap compute.
Why it matters now: This scarcity is inflating training and inference costs, forcing a market-wide pivot. Instead of merely buying more GPUs, AI builders must rapidly adopt advanced efficiency techniques like quantization, caching, and optimized inference architectures just to maintain operational velocity.
Who is most affected: AI practitioners, startups, and enterprise CTOs are bearing the brunt, as they face unpredictable cloud waitlists and skyrocketing total cost of ownership (TCO) while trying to deploy production-grade intelligence.
The under-reported angle: The true bottleneck isn’t just found in silicon fabs; it’s a structural collision of TSMC packaging constraints (CoWoS), high-bandwidth memory (HBM) shortages, and regional power grid limits, turning compute into a heavily regulated and geopolitically sensitive commodity.
Deep Dive
Have you tried scaling an AI feature lately only to hit an invisible ceiling on calls? The era of “tokenmaxxing” – where developers could throw infinite, cheap API calls at a problem – is officially over. AI builders are hitting a hard physical wall, and the fallout is blowing up budgets across the board.
The old story of frictionless growth is being corrected by a severe hardware shortage. Cloud providers simply cannot rack H100s and B200s fast enough, so they have shifted from open taps to strict token quotas. Rationing access to frontier models like Gemini is now the norm, a direct response to demand that keeps climbing while supply stays tight.
To understand the shortage, look past Nvidia’s supply chain alone. The crisis runs deeper. Constraints at TSMC’s advanced CoWoS packaging, ongoing shortages in High-Bandwidth Memory (HBM), and straight limits on gigawatts at the data-center level all play a part. From what I’ve seen, bringing even a 1-gigawatt AI campus online turns into a drawn-out negotiation with utilities, grid operators, and local policymakers. Power and cooling have become the real governors of progress.
This scarcity is also widening a divide. Big Tech and well-funded labs can still lock in multi-year reservations. Startups and mid-market teams, by contrast, are left juggling multi-cloud hops, waitlists, and spot instances just to keep batch inference running.
Because of this, the most pressing work in AI right now centers on efficiency rather than raw scale. Engineering groups are building what amounts to “AI FinOps” practices – quantization, distillation, LoRA fine-tuning, KV cache optimization. Tools such as vLLM and TensorRT-LLM have moved from nice-to-have to essential for squeezing meaningful throughput out of limited hardware.
The rationing is also pushing teams toward smaller, distilled open-weight models and edge inference. When cloud capacity carries quotas and rising TCO, running lighter models on-device or through on-prem colocation often becomes the more reliable path to sustained momentum and reduced vendor dependence.
Stakeholders & Impact
| Stakeholder / Aspect | Impact | Insight |
|---|---|---|
| Hyperscalers & AI Vendors | High | Forced to implement dynamic quotas and token caps; prioritizing highest-margin workloads while scrambling for grid power. |
| Enterprise AI Adopters | High | TCO models are breaking. Forced to shift from purely cloud-native API dependency to hybrid strategies involving smaller, self-hosted models. |
| AI Infrastructure & Utilities | Significant | Severe pressure to bypass grid bottlenecks via alternative cooling and next-generation power agreements (e.g., nuclear or off-grid assets). |
| Foundry / Supply Chain | Maximum | TSMC, memory suppliers (HBM), and packaging facilities remain the ultimate chokepoints, dictating the global pace of AI deployment. |
About the analysis
Researched and written with AI assistance under the editorial responsibility of the i10X News team. The title image is an AI-generated illustration. Read our AI Use Policy. Spotted an error? Request a correction.
This independent, research-based analysis triangulates current hardware allocation policies, semantic AI supply chain mapping (from fabs to data center grids), and emerging developer workarounds. It is designed for CTOs, AI FinOps leaders, and infrastructure architects navigating the strategic complexities of the global compute crunch.
i10x Perspective
Compute is rapidly becoming the world’s most fiercely contested macro-commodity. I’ve noticed how the current shortage marks a clear end to brute-force scaling and the start of an efficiency-first mindset, where clever architecture has to make up for physical limits. Over the next five years, expect a clear split: gated frontier models for those who can secure the power, alongside highly optimized, decentralized systems running closer to the edge. The real advantage will go to teams that learn how to deliver results with the least compute rather than the most.



