Quick Take
- The finding: In a randomized study with 802 US adults in the Google Health app, a structured AI agent prepared patients for doctor visits better than a plain chatbot running on the same Gemini 2.5 Flash model.
- The numbers: 73.8% of agent users felt prepared for their visit vs. 57.0% with the control chatbot; blinded clinicians rated 67.2% of agent sessions fully comprehensive vs. 50.6%.
- The caveat: Safety stayed high in both arms, but patient satisfaction and clinician-rated quality did not correlate, and the study was run and funded by Google.
Many patients already ask chatbots what to expect before a doctor’s appointment. A new preprint from Google Research, “A prospective randomized study of patient-centered AI for clinical visit preparation” by Xincheng Tan, Mike Schaekermann, Quang Duong, Jackie M. Barr and 32 co-authors, tests whether a purpose-built AI visit preparation agent actually helps, compared with a minimally prompted chatbot. It is one of the first randomized tests of a patient-facing AI tool in a real consumer app rather than a benchmark or simulation.
What the study shows
All three study arms used the same model and interface and differed only in their system prompts. The visit preparation agent (in a standard and a concise variant, pooled in the main analysis) followed a fixed workflow: gather context, set expectations for the visit, give general health information, build a prioritized list of questions for the clinician and keep a running summary.
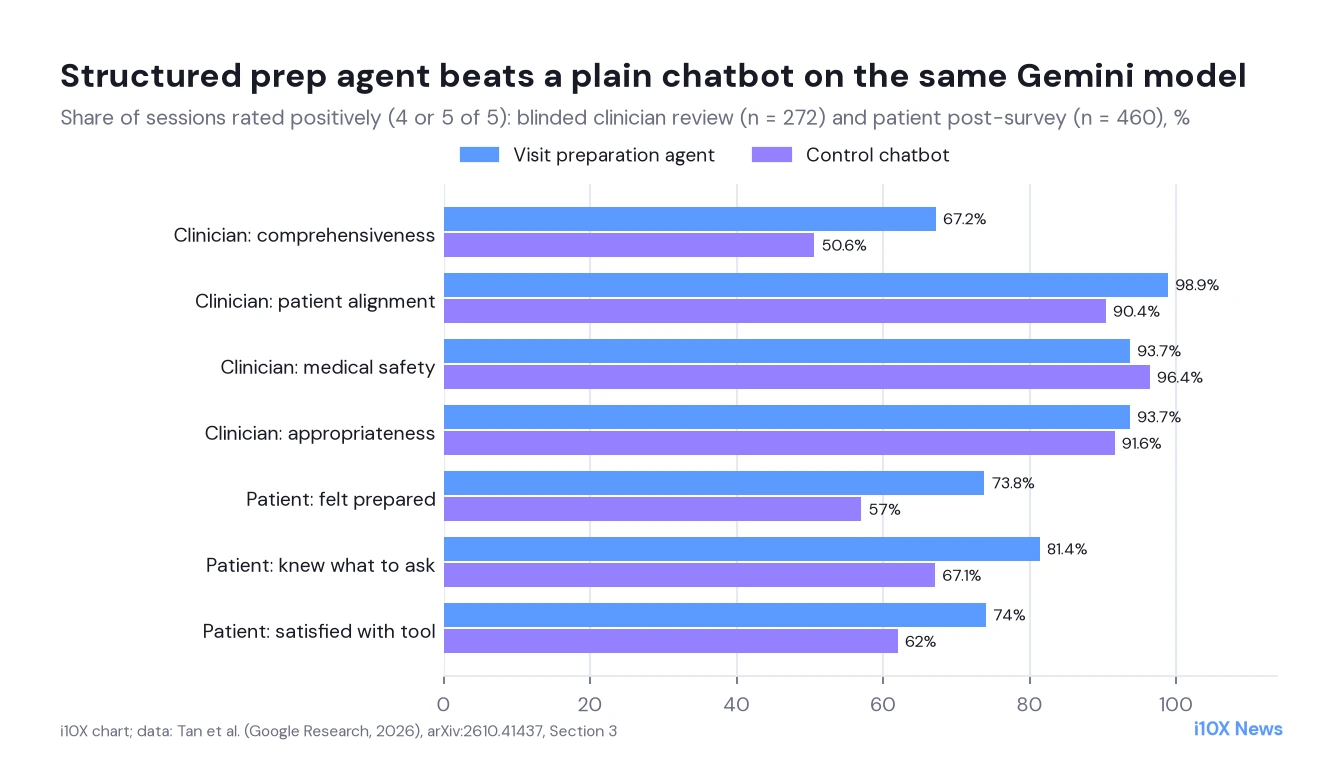
- More complete preparation: Three blinded primary care physicians reviewed 272 completed sessions. Agent sessions were fully comprehensive more often (67.2% vs. 50.6%; P < 0.05) and better aligned with the patient’s health context (98.9% vs. 90.4%; P < 0.01).
- No loss in safety: Medical safety (93.7% vs. 96.4% for control) and appropriateness (93.7% vs. 91.6%) did not differ significantly. “Unsafe helpfulness”, meaning high utility with lower reliability, occurred in 2.6% of agent sessions and none of the control sessions.
- More useful safe sessions: Sessions rated both highly reliable and highly useful rose from 50.6% to 64.6% (P < 0.05).
- Patients felt better prepared: In 460 post-surveys, agent users more often felt prepared (73.8% vs. 57.0%), knew what to ask (81.4% vs. 67.1%), felt able to make the most of the visit (81.4% vs. 69.6%), were satisfied (74.0% vs. 62.0%) and wanted to reuse the tool (76.6% vs. 65.8%).
- Two perspectives, no overlap: After correction for multiple comparisons, no patient survey item correlated significantly with any clinician rating.
| Outcome | Visit prep agent | Control | P |
|---|---|---|---|
| Clinician: fully comprehensive | 67.2% | 50.6% | < 0.05 |
| Clinician: aligned with patient context | 98.9% | 90.4% | < 0.01 |
| Clinician: medically safe | 93.7% | 96.4% | n.s. |
| Patient: felt prepared | 73.8% | 57.0% | < 0.01 |
| Patient: confident what to ask | 81.4% | 67.1% | < 0.01 |
| Patient: satisfied with tool | 74.0% | 62.0% | < 0.05 |
Why it matters: Structure beats raw model capability
Because both arms ran on the same Gemini 2.5 Flash model, the gains come from how the conversation was designed, not from a stronger model. That is a useful result for anyone building health assistants: a guided workflow made patients feel more prepared without a measurable safety cost.
The design is stronger than most patient-facing AI studies. Participants were randomized, the trial was approved by the Advarra IRB and registered at ClinicalTrials.gov (NCT07552311), reporting followed CONSORT, clinicians were blinded to study arm and model, and P values were corrected for multiple testing with the Benjamini-Hochberg procedure. Completion rates were similar between arms (41.1% vs. 42.5% discontinued), which makes a biased comparison less likely.
Method in brief
- Setting: Decentralized study in the Google Health app on Android in the US, November 19, 2025 to May 15, 2026.
- Participants: 5,960 users consented and were randomized 1:2:2; 802 adults with 866 health-related conversations entered the analysis (control 141, agent 725). Mean age 50.5 years, 63.3% of conversations by women. People with known mental health conditions, STIs or pregnancy were excluded.
- Visits: Most common were specialist consultations (33.1%), annual wellness exams (21.8%) and chronic-condition primary care (17.0%).
- Evaluation: Primary outcome was the patient-reported preparation experience; secondary was blinded clinician review on medical safety, appropriateness, comprehensiveness and patient alignment; a 14-day follow-up was exploratory.
What remains open
- No clinical outcomes: The study measures how prepared patients felt and how clinicians rated the transcripts, not whether visits or health outcomes improved.
- Thin follow-up: Only 59 participants reported a doctor visit in the 14-day follow-up. 78.3% vs. 69.2% said the visit matched the expectations set by the agent, a difference that was not significant.
- Survivorship: 42.3% of included conversations ended early, and clinicians only rated completed sessions, so absolute quality ratings may be too high.
- Selective sample: Android users of the Google Health app who opted into research are likely more tech-savvy and health-literate than average patients, and education, income and ethnicity were not collected.
- Industry study: Google designed, ran and funded the trial. The system prompts are published in the appendix, but beyond example conversations the study data are not released.
Context: From diagnosis benchmarks to patient support
Most medical AI research tests models on exam questions or simulated diagnoses. This study puts a Gemini-based agent in a narrower, non-diagnostic role and measures real users. That matters because other recent studies have shown the risks of chatbots in health, from models bending diagnoses to patient beliefs to reasoning models producing false positives. Google‘s result suggests that scoping the task tightly is one way to keep that risk low. More research is collected in Society & Economy.
What it means for health apps and patients
- Builders: Prompt and workflow design can move outcomes as much as model choice. Structured steps and a running summary are cheap to add.
- Evaluators: Patient satisfaction is not a proxy for clinical quality. Health AI should be judged by both clinicians and users.
- Patients: Asking a chatbot to help you list and prioritize questions before a visit is a low-risk use, as long as it does not replace the clinician’s judgment.
About the analysis
Researched and written with AI assistance under the editorial responsibility of the i10X News team. The title image is an AI-generated illustration. Read our AI Use Policy. Spotted an error? Request a correction.
This article is based on the full text of the preprint (arXiv:2610.41437v1, submitted October 30, 2026), including the appendix. All numbers come from the paper; i10X did not rerun the analysis. The chart was drawn by i10X from numbers stated in Section 3; arXiv lists the paper under CC BY 4.0, while the PDF carries a Google copyright notice, so no original figures were reused. The study was funded by Alphabet, and authors who are Alphabet employees may own stock. AI tools assisted with research and drafting; the selection, fact-checking and final editing were done by the i10X editorial team.
i10x Perspective
The interesting part is not that Google’s agent won, but why: the same model, given a better script, did measurably more for patients. As chatbots become the first stop before a doctor’s visit, how they are structured will matter as much as which model sits underneath.