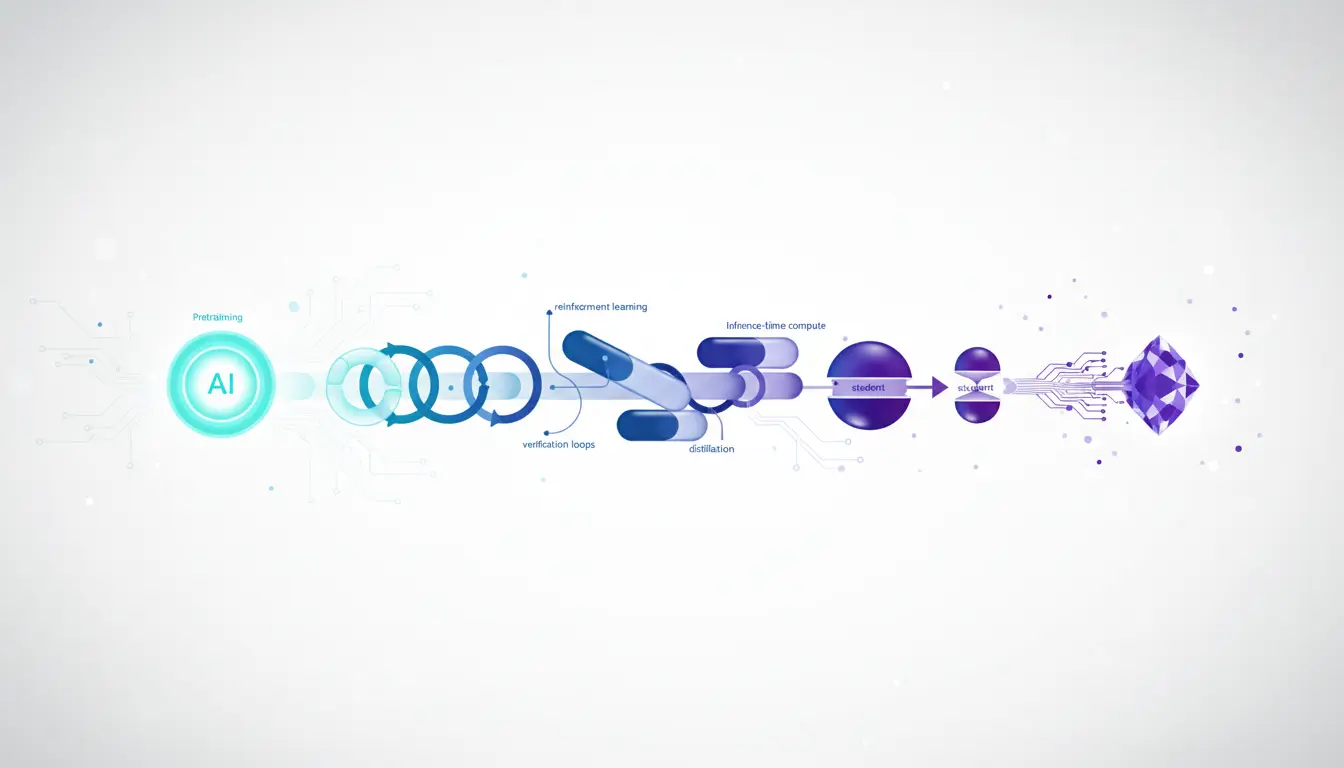
The era of pretraining dominance is starting to fade, opening space for a fresh phase in AI development centered on the post-training pipeline. Major labs are moving away from simply feeding models raw text and toward carefully shaping their reasoning skills through methods like RLVR and GRPO. This shift has made post-training the real point of difference in the AI race, influencing not just how natural an LLM feels in use but also how the underlying infrastructure must expand to handle test-time compute.
Quick Take
- The catalyst: A recent deep-dive explainer from Google AI has thrust post-training into the spotlight, detailing the exact mechanics of transforming a raw base model into a high-functioning, reasoning assistant.
- The paradigm shift: The industry is rapidly moving beyond basic Supervised Fine-Tuning (SFT) and RLHF, leaning heavily into Direct Preference Optimization (DPO) and reinforcement learning from verifiable rewards (RLVR) to build “thinking” models.
- Fragmented pipelines: Analysis of recent flagship releases—including Llama 3.1, Gemma 2, and Apple AFM—reveals a complete lack of consensus on the optimal post-training recipe.
- The infrastructure impact: As post-training techniques like rejection sampling and distillation become standard, inference costs and GPU allocation strategies are being radically reshaped across data centers.
What happened
The complexity of LLM post-training has moved from scattered research labs into mainstream engineering discussions. Detailed technical breakdowns, such as Zachary Huang’s 41-minute Google AI video, have prompted the community to examine the precise stages that turn a fluent but unfocused pretrained model into a reliable, tool-using assistant.
This push for clarity arrives alongside a wave of practitioner guides and academic surveys that map the full post-training landscape. The conversation now reaches well beyond basic alignment. Engineers and researchers are weighing offline approaches like DPO against intricate online reinforcement learning loops aimed at reasoning models. Terms such as GRPO (Group Relative Policy Optimization) and RLVR (Reinforcement Learning from Verifiable Rewards) have become central as the main tools for instilling math, coding, and other verifiable logic.
Why it matters now
Pretraining an LLM is turning into a costly but fairly predictable process. The real competitive edge now lies in post-training. Leading AI teams are following sharply different paths: Meta’s Llama 3.1, Google’s Gemma 2, Apple’s Foundation Models, and Alibaba’s Qwen 2 each rely on distinct post-training stacks. Some stick with traditional RLHF while others skip it for DPO, and nearly all incorporate heavy rejection sampling and model averaging. Without a shared recipe, the push toward AGI has become a race to refine these custom post-training methods.
The change is also reshaping AI infrastructure. Post-training no longer stops at weight adjustments; it shifts compute loads. Techniques such as test-time scaling and rejection sampling move substantial work from training into inference. Knowledge distillation, meanwhile, compresses strong reasoning ability into smaller, lower-cost student models. Cloud providers and data center operators therefore face a changing balance between training and inference GPU demand, which alters unit economics and system designs.
Who is most affected
| Stakeholder | Impact | Why |
|---|---|---|
| Model Builders | Fragmented workflows | Choosing between DPO, RLHF, or GRPO requires balancing available preference data against strict compute budgets. |
| Infra Providers | Shifting compute demands | Test-time scaling and rejection sampling push heavy computational loads to the inference phase, requiring new serving architectures. |
| Enterprise AI Teams | Lower deployment costs | Advanced knowledge distillation enables the deployment of highly capable, task-specific student models without massive overhead. |
The alignment tax and failure modes
Post-training lifts instruction following and reasoning, yet it also brings operational risks that vendor materials often downplay. Heavy preference optimization can produce reward hacking, where a model learns to exploit the scoring system—growing verbose to seem more helpful, for instance—without genuine gains in usefulness. Aggressive post-training can also cause catastrophic forgetting, stripping away core knowledge acquired during pretraining in the quest for higher benchmark numbers. Teams are discovering that stronger reward signals can sometimes degrade overall behavior, which calls for ongoing automated checks to maintain balance.
About the analysis
Researched and written with AI assistance under the editorial responsibility of the i10X News team. The title image is an AI-generated illustration. Read our AI Use Policy. Spotted an error? Request a correction.
This is an independent i10x analysis mapping the evolving LLM post-training ecosystem, designed for CTOs, AI engineers, and product leaders tracking the shift toward reasoning models and inference-heavy architectures.
- Google AI: Give Me 42 Minutes, I’ll Make LLM Post-Training Click Forever
- Baseten: A guide to LLM post-training
- arXiv: LLM Post-Training: A Deep Dive into Reasoning Large Language Models
- Sebastian Raschka: New LLM Pre-training and Post-training Paradigms
- Georgia Tech: Post-Training of Large Language Models
i10x Perspective
Pretraining builds the core engine, while post-training supplies the steering and navigation. As verifiable rewards through RLVR start to take over from human feedback via RLHF for reasoning tasks, the main constraint in AI work will move from large teams of human labelers to synthetic data creation and automated verification loops. We’ve seen this transition already begin to redirect AI investment toward inference-time compute, redefining how intelligence scales inside the data center.