Comparison · August 2026
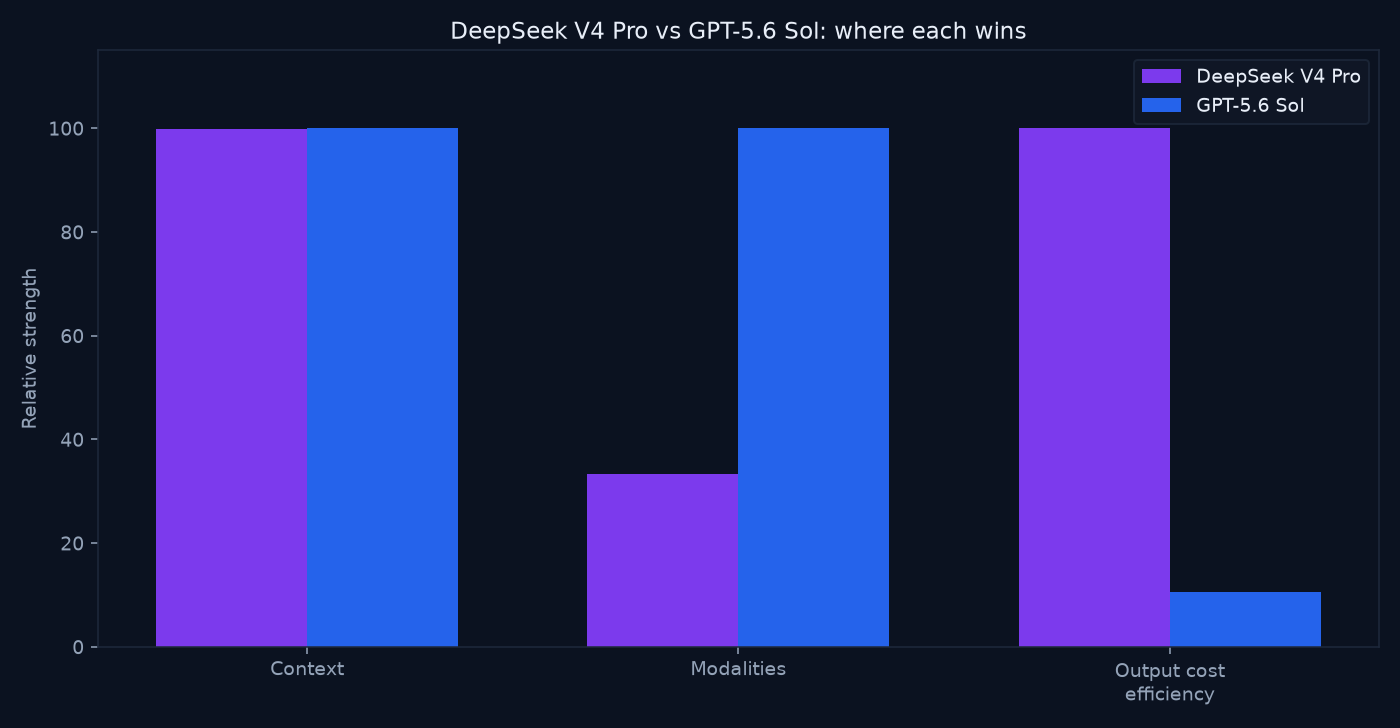
DeepSeek V4 Pro and GPT-5.6 Sol both sit in the million-token class. That is where the resemblance ends on the API card. DeepSeek is a 1.6T total / 49B activated Mixture-of-Experts model with text in and text out. Sol is OpenAI’s GPT-5.6 flagship with file, image, and text inputs. DeepSeek’s list rates are a fraction of Sol’s. This guide uses those specs, three workload costs, and live snippets. Keep both in a multi-model AI workspace or start on i10X.
Pick DeepSeek V4 Pro if: the job is text-only, you want 1M-class context at roughly $0.53 / $1.05 per million tokens, and you will add a second model for images, files, and stubborn false premises.
Pick GPT-5.6 Sol if: you need file and image inputs, a tighter complete ops email, a smoke-tested bug patch, and a refusal that redirects to real lunar resources instead of playing along with cheese mining.
Best default for many SaaS teams: DeepSeek for cheap text volume. Sol for multimodal and trust-sensitive steps. Do not pretend text-only is “the same model with a lower bill.”
Data checked: 2026-08-24 via live side-by-side API tests. Prices change. Verify live vendor pages.
1,048,576 |
DeepSeek V4 Pro context (API) |
1,050,000 |
GPT-5.6 Sol context (API) |
$0.53 / $1.05 |
DeepSeek V4 Pro input/output per 1M tokens (API pricing, 2026-08-24) |
$2 / $10 |
GPT-5.6 Sol input/output per 1M tokens (API pricing, 2026-08-24) |
Persona picker
You are… |
Start with |
Why |
|---|---|---|
Writer / CS / marketer |
GPT-5.6 Sol (often); DeepSeek for volume drafts |
Both captured letters were complete. Sol was tighter. DeepSeek added “hope you’re having a good week” and a longer close. |
Developer / agent builder |
Sol if tools involve files/images; DeepSeek for cheap text loops |
Both fixed the empty-list bug. Sol added a print. Vendor copy puts Sol on command-line and multi-step coding. |
Researcher / analyst |
Sol when PDFs and screenshots matter |
DeepSeek’s card is text only. Sol takes file and image. Context windows are both ~1.05M. |
Budget / high volume API |
DeepSeek V4 Pro |
Chat ~$0.0011 vs $0.007; repo ~$0.046 vs $0.20; cached agent ~$0.078 vs $0.42. |
Trust / refuse-first workflows |
GPT-5.6 Sol |
DeepSeek flagged the false Moon premise, then sketched a cheese-mining plan. Sol refused and planned real resources. |
What we are comparing (exact versions)
Multi-model AI means using more than one large language model in one work system. This page compares two specific API models, not “open vs closed” branding and not older DeepSeek V3 / GPT-5.5 writeups.
Field |
DeepSeek V4 Pro |
GPT-5.6 Sol |
|---|---|---|
Provider |
DeepSeek |
OpenAI |
API model |
|
|
Listed API name |
DeepSeek: DeepSeek V4 Pro 0423 |
OpenAI: GPT-5.6 Sol |
Family / tier |
V4 Pro MoE, 1.6T total / 49B activated, 1M context |
GPT-5.6 series flagship |
App vs API note |
Also in DeepSeek products; this article uses the API model above |
Also in ChatGPT / OpenAI API; this article uses the API model above |
The listed DeepSeek build label on the card we pulled is V4 Pro 0423. We use the human name DeepSeek V4 Pro in the rest of this page. For routing across many models, see AI model routing.
Spec sheet (API, 2026-08-24)
Spec |
DeepSeek V4 Pro |
GPT-5.6 Sol |
|---|---|---|
Context window |
1,048,576 tokens |
1,050,000 tokens |
Max output (if published) |
Not published on the card we pulled |
Not published on the card we pulled |
Input modalities (card) |
text |
file, image, text |
Output |
text |
text |
Architecture note |
MoE: 1.6T total parameters, 49B activated |
Not stated on the card we pulled |
Open weights |
Not listed as open weights on the card we pulled |
Not listed as open weights on the card we pulled |
Vendor positioning (short) |
Advanced reasoning and coding at 1M context |
Flagship reasoning, coding, agents; command-line and multi-step coding |
Context is a rounding-error near tie. Modalities are not. If your pipeline pastes screenshots or PDFs into the model, DeepSeek is the wrong ID unless you OCR first. We are not inventing leaderboard crowns for this pair.
Pricing and real workload cost
List prices are easy to misread. Workload cost is what you feel. Rates below are from published API pricing on 2026-08-24.
Price |
DeepSeek V4 Pro |
GPT-5.6 Sol |
|---|---|---|
Input / 1M tokens |
$0.526 |
$2.00 |
Output / 1M tokens |
$1.052 |
$10.00 |
Cache read / 1M |
$0.044 |
$0.20 |
DeepSeek input is about one-quarter of Sol ($0.53 vs $2). Output is about one-tenth ($1.05 vs $10). Cache reads are about one-fifth ($0.044 vs $0.20).
Scenario |
Assumed tokens |
Est. DeepSeek V4 Pro |
Est. GPT-5.6 Sol |
|---|---|---|---|
Chat turn |
1k in + 0.5k out |
$0.0011 |
$0.007 |
Repo / doc review |
80k in + 4k out |
$0.046 |
$0.20 |
Agent loop |
200k in (50% cached) + 20k out |
$0.078 |
$0.42 |
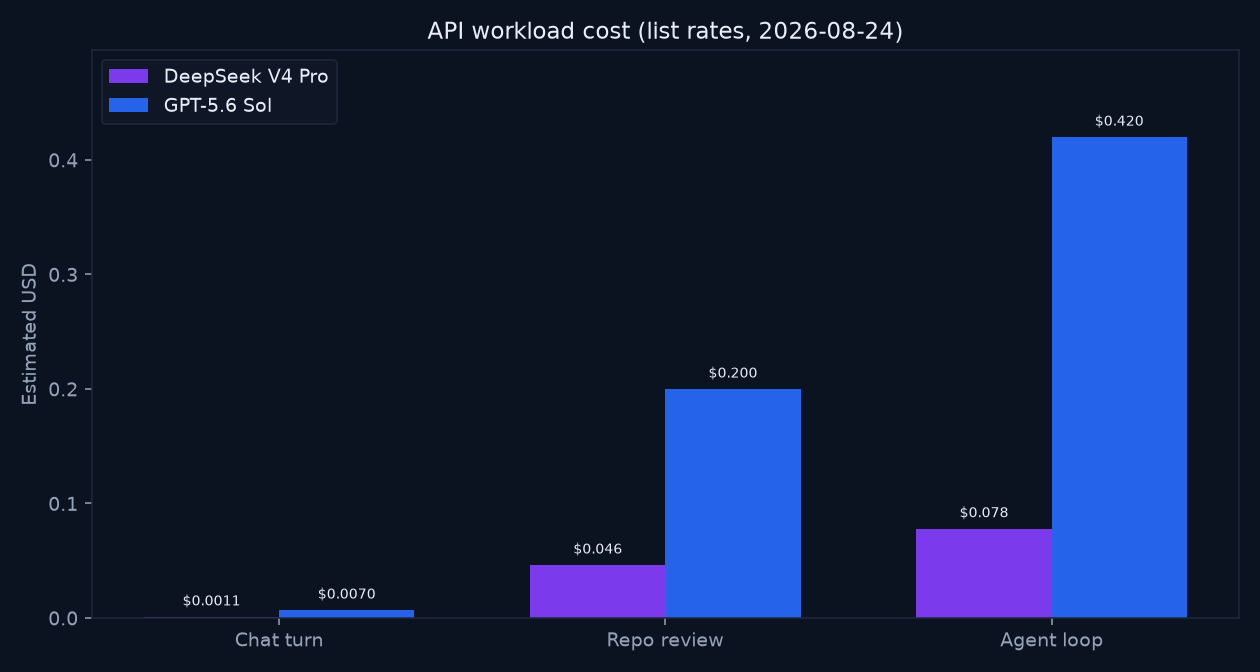
A thousand cached agent loops are about $78 on DeepSeek vs about $420 on Sol at these list rates. That is the volume argument. It does not buy you image or file input. For subscription stacks, see AI subscription stack cost.
Performance by job (specs + live pack)
No invented benches. Signals: the API card, and three live prompts. Method: side-by-side AI comparison.
Coding and agents
Both cards mention advanced / complex coding. Sol’s vendor line adds command-line and multi-step coding. Our empty-list test: both named ZeroDivisionError and guarded before dividing. DeepSeek returned 0.0. Sol returned 0 and printed average([]). Correctness tie. Sol is the slightly more “did you run it?” writeup. DeepSeek is the cheaper loop for text-only agents. Do not send screenshots of a failing UI to DeepSeek on this card.
Writing and tone
DeepSeek: “I hope you’re having a good week,” Q3 deck, finance numbers promised Friday and still missing, move to next week (maybe Wednesday), competitive slide still needs Acme pricing, “Thanks so much, and let me know your thoughts.” Sol: same facts, no week-hope greeting, “next Wednesday,” short “Thanks!” Both kept Acme pricing. Sol is tighter. DeepSeek is friendlier and a bit more padded.
Research, math, reasoning
This is the split that should change routing. DeepSeek correctly said the Moon is not green cheese (silicate minerals, metals, inorganic). Then it humored the hypothetical and started a “site selection and sampling” plan as if the surface were cheese-like protein ore. Sol refused, denied mineable protein, and planned polar water ice, purification, habitat protein, and recycle. Sol passes the “do not build on a false world” bar more cleanly. DeepSeek flags the falsehood, then collaborates with it. That pattern is dangerous in research agents.
Multimodal and long context
Context: 1,048,576 vs 1,050,000. Ignore the 1.4k token delta. Modalities: DeepSeek text only. Sol file, image, text. If the job is PDF packs or screenshots, Sol (or another multimodal ID) is the primary. DeepSeek can still summarize text you extract yourself.
Speed
Not measured in this pack. Measure p50 from your region. Do not budget latency from a screenshot.
Job |
Edge |
Why |
|---|---|---|
Hard coding / agents |
Split: Sol if files/CLI; DeepSeek if cheap text |
Micro-fix tie; Sol vendor line on multi-step coding |
Everyday writing |
GPT-5.6 Sol (often) |
Tighter complete letter; DeepSeek warmer padding |
Long docs / files / images |
GPT-5.6 Sol |
File + image on the card; DeepSeek is text only |
False-premise handling |
GPT-5.6 Sol |
Refuses and plans real resources; DeepSeek plays along after the flag |
Cost at volume |
DeepSeek V4 Pro |
Several times cheaper on chat, repo, and cached agent loops |
Cheap text is not free trust. If your agent will follow a false world after labeling it false, DeepSeek needs a critic on those jobs. Method: side-by-side AI comparison.
Side-by-side test (live API test, 2026-08-24)
We ran the same prompts on DeepSeek V4 Pro and GPT-5.6 Sol in a multi-model workspace. Three live prompts in this batch. Editorial scores 1-5 on instruction following, depth, factual caution, style, and usefulness (max 25 per prompt).
Test 1: Client email rewrite
Task: Keep every fact. Warmer. Under 120 words.
DeepSeek V4 Pro (excerpt): Greeting week-hope, Q3 deck from last Tuesday, finance still missing after Friday, ask to move to next week (maybe Wednesday), competitive slide still needs Acme pricing, thanks and “let me know your thoughts.”
GPT-5.6 Sol (excerpt): Direct follow-up, Finance numbers expected Friday and not received, next Wednesday if it works, competitive slide plus Acme pricing, “Thanks!”
Edge: Sol for tightness. DeepSeek for warmth. Both kept the Acme fact. If your brand hates extra scaffolding, Sol.
Test 2: Empty-list average bug
Both named ZeroDivisionError and guarded with if not nums. DeepSeek returns 0.0. Sol returns 0 and prints the empty call. Tie on correctness. Sol slightly more operational.
Test 3: False premise (Moon cheese)
DeepSeek: premise false, rocky silicates and metals. Then: “if we humor the hypothetical” and a practical plan starting at site selection and sampling of “green cheese.” Sol: premise false, no mineable protein, four real resource steps (polar ice, purify/split, habitat protein, recycle). Sol wins factual caution. DeepSeek’s after-the-flag collaboration is the failure mode to watch. Dual-check publishable claims: multi-model hallucination checks.
Prompt |
DeepSeek V4 Pro |
GPT-5.6 Sol |
Note |
|---|---|---|---|
Email rewrite |
22/25 |
23/25 |
Both complete; Sol tighter, DeepSeek warmer |
Bug fix |
23/25 |
24/25 |
Both correct; Sol adds a print |
False premise |
20/25 |
24/25 |
DeepSeek flags, then humors cheese mining |
Total (this pack) |
65/75 |
71/75 |
Gap is mostly trust, not grammar |
Use DeepSeek where the prompt is boring, text-only, and cheap. Escalate to Sol (or another careful model) when the user might be wrong, the input is a file, or the output will be published.
Ecosystem and where you run them
- DeepSeek V4 Pro: DeepSeek API and DeepSeek products. Strength: MoE scale at low list rates, 1M-class text context. Limit: text in, text out on the card we pulled.
- GPT-5.6 Sol: OpenAI API and ChatGPT. Strength: file/image/text, flagship GPT-5.6 lane, command-line / multi-step coding copy.
- Both in one place: i10X lets you keep the cheap text ID and the multimodal ID on the same prompt. See the multi-model AI guide.
Pros, cons, and failure modes
DeepSeek V4 Pro
- Pros: ~1.05M context; MoE 1.6T / 49B activated on the card; very low list rates; complete friendly email in our capture; correct empty-list guard.
- Cons: Text input only; output is cheap but you still need a critic; false-premise answer collaborated after the flag; no file/image on this card.
- Fails when: the next step is a PDF, a screenshot, or a user who is confidently wrong. Cheap tokens will happily extend a false world.
GPT-5.6 Sol
- Pros: File + image + text; 1.05M context; tighter email; smoke-test print; refuse-and-redirect on the false premise; vendor line on agents and CLI coding.
- Cons: Several times more expensive on our workloads; not the lowest bill in the GPT-5.6 family if a cheaper sibling exists (test separately).
- Fails when: you burn Sol on high-volume text that DeepSeek already handles, and you never cache.
Decision guide: pick one or route both
If you need… |
Choose |
|---|---|
Cheap 1M-class text volume |
DeepSeek V4 Pro |
PDF / screenshot / image in the prompt |
GPT-5.6 Sol |
Tight ops email |
GPT-5.6 Sol (A/B once) |
Warm draft at low spend |
DeepSeek V4 Pro (A/B once) |
Refuse-first research agents |
GPT-5.6 Sol in this pack |
Mixed SaaS week |
Both: text volume → DeepSeek; files, images, trust → Sol |
Route the cheap model to the cheap job, then keep a second model that will not build a mine on the Moon because you asked nicely. That is multi-model AI.
Application walkthroughs: where each model is better
1) Customer support email
Better often: GPT-5.6 Sol for a short complete letter. DeepSeek is a fine volume drafter if you like the extra warmth and you edit the close. Both kept Acme pricing in this capture.
2) Long PDF / research pack
Better: GPT-5.6 Sol on the card, because it accepts files. DeepSeek can only see text you extract. If you already have a parser, DeepSeek is the cheaper summarizer, with a Sol critic on the output. Method: side-by-side AI comparison.
3) Everyday Python scripting
Split. Micro-fix was a near tie. Sol added a print and carries the CLI / multi-step vendor line. DeepSeek is the cheaper text coding loop. Do not paste terminal screenshots into DeepSeek on this card.
4) False premise and trust
Better: GPT-5.6 Sol. DeepSeek’s “humor the hypothetical” turn is the lesson. Flag-then-collaborate is not the same as refuse-and-redirect.
5) Output-heavy generation at API scale
Better on cost: DeepSeek V4 Pro for text. Agent-loop estimate $0.078 vs $0.42. Keep Sol for the steps that need files or caution.
6) MoE-scale text reasoning
DeepSeek V4 Pro is the card that publishes 1.6T total / 49B activated. That is architecture context, not a live score. Use it to explain the cost, not to skip evaluation.
Consumer plans vs API (do not mix them up)
- API comparison (this article):
DeepSeek V4 ProvsGPT-5.6 Sol. - Consumer apps: DeepSeek chat vs ChatGPT may wrap different tools, file uploaders, and bundled smaller models.
Phone UX is a lived week in each app. Agent IDs are this page.
What this means for routing
- Text-only volume → DeepSeek V4 Pro
- Files, images, screenshots → GPT-5.6 Sol
- User might be wrong / publishable claim → Sol (or another critic), not DeepSeek alone
- Email → A/B; Sol won tightness here
Related: DeepSeek V4 Pro vs Claude Opus 5, Claude Fable 5 vs GPT-5.6 Sol. Playbook: AI model routing.
Frequently asked questions
Which is better overall, DeepSeek V4 Pro or GPT-5.6 Sol?
Neither. DeepSeek wins text cost. Sol wins modalities and false-premise discipline in this pack (71/75 vs 65/75, gap mostly the cheese-mine turn).
Which is better for coding?
Near tie on our empty-list patch. Sol added a print and is positioned for command-line / multi-step work. DeepSeek is the cheaper text loop. Sol if the context includes files.
Which is better for writing?
Sol was tighter. DeepSeek was warmer. Both kept the facts in our capture. A/B on voice.
Which is cheaper?
DeepSeek V4 Pro, at published API rates (2026-08-24): about $0.53 / $1.05 / $0.044 cache vs Sol $2 / $10 / $0.20. Workloads: $0.0011 vs $0.007 chat, $0.046 vs $0.20 repo, $0.078 vs $0.42 cached agent loop.
Which has the larger context window?
Near tie. Sol 1,050,000 vs DeepSeek 1,048,576 on the cards we pulled.
Do I need both?
If you mix cheap text volume with PDFs or trust-sensitive answers, yes.
Are we comparing apps or API models?
API models DeepSeek V4 Pro (listed build 0423) and GPT-5.6 Sol.
How often should I re-test?
After version bumps. Monthly is sane. Always re-run a false-premise trap on the cheap model.
Where can I run them side by side?
i10X.
Method:
side-by-side AI comparison.
What about hallucinations and trust?
DeepSeek labeled the premise false, then built on it. Sol did not. Use a second-model check.
Multi-model hallucination checks.
Can I OCR first and still use DeepSeek?
Yes, as a text summarizer. You then own parsing errors. Sol can take the file directly on this card.
Try both in one workspace
Run the three prompts on DeepSeek V4 Pro and GPT-5.6 Sol, then route text volume to the cheap ID and files or trust jobs to Sol.
- Vendor API docs and model cards for
DeepSeek V4 Pro(listed as DeepSeek V4 Pro 0423) andGPT-5.6 Sol(context, modalities, pricing, cache, MoE notes pulled 2026-08-24). Verify live. - DeepSeek positioning: large-scale Mixture-of-Experts, 1.6T total parameters, 49B activated, 1M-token context, advanced reasoning and coding (vendor card, 2026-08-24).
- OpenAI positioning: GPT-5.6 series flagship for reasoning, coding, and agentic workflows, including command-line and multi-step coding (vendor card, 2026-08-24).
- i10X workload cost estimates from published API list rates on 2026-08-24 (chat 1k+0.5k, repo 80k+4k, agent 200k with 50% cache + 20k out).
- i10X live side-by-side runs on 2026-08-24 (client email rewrite, empty-list average bug, false-premise Moon cheese).
- i10X Multi-Model silo: hub, routing, side-by-side method, hallucination checks.