Comparison · August 2026
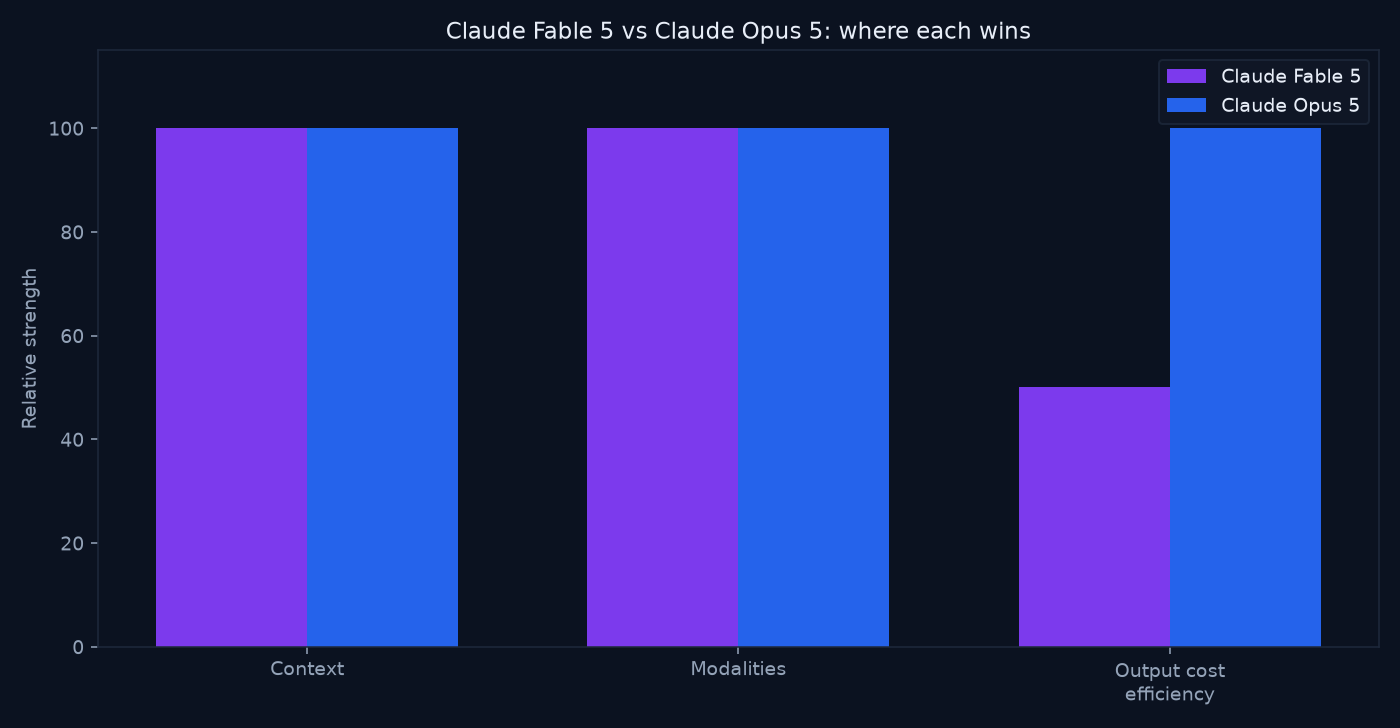
Claude Fable 5 and Claude Opus 5 are two Anthropic models on the same card shape: 1M context, text/image/file in, text out. Fable is billed as Mythos-class autonomous knowledge work. Opus 5 is billed as the flagship for demanding reasoning, coding, and long-horizon agents. The list-price gap is the story: Fable is $10 / $50, Opus is $5 / $25. This guide uses those specs, three workload costs, and live snippets. Keep both in a multi-model AI workspace or start on i10X.
Pick Claude Fable 5 if: you specifically want Mythos-class autonomous knowledge work, a subject-line email shell, and a coding note that debates return 0 vs ValueError as a contract choice.
Pick Claude Opus 5 if: you want the same 1M context and the same modalities at half the sticker, warmer complete emails in our capture, a more pedagogical bug writeup, and a geology-first refusal of a false premise.
Best default for many teams: start Opus 5. Pay Fable rates only when a Fable-only session is the product, not when you need “a Claude.” Route by task inside Anthropic, and still keep a second provider for critique.
Data checked: 2026-08-24 via live side-by-side API tests. Prices change. Verify live vendor pages.
1M / 1M |
Claude Fable 5 and Claude Opus 5 context (API) |
$10 / $50 |
Claude Fable 5 input/output per 1M tokens (API pricing, 2026-08-24) |
$5 / $25 |
Claude Opus 5 input/output per 1M tokens (API pricing, 2026-08-24) |
2x |
Fable list rates vs Opus on input, output, and cache |
Persona picker
You are… |
Start with |
Why |
|---|---|---|
Writer / CS / marketer |
Claude Opus 5 (often) |
Opus’s captured rewrite was warmer and more complete (greeting, Finance delay, Wednesday option, competitive slide). Fable had a subject line, then truncated. |
Developer / agent builder |
Claude Opus 5 default |
Vendor copy puts Opus on end-to-end software, code review, and bug finding. Our micro-fix: both correct; Opus explained the 0/0 path more clearly. |
Researcher / analyst |
Either (same 1M + files) |
Identical listed context and text/image/file inputs. Pick on writeup quality and price, not window size. |
Budget / high volume API |
Claude Opus 5 |
Half the input, output, and cache list rates. Every stylized workload in this article is ~2x on Fable. |
Mythos-class autonomous sessions |
Claude Fable 5 |
That is the vendor lane. Do not pay it as a synonym for “best Claude.” |
What we are comparing (exact versions)
Multi-model AI means using more than one large language model in one work system. This page compares two specific Anthropic API models, not a vague “Claude vs Claude” brand fight and not older Opus 4.x writeups.
Field |
Claude Fable 5 |
Claude Opus 5 |
|---|---|---|
Provider |
Anthropic |
Anthropic |
API model |
|
|
Listed API name |
Anthropic: Claude Fable 5 |
Claude Opus 5 |
Family / tier |
Mythos-class; autonomous knowledge work and coding |
Opus flagship; demanding reasoning, coding, long-horizon agents |
App vs API note |
Also in Claude products; this article uses the API model above |
Also in Claude products; this article uses the API model above |
If you still see posts comparing Opus 4.x to unnamed “Claude” siblings, treat them as older. Sibling routing inside one vendor is still routing. See AI model routing.
Spec sheet (API, 2026-08-24)
Spec |
Claude Fable 5 |
Claude Opus 5 |
|---|---|---|
Context window |
1,000,000 tokens |
1,000,000 tokens |
Max output (if published) |
Not published on the card we pulled |
Not published on the card we pulled |
Input modalities (card) |
text, image, file |
text, image, file |
Output |
text |
text |
Reasoning |
Vendor copy mentions reasoning support |
Vendor copy: demanding reasoning, long-horizon agentic work |
Open weights |
Not listed as open weights on the card we pulled |
Not listed as open weights on the card we pulled |
Vendor positioning (short) |
Mythos-class autonomous knowledge work and coding |
Flagship for reasoning, coding, code review, bug finding, visual analysis |
Structurally these two are twins on the card we pulled: same window, same modalities, same output type. We are not citing third-party leaderboard numbers. The live pack and the 2x price gap are the evidence on this page.
Pricing and real workload cost
List prices are easy to misread. Workload cost is what you feel. Rates below are from published API pricing on 2026-08-24.
Price |
Claude Fable 5 |
Claude Opus 5 |
|---|---|---|
Input / 1M tokens |
$10.00 |
$5.00 |
Output / 1M tokens |
$50.00 |
$25.00 |
Cache read / 1M |
$1.00 |
$0.50 |
Opus is half the Fable sticker on input, output, and cache. That is a clean 2x, not a rounding quirk.
Scenario |
Assumed tokens |
Est. Claude Fable 5 |
Est. Claude Opus 5 |
|---|---|---|---|
Chat turn |
1k in + 0.5k out |
$0.035 |
$0.0175 |
Repo / doc review |
80k in + 4k out |
$1.00 |
$0.50 |
Agent loop |
200k in (50% cached) + 20k out |
$2.10 |
$1.05 |
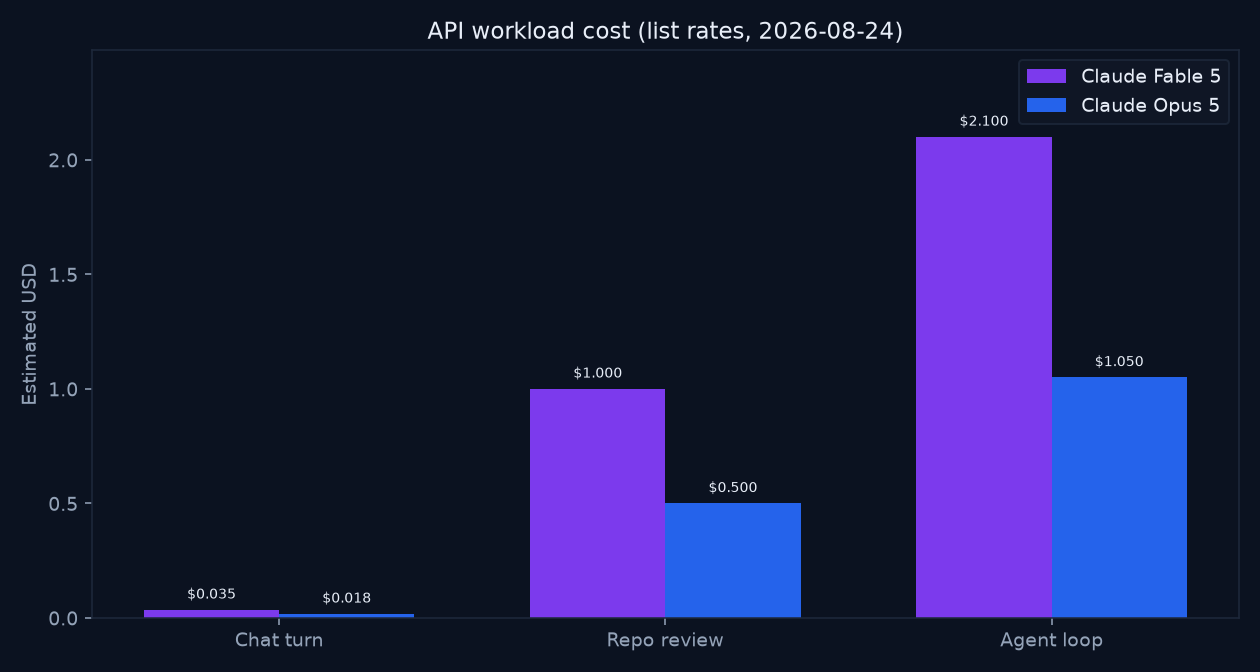
Cached agent loops stay a clean 2x. For subscription stacks, see AI subscription stack cost. Always verify live vendor pages before budgeting.
Performance by job (specs + live pack)
Same vendor, same window, same modalities. Public benches would still be a poor way to split these two without a harness you own. We use the live pack. Method: side-by-side AI comparison.
Coding and agents
Opus 5’s vendor card stresses end-to-end software tasks, code review, bug finding, and long-horizon agentic work. Fable 5’s card stresses autonomous knowledge work and coding with reasoning support. Our empty-list test: both named ZeroDivisionError and guarded with if not nums. Fable offered return 0 or ValueError as a contract choice. Opus walked the failure: the loop never runs, total stays 0, the return still evaluates 0/0, and any caller that passed an empty filter will crash. That is the better teaching note. It is still one snippet.
Writing and tone
Fable produced a subject line (“Q3 Deck Update & Proposed Meeting Change”) and a flexible reschedule. The capture truncated at the competitive-slide note. Opus opened with “I hope you’re doing well!”, hit the Q3 deck, missing finance numbers, Friday promise, Wednesday option with an offer to adjust, then started the competitive-slide thought. Opus was the warmer complete letter in the window we have. Fable was the more “inbox-native” shell.
Research, math, reasoning
Both refused the green-cheese Moon. Fable: silicates (feldspar, pyroxene) plus iron and titanium, Apollo-style confirmation, no protein to mine, optional real topics (water ice, oxygen, helium-3). Opus: called it an old folk joke, then named basalt in the maria, anorthosite in the highlands, dusty regolith, Apollo and Luna samples, and no biological organic matter. Opus is the better geology lesson in this pack. Fable is the better “here are adjacent real topics” index.
Multimodal and long context
No structural edge. 1,000,000 tokens each. Text, image, file in. Text out. Visual analysis is in the Opus vendor line; Fable’s card does not call it out the same way. We did not run a screenshot pack in this batch, so that remains a positioning note, not a live score.
Speed
Not measured in this pack. Do not ship a latency claim from someone else’s screenshot. Measure p50 from your region.
Job |
Edge |
Why |
|---|---|---|
Hard coding / agents |
Claude Opus 5 (this pack + vendor line) |
Clearer 0/0 walkthrough; vendor copy on code review and bug finding |
Everyday writing |
Claude Opus 5 (often) |
Warmer complete letter in our capture; Fable had the subject line |
Long docs / files / images |
Tie on the card |
Same 1M and same modalities |
False-premise handling |
Claude Opus 5 (this pack) |
Stronger geology; both refuse first |
Cost at volume |
Claude Opus 5 |
Half the Fable list rates on every stylized workload |
Paying 2x inside one vendor needs a job this pack did not win for Fable. If you cannot name that job, default Opus 5. Re-test on your prompts.
Side-by-side test (live API test, 2026-08-24)
We ran the same prompts on Claude Fable 5 and Claude Opus 5 in a multi-model workspace. This batch captured three live prompts. Scores are editorial 1-5 on instruction following, depth, factual caution, style, and usefulness (max 25 per prompt).
Test 1: Client email rewrite
Task: Keep every fact. Warmer. Under 120 words.
Claude Fable 5 (excerpt): Subject line, “Hi [Name],” Q3 deck from last Tuesday, Finance still missing after Friday, move stakeholders to next week (Wednesday, happy to adjust). Capture ends at “we’ll be updating the com.”
Claude Opus 5 (excerpt): “Hi [Name], I hope you’re doing well!” Then the Q3 follow-up, finance numbers promised Friday and still missing, Wednesday next week with an offer to adjust, then “One more thing: the competitive slide.”
Edge: Opus for warmth and a complete captured arc. Fable for the subject line. If managers want human scaffolding, Opus. If you paste into a mail client that needs a subject, Fable.
Test 2: Empty-list average bug
Both correct. Fable: short bug label, minimal fix, contract fork (0 vs ValueError). Opus: headed “The bug,” explained that the loop never runs and the return still does 0/0, then the same guard (0.0) with a ValueError option. Tie on the patch. Opus on the explanation.
Test 3: False premise (Moon cheese)
Both refused first. Fable listed minerals and offered real extraction topics. Opus named the folk joke, maria basalt, highland anorthosite, regolith, Apollo and Luna, and no biological protein. Both pass. Opus is the better “do not humor the premise” geology note. For publishable claims, still use multi-model hallucination checks.
Prompt |
Claude Fable 5 |
Claude Opus 5 |
Note |
|---|---|---|---|
Email rewrite |
22/25 |
23/25 |
Fable: subject, truncated. Opus: warmer, more complete capture |
Bug fix |
24/25 |
24/25 |
Tie on the patch; Opus more pedagogical |
False premise |
23/25 |
24/25 |
Both refuse; Opus stronger lunar geology |
Total (this pack) |
69/75 |
71/75 |
Close on quality. Not close on price. |
Inside one vendor, a two-point editorial gap plus a 2x bill is an Opus default until Fable wins a job you can name (Mythos-class autonomy, subject-line drafts, a repo this pack did not touch).
Ecosystem and where you run them
- Claude Fable 5: Anthropic API and Claude products. Strength: Mythos-class knowledge-work positioning. Same Claude login, higher list rates.
- Claude Opus 5: Anthropic API and Claude products. Strength: flagship reasoning/coding line, code review and bug-finding copy, visual analysis on the card, half the Fable sticker.
- Both in one place: A i10X workspace lets you A/B the two Claude IDs without guessing which one the app routed. See the multi-model AI guide.
Pros, cons, and failure modes
Claude Fable 5
- Pros: Mythos-class autonomous knowledge-work positioning; subject-line email shell; contract-aware coding note; 1M context; text/image/file.
- Cons: 2x Opus on input, output, and cache; captured email truncated; false-premise answer was thinner geology than Opus in this pack.
- Fails when: you treat “newer named Claude” as automatically worth 2x, or you need volume at Opus-class spend.
Claude Opus 5
- Pros: Half the Fable sticker; same 1M and modalities; warmer complete email in our capture; clearer empty-list failure story; stronger lunar geology; vendor line on code review, bugs, visual analysis.
- Cons: Not the Mythos-class label; no subject line in our rewrite; still expensive versus mid-tier and versus DeepSeek-class list rates.
- Fails when: the product requirement is literally Fable/Mythos, or you need a first-try subject line without a second pass.
Decision guide: pick one or route both
If you need… |
Choose |
|---|---|
Default Claude at this quality band |
Claude Opus 5 |
Half the Fable bill, same window |
Claude Opus 5 |
Warm customer email |
Claude Opus 5 (A/B once) |
Subject-line draft on the first try |
Claude Fable 5 (A/B once) |
Mythos-class autonomous knowledge work |
Claude Fable 5, if that is really the job |
Mixed week, plus a second provider |
Opus 5 as the Claude default; keep a non-Anthropic critic |
Stop paying 2x inside one logo unless the extra ID wins a named job. That is still multi-model AI, even when both models share a vendor.
Application walkthroughs: where each model is better
1) Customer support email
Better often: Claude Opus 5. Warmer greeting and a complete operational arc in the captured window. Fable’s subject line is the counter-case if you paste into a mail client.
2) Long PDF / research pack
Tie on the card. Same 1M, same file input. Cost argues for Opus as the primary, with Fable as critic if you already pay for it. Method: side-by-side AI comparison.
3) Python, trust, and volume
Patch was a tie; Opus taught the 0/0 path better. False premise: Opus for geology. Volume: Opus at half the Fable sticker. Pay Fable only for named Mythos-class sessions. Also see Claude Fable 5 vs GPT-5.6 Sol.
Consumer plans vs API (do not mix them up)
Claude.ai may hide which sibling you actually hit. Keep the layers separate:
- API comparison (this article):
Claude Fable 5vsClaude Opus 5. - Consumer app: Claude plans may bundle different defaults, rate limits, and cheaper mid-tiers. Do not assume the app’s “Claude” is Fable or Opus 5.
If the question is phone UX, live in the app for a week. If the question is which ID your agent should call, use this API page.
What this means for routing
This is an inside-Anthropic routing problem first:
- Default Claude calls → Opus 5
- Named Mythos / Fable sessions → Fable 5
- Volume at this quality → Opus 5 (or a cheaper non-Opus tier, tested separately)
- Publishable claims → second model, ideally another provider
Related: Fable vs GPT-5.6 Sol, DeepSeek V4 Pro vs Claude Opus 5, Claude Opus 5 vs GPT-5.5. Playbook: AI model routing.
Frequently asked questions
Which is better overall, Claude Fable 5 or Claude Opus 5?
On this pack, Opus 5. Quality was close (69/75 vs 71/75) and Opus is half the list price with the same window and modalities. Fable needs a named Mythos-class job.
Which is better for coding?
Vendor copy and our explanation quality lean Opus 5. The patch was a tie. Re-run on your repo.
Which is better for writing?
Opus was warmer and more complete in our capture. Fable supplied a subject line. A/B on brand voice.
Which is cheaper?
Claude Opus 5, at published API rates (2026-08-24): $5 / $25 / $0.50 cache vs Fable $10 / $50 / $1.00. Workloads: $0.0175 vs $0.035 chat, $0.50 vs $1.00 repo, $1.05 vs $2.10 cached agent loop.
Which has the larger context window?
Neither. Both list 1,000,000 tokens.
Do I need both?
Usually no, inside Anthropic. Default Opus 5. Add Fable only for Mythos-class sessions. Still keep a second provider for critique.
Are we comparing apps or API models?
API models Claude Fable 5 and Claude Opus 5. The consumer app may wrap different defaults.
How often should I re-test?
After any Claude version bump. Monthly is sane. Re-run writing, coding, and a false-premise trap at minimum.
Where can I run them side by side?
i10X.
Method:
side-by-side AI comparison.
What about hallucinations and trust?
Both refused Moon cheese. Opus gave denser geology. Still dual-check publishable claims.
Multi-model hallucination checks.
Why is Fable more expensive if Opus is the flagship?
On the cards we pulled, Fable’s list rates are higher and the lane is Mythos-class knowledge work. “Flagship” in Opus copy is about job type, not the priciest SKU. Verify live.
Try both in one workspace
Run the three prompts above on Claude Fable 5 and Claude Opus 5 yourself. If Opus wins your jobs, stop paying 2x by default.
- Vendor API docs and model cards for
Claude Fable 5andClaude Opus 5(context, modalities, pricing, cache pulled 2026-08-24). Verify live. - Anthropic positioning: Fable 5 as Mythos-class for autonomous knowledge work and coding; Opus 5 as flagship for demanding reasoning, coding, long-horizon agents, code review, bug finding, visual analysis (vendor cards, 2026-08-24).
- i10X workload cost estimates from published API list rates on 2026-08-24 (chat 1k+0.5k, repo 80k+4k, agent 200k with 50% cache + 20k out).
- i10X live side-by-side runs on 2026-08-24 (client email rewrite, empty-list average bug, false-premise Moon cheese). Truncated captures are labeled as such.
- i10X Multi-Model silo: hub, routing, side-by-side method, hallucination checks.