
Quick Take
- Summary: Google has cemented Gemini as its omnipresent AI infrastructure, deploying a tiered model ecosystem that spans massive cloud environments, enterprise workspaces, and local edge devices.
- What happened: Transitioning fully away from the experimental Bard, Google launched the Gemini 1.5 Pro, 1.5 Flash, and Nano, aggressively rolling it out across Vertex AI, consumer apps, and notably, via over-the-air (OTA) updates to edge endpoints like Renault vehicle fleets.
- Why it matters now: Gemini represents a shift from monolith LLMs to an “intelligence routing” strategy; by tiering models, Google is actively addressing data center compute bottlenecks and inference costs. From what I’ve seen, this proves the future of AI scaling relies on fitting the right model to the right compute footprint.
- Who is most affected: Enterprise CTOs calculating Total Cost of Ownership (TCO) across cloud and edge, multimodal app developers optimizing for latency, and rival AI labs (OpenAI, Anthropic) competing against Google’s unrivaled distribution network.
- The under-reported angle: While the media fixates on consumer chat apps and Workspace integrations, Gemini’s deployment into the automotive sector and local Android distributions signals a massive architectural shift toward offline, distributed edge inference – bypassing the cloud entirely.
Deep Dive
Have you ever stopped to consider what actually changes when an AI rollout moves beyond the headlines? Google’s rollout of the Gemini ecosystem is not just a product rebrand; it is a full-stack restructuring of how intelligence is served, priced, and executed. While mainstream visibility is high – evidenced by AI Overviews dominating Google’s search results – the underlying narrative is fundamentally about compute optimization. By splitting the architecture into Gemini 1.5 Pro for heavy, long-context reasoning, 1.5 Flash for high-throughput, low-latency tasks, and Gemini Nano for on-device execution, Google is orchestrating a masterclass in infrastructure triage.
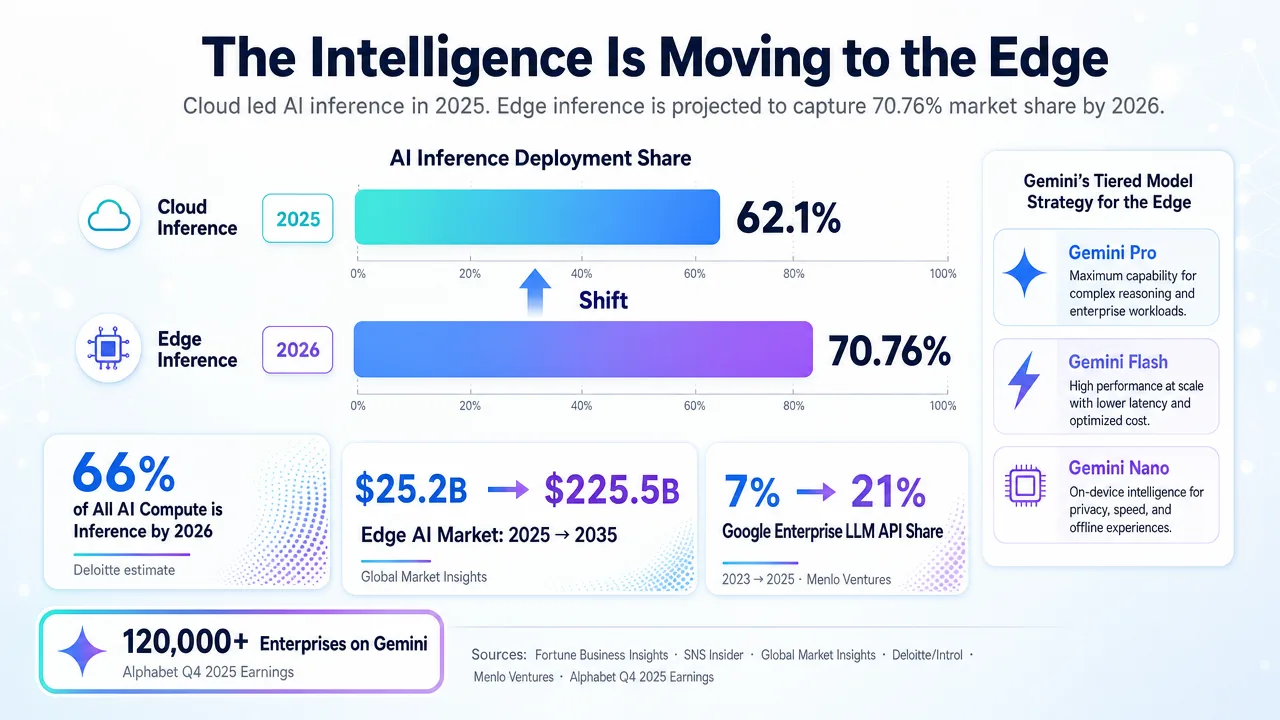
Much of the existing coverage reads like vendor product manuals, highlighting Workspace plugins or Cloud pricing tiers without identifying the core technical tensions. Enterprise buyers are wrestling with Total Cost of Ownership (TCO), latency, and data privacy. Gemini 1.5 Flash is Google’s direct infrastructural response to these pain points. By offering a smaller, heavily distilled model that retains multimodal capabilities, Google provides a vital pressure release valve for its TPU/GPU clusters – allowing developers to scale applications without melting cloud budgets or facing crippling latency.
The most revealing shift, however, is happening far from the data center. Automotive World’s reporting on Renault deploying Google Gemini via over-the-air (OTA) updates exposes Google’s most lethal structural advantage: hardware distribution. Deploying Gemini Nano directly into an infotainment system or a smartphone represents a strategic pivot toward edge inference. This allows complex, multimodal queries (like voice and vision) to run locally, mitigating latency, bypassing spotty cellular grids, and drastically reducing the power and water demands on central AI data centers.
This dual-pronged strategy – dominating the cloud with Vertex AI integrations while flooding the edge with Nano – puts intense pressure on pure-play model developers like OpenAI and Anthropic. A CTO evaluating an AI stack is no longer just looking at base model benchmarks against GPT-4o or Claude 3.5 Sonnet. They are evaluating integration friction. Gemini’s native embedding into enterprise security domains, data lakes, and device-level operating systems changes the math from “who has the smartest model” to “who can run intelligence most efficiently where my data already lives.”
Ultimately, Gemini is stress-testing a new paradigm for the AI race. True scale will not be achieved solely by building larger gigawatt-guzzling facilities, though those remain critical for training. Instead, the real enterprise moat will be defined by orchestration: seamlessly routing multimodal workloads between the cloud and the edge, balancing context length, cost, and latency in real-time.
Stakeholders & Impact
- AI / LLM Competitors — High impact. Forces OpenAI and Anthropic to compete not just on model intelligence, but on edge distribution and ecosystem lock-in.
- Enterprise & CTOs — High impact. Multi-tiered models (Pro, Flash, Nano) require new TCO calculation frameworks and routing logic to optimize cloud vs. edge inference.
- Automotive & Hardware — High impact. OTA deployments like Renault’s demonstrate that legacy hardware is becoming a decentralized compute cluster for local AI execution.
- Cloud Infrastructure — Significant impact. Offloading inference to edge devices (Nano) acts as a critical load-balancing strategy for Google’s power-constrained data centers.
About the analysis
Researched and written with AI assistance under the editorial responsibility of the i10X News team. The title image is an AI-generated illustration. Read our AI Use Policy. Spotted an error? Request a correction.
This independent analysis synthesizes Google’s official model documentation, enterprise Cloud and Workspace roadmaps, and automotive industry deployments to map the broader strategic footprint of Gemini. It is designed for technical decision-makers, CTOs, and AI developers navigating integration costs, edge-vs-cloud architectures, and the shifting competitive dynamics of the LLM market.
i10x Perspective
Google is no longer just building chatbots; they are building an ambient intelligence grid. By systematically embedding tiered models from server racks down to vehicle dashboards, Google is betting that the ultimate winner of the AI race won’t just have the highest benchmarks, but the lowest friction of inference. Over the next five years, watch how this “edge-first” inference strategy impacts energy demand projections – if millions of devices absorb the compute load locally, the current panic over data center power capacity might find an unexpected, decentralized relief valve.
Google is no longer just building chatbots; they are building an ambient intelligence grid. By systematically embedding tiered models from server racks down to vehicle dashboards, Google is betting that the ultimate winner of the AI race won’t just have the highest benchmarks, but the lowest friction of inference. Over the next five years, watch how this “edge-first” inference strategy impacts energy demand projections – if millions of devices absorb the compute load locally, the current panic over data center power capacity might find an unexpected, decentralized relief valve.






