Google AI just released a 10-minute series on Generative AI. It aims to pull back the curtain on large language models by walking through the pipeline from raw text to tokens, embeddings, and autoregressive generation. At the same time, by getting developers and product teams on the same page about the inference pipeline, Google is quietly tackling the huge infrastructure and latency costs that come with sloppy AI deployments.
Quick Take
- The release: Google AI drops a compact, high-density curriculum explaining the inner workings of LLM inference, from tokenization to output probabilities.
- Why it matters now: As enterprise AI shifts from prototype to production, misunderstanding the mechanical flow of an LLM leads to catastrophic cost, context window abuse, and latency overruns.
- The underlying shift: The AI market is maturing; developers no longer just want to know how to prompt an LLM, but what infrastructure runs under the hood to optimize their applications.
- Who is most affected: AI application developers, cloud infrastructure engineers, and technical product managers attempting to balance token economics with model performance.
What happened
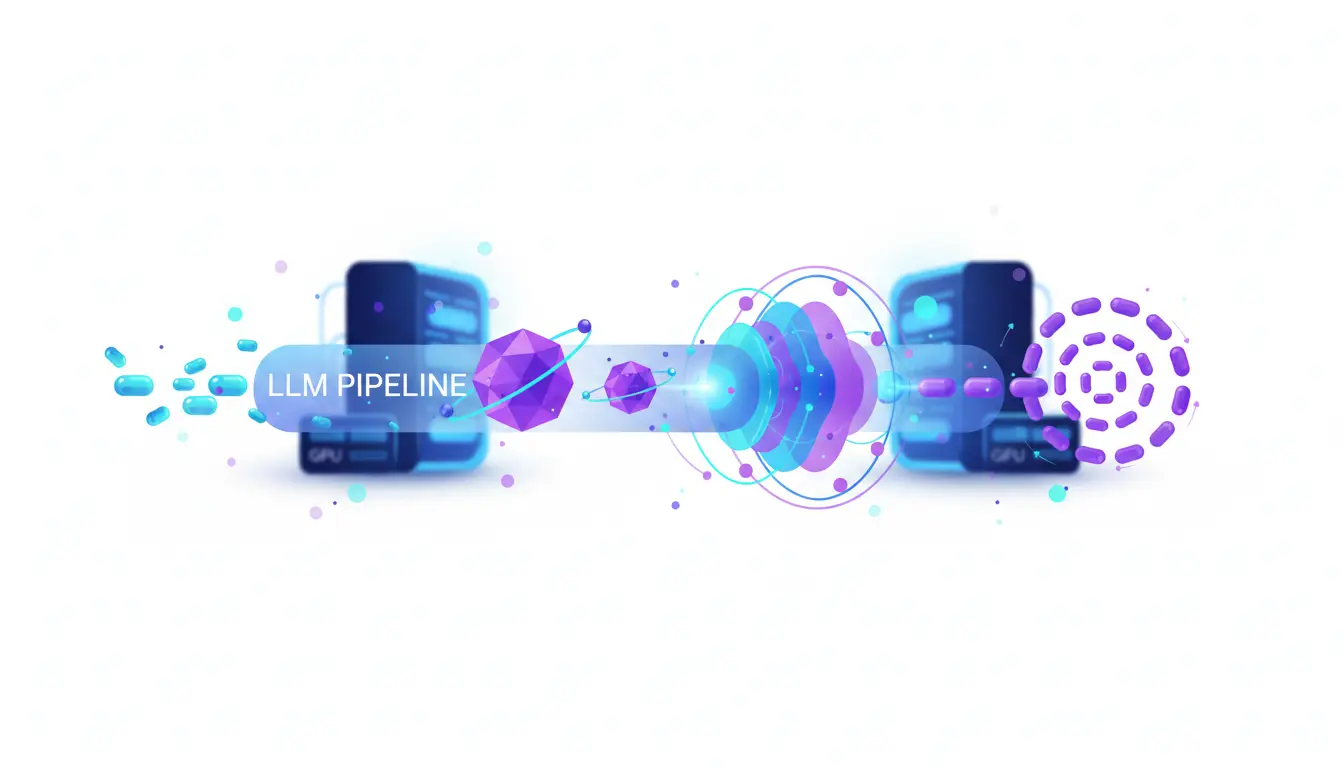
A newly launched 10-minute Generative AI series by Google AI provides a rapid, step-by-step walkthrough of the Large Language Model (LLM) inference pipeline. The curriculum targets a critical knowledge gap in the market, moving beyond basic prompt engineering to explain the mechanical flow of generative models. It details exactly how raw text is chopped into discrete token IDs, converted into high-dimensional embedding vectors, and fed into the model.
Instead of hiding the math or relying on generic metaphors, the series tackles the fundamental architecture of modern AI. It maps the journey of a prompt through positional encoding and self-attention mechanisms, culminating in the generation of logits and softmax probabilities. Finally, it illustrates how autoregressive decoding selects and spits out the final text, one token at a time, before mapping it back into human-readable language.
Why it matters now
Understanding the LLM pipeline is no longer just an academic exercise; it is the fundamental basis of AI economics. When developers lack clarity on how tokenization works, they misuse context windows, driving up API costs and consuming unnecessary compute on cloud grids. The distinction between the “prefill” phase (reading the input prompt in parallel) and the “decode” phase (generating the output sequentially) directly dictates application latency and determines how companies scale their GPU clusters.
Furthermore, as the AI arms race intensifies, educating the developer ecosystem is a strategic moat. By standardizing the terminology around subword tokens, embeddings, and transformer layers, Google is cultivating a workforce better equipped to build efficiently on cloud infrastructure. When developers understand that generating a single token requires passing vectors through massive transformer layers built around attention mechanisms, they optimize their workloads – ultimately relieving pressure on constrained data centers, memory bandwidth, and GPU supply chains.
Who is most affected
The ripple effects of this foundational education primarily impact those building, deploying, and financing AI applications.
| Stakeholder | Impact | Why |
|---|---|---|
| AI App Developers | Tighter optimization | Understanding subword tokenization and decoding strategies (top-k, top-p, temperature) allows for cheaper, faster model interactions. |
| Cloud Infra Providers | Smoother compute loads | Applications built with mechanical sympathy for LLMs use context windows efficiently, easing memory bandwidth demands like KV cache limits. |
| Technical PMs | Better product scoping | Realizing that LLMs generate output autoregressively explains why responses must stream, fundamentally altering UX design. |
About the analysis
Researched and written with AI assistance under the editorial responsibility of the i10X News team. The title image is an AI-generated illustration. Read our AI Use Policy. Spotted an error? Request a correction.
This is an independent i10x analysis exploring the intersection of AI education and infrastructure economics, tailored for CTOs, AI developers, and system architects.
i10x Perspective
We are transitioning from the “magic” phase of AI into the “mechanical” phase. As models scale, the brute-force approach to inference is hitting a wall of energy consumption and hardware limitations. Initiatives that demystify the LLM pipeline signal a broader industry pivot: the next generation of AI dominance will not just be won by the company with the biggest model, but by the ecosystem that most deeply understands the granular mechanics of tokens and attention layers to extract maximum intelligence per watt.