CLM-8B: Open-Source Contrastive Model for Fast AI Agents
⚡ Quick Take
Contrastive scoring is quietly replacing token generation as the engine for high-speed AI agents, and CLM-8B just open-sourced the blueprint.
Contrastive-LM has released CLM-8B, an open-source "System One" model designed specifically for agentic decision-making, offering a radical speed advantage over traditional generative models.
Summary: Contrastive-LM has released CLM-8B, an open-source "System One" model designed specifically for agentic decision-making, offering a radical speed advantage over traditional generative models.
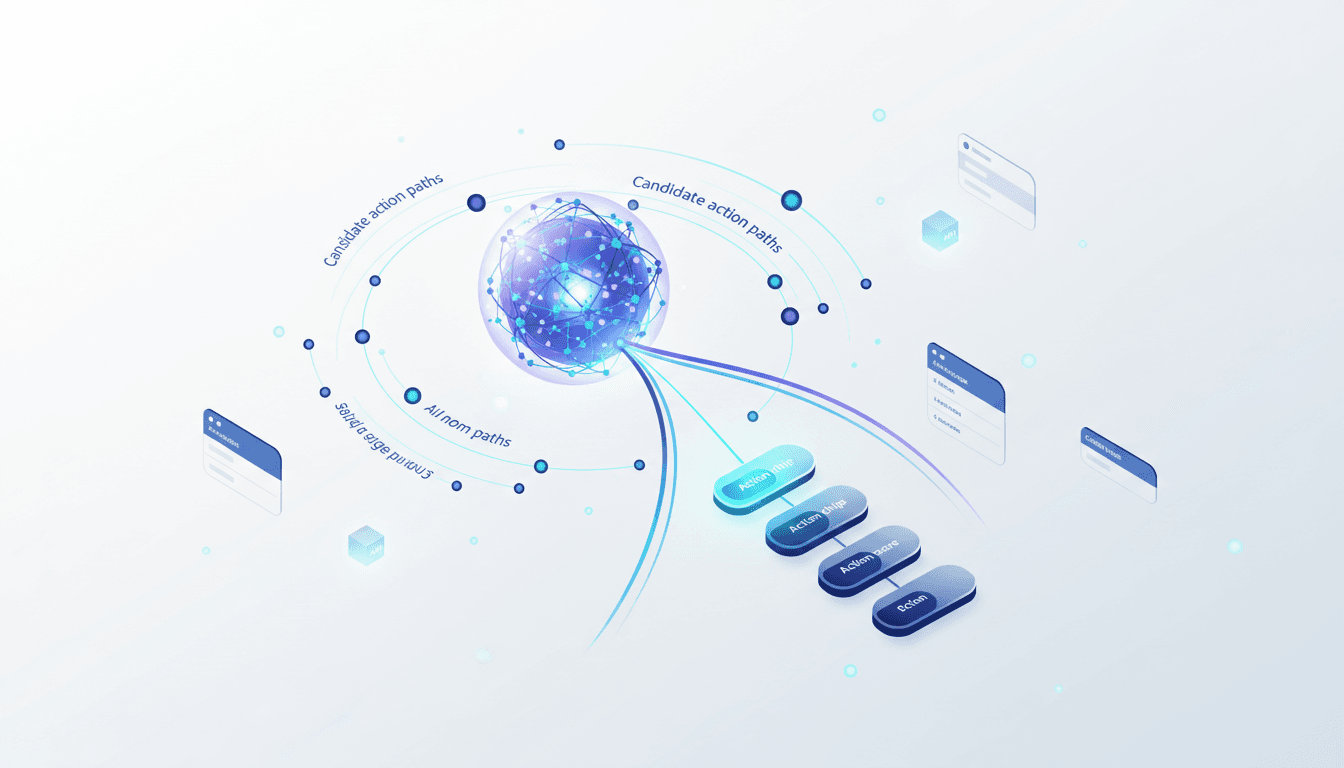
What happened: By utilizing a frozen Qwen3-8B encoder paired with dual projection heads trained via a contrastive InfoNCE objective, CLM-8B scores candidate actions against a given state rather than generating text. This architecture allows it to run up to 9× faster than proprietary leaders like Jev in zero-shot tests on benchmarks like DeepSWE and Terminal-Bench.
Why it matters now: The AI industry is hitting a latency wall; generating tokens to evaluate dozens of possible agent actions (like UI clicks or API calls) is simply too slow and expensive for real-time applications. CLM-8B proves that decoupled, action-scoring models are the scalable path forward for autonomous workflows.
Who is most affected: AI agent developers, ML infrastructure engineers optimizing inference pipelines, and enterprise CTOs looking to reduce the Total Cost of Ownership (TCO) for complex, multi-step agent deployments.
The under-reported angle: Most coverage focuses on the 9× speedup, but the real unlock is action caching. Because CLM-8B isolates state and action embeddings, engineers can pre-compute and cache the embeddings for thousands of possible actions, only recalculating the current state on the fly—a paradigm shift for scaling computer-use agents.
🧠 Deep Dive
Text generation is fundamentally the wrong paradigm for fast, repetitive agentic decision-making. When an AI agent needs to choose between fifty possible UI interactions or API calls, forcing an LLM to auto-regressively generate the reasoning and the selection creates massive latency bottlenecks. CLM-8B bypasses this entirely. By functioning as a "System One" brain—a fast, reflexive scorer rather than a slow, deliberate writer—it evaluates states and actions in a shared embedding space, dramatically accelerating the agentic loop.
The architecture is a masterclass in lightweight efficiency. Contrastive-LM didn't pretrain a massive new foundation model from scratch. Instead, they took a frozen Qwen3-8B backbone and strapped on two small projection heads (state and action). Trained on internet-scale data, Nemotron Q&A, and synthetic hard negatives, these heads use a contrastive InfoNCE objective to perfectly align what the agent sees with what the agent should do. The result is a model that drops cleanly onto a single GPU using standard vLLM stacks, bypassing the immense compute overhead normally required for Jev-class decision models.
From what I've seen, competitor coverage and social chatter—such as Jacky Kwok’s WikiRacing demos—highlight the 9× speedup over Jev, but they largely miss the broader market context. We are currently witnessing a Cambrian explosion of "Jev clones" in 2026 as developers scramble for viable decision models. Amidst this noise, CLM-8B distinguishes itself not just with speed, but with its Apache-2.0 licensed projection heads and verifiable anchors in rigorous benchmarks like DeepSWE and Terminal-Bench 2.1. It acts as a highly calibrated verifier that integrates seamlessly into existing tool-calling stacks.
That said, a significant gap remains in the ecosystem's understanding of Total Cost of Ownership (TCO) for these models. While CLM-8B solves the immediate inference latency problem, production-grade deployments will require robust infrastructure playbooks. Optimizing the number of candidate actions evaluated simultaneously, managing action-reuse caching, and fine-tuning the verifier for highly specific enterprise domains will separate the toy demos from enterprise-grade agent swarms.
Ultimately, CLM-8B bridges the gap between traditional RAG rerankers and fully autonomous agent brains. By applying the mathematics of text-ranking to the realm of physical and digital actions, it provides a blueprint for how future AI systems will navigate complex environments without getting bogged down by the weight of their own generation.
📊 Stakeholders & Impact
Stakeholder / Aspect | Impact | Insight |
|---|---|---|
Agent Developers | High | Unlocks real-time, low-latency decision loops by replacing token generation with rapid state-action scoring arrays. |
AI Infra Providers | Medium–High | Shifts compute demand away from massive auto-regressive generation toward high-throughput embedding generation and caching. |
Enterprise Teams | High | Drastically reduces the TCO of deploying agentic workflows by enabling single-GPU serving via vLLM. |
Open Source AI | Significant | The Apache-2.0 license commoditizes a core component of the "System One" stack, challenging proprietary Jev-class models. |
✍️ About the analysis
This independent, research-based analysis synthesizes current market coverage, Hugging Face metadata, and benchmark reports (DeepSWE, Terminal-Bench) surrounding the CLM-8B release. It is designed for CTOs, ML engineers, and AI product teams evaluating the shift from generative to contrastive models in agent architectures.
🔭 i10x Perspective
The release of CLM-8B signals the inevitable decoupling of AI reasoning. We are moving toward a dual-engine future: massive, deliberate LLMs serving as "System Two" for complex planning, and fast, contrastive models like CLM-8B acting as the "System One" nervous system for rapid execution. As these scoring models commoditize, the proprietary moat for companies building closed Jev-class action models will evaporate. Over the next five years, the competitive frontier will shift away from who can build the smartest single model, to who can choreograph the most efficient interplay between generation and contrastive scoring on the edge.
Related News
Gemini 4 Post-Training: Google's Agentic AI Shift
DeepMind confirms Gemini 4 has entered post-training, focusing on persistent agents and long-context capabilities for software development. Discover the enterprise implications and infrastructure challenges.
AI Safety: From Academic Theory to Enterprise Engineering
AI safety is moving from existential risk research to practical mandates like guardrails and compliance. Learn how regulators and LLMOps teams are implementing measurable controls. Explore the guide.
Generative UI Standardization: Agent-Orchestrated Components
The AI industry shifts to governed Generative UI frameworks, replacing fragile LLM HTML with structured component catalogs and intent protocols. Learn how this improves security and performance for enterprise apps.