Quick Take
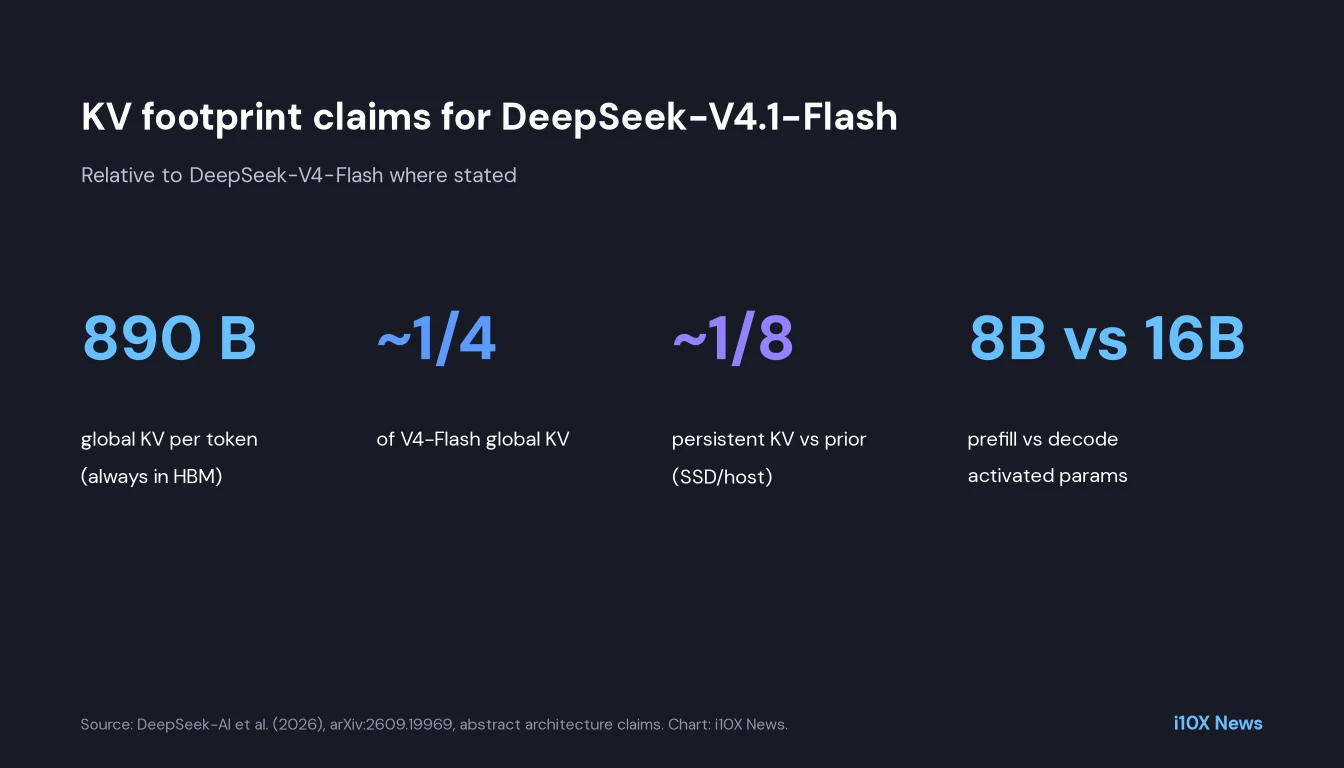
- The finding: DeepSeek-V4.1-Flash, a 552B MoE with up to 1M context, activates 16B parameters per token in decode but only 8B during prefill via a Causal Encoder-Decoder design.
- KV compression: Cross-layer reuse in CSA2 plus FP4 KV caching cuts the always-in-HBM global KV footprint to 890 bytes/token — about 1/4 of DeepSeek-V4-Flash.
- Persistent store: SWA Bounded Replay further reduces the always-on-SSD/host persistent KV footprint to roughly 1/8 of the prior generation.
Long-horizon agents make workloads input-heavy: prefill stays expensive and huge KV caches strain HBM, SSD and bandwidth. DeepSeek-AI’s V4.1-Flash technical report attacks those bottlenecks together.
What the study shows
The authors report V4.1-Flash-Base knowledge/reasoning/coding comparable to V4-Pro-Base with 5–10% gains on held-out evals, using 1/3 total and 1/4 activated parameters. They claim parity with closed-source frontiers on most benches and capability for over 95% of real-world tasks.
- Vision path: 3×3 pixel-unshuffle cuts visual tokens 9×, supporting ~1344×1344 inputs.
- Agent-oriented economics: Asymmetric prefill/decode activation targets input-heavy agent traffic.
Why it matters: agents are prefill-bound
If agents spend most tokens on context, cutting prefill activation and KV bytes moves the cost curve more than raw decode FLOPs.
Method in brief
CED architecture, CSA2 sparse attention with reuse, FP4 KV, SWA Bounded Replay deployment path.
What remains open
- Vendor report: All claims from DeepSeek-AI; independent replication pending.
- “95% of real-world tasks”: Broad claim — treat as author framing.
Context
Related long-context MoE work in Efficiency & Training.
What it means for agent platforms
- Separate prefill and decode budgets: Asymmetric activation helps.
- Compress persistent KV aggressively: SSD/host footprints dominate multi-session agents.
- Validate quality independently: Vendor benches need third-party checks.
About the analysis
Researched and written with AI assistance under the editorial responsibility of the i10X News team. The title image is an AI-generated illustration. Read our AI Use Policy. Spotted an error? Request a correction.
This article is based on the full text of the preprint “DeepSeek-V4.1-Flash: Pushing the Limits of KV Cache Compression” (arXiv:2609.19969v1, submitted September 17, 2026). All numbers are taken from the paper’s text, tables and figures; i10X did not rerun the experiments. The paper is distributed under arXiv’s non-exclusive license, so i10X does not reproduce its figures; the chart was drawn by i10X from numbers reported in abstract architecture claims.
i10x Perspective
V4.1-Flash is less a new intelligence story than a deployment story: fewer bytes, asymmetric compute, million-token agents. If the quality claims hold, this is how open MoEs stay cost-competitive for tool-heavy workloads.