Quick Take
- The finding: NVIDIA researchers show that Claude Opus 4.5 and GPT 5.6 Sol lose little to no accuracy when their context is compacted into short windows, across 13 long-horizon and long-input benchmarks.
- The cost angle: On open-weight models, serving a 256K context window costs 3.6× to 7× more per generated token than a 16K window, so short contexts could be far cheaper to run.
- The surprise: Even one action per context barely hurt coding agents, and on long-document tasks short contexts with selective reading often beat the full-context baseline by large margins.
Long context windows are one of the main selling points of frontier models. A new preprint from NVIDIA, titled “You don’t need long context”, questions whether agents actually need them. Peter Belcak, Pavlo Molchanov and ten co-authors test what happens when models must keep their working context short, by regularly summarizing their own history, and conclude that the long-context race may be solving the wrong problem.
What the study shows
The team compared each model’s normal full-history run with “compaction” settings: once the conversation hits a threshold, the model writes a summary and continues in a fresh, short context. Settings ranged from a 128K limit down to 16K, compacted at 12K.
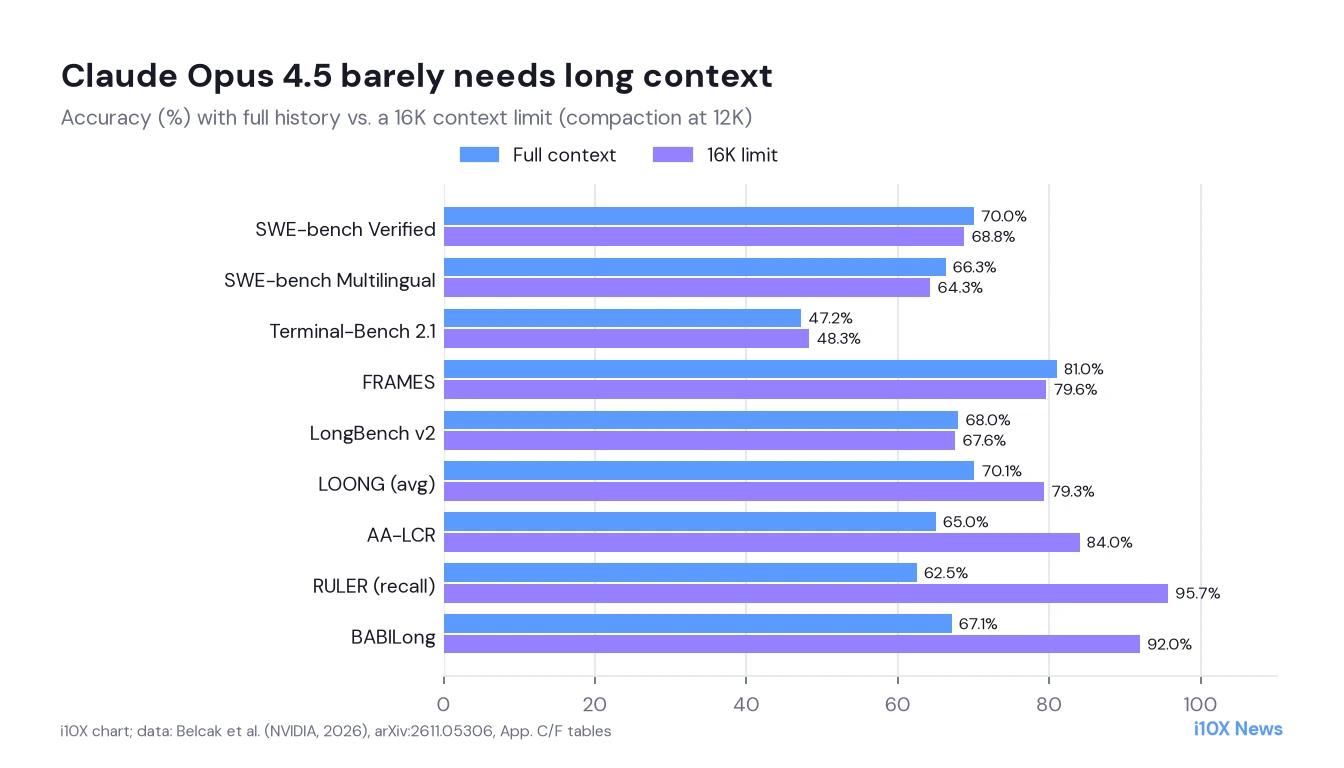
- Long-horizon tasks: On six benchmarks, including SWE-bench Verified, Terminal-Bench 2.1, FRAMES and τ²-bench, accuracy changed by −3.7 to +5.6 percentage points for Opus 4.5 and −3.3 to +4.4 points for GPT 5.6 Sol. For either model, no more than 5 of 22 configurations lost more than 2 points.
- Long-input tasks: On seven benchmarks such as LongBench v2, LOONG, AA-LCR, RULER and BABILong, long inputs were stored as files that the agent read selectively. Opus 4.5 changed by −0.4 to +40.0 points, GPT 5.6 Sol by +1.0 to +30.9 points. On RULER, Opus rose from 62.5% to 95.7% recall at the tightest limit.
- Serving cost: Measured with vLLM on H100 GPUs, a 256K window costs 3.6× (GLM 5.2), 5.6× (Kimi K2.6) and 7× (Qwen 3 Coder Next) more per output token than a 16K window. On a local DGX Spark, token latency roughly doubled for several models across the measured context lengths.
- Open-weight models are fragile: All tested open models lost SWE-bench Verified accuracy at the tightest setting. Qwen 3 Coder Next collapsed from 53.0% to 3.6%, while Qwen 3.6 27B (68.6% to 65.0%) and MiniMax M2.7 (72.6% to 67.8%) held up best.
The most radical test was “single-action contexts”: the model takes one step, writes a compact state and hands over to a fresh context. Peak context dropped from 130K–200K tokens to 15K–37K, with a median of 7K–9K.
| Model and benchmark | Full history | One action per context | Best compaction setting |
|---|---|---|---|
| Opus 4.5, SWE-bench Verified | 70.0% | 70.2% | 74.8% |
| Opus 4.5, Terminal-Bench 2.1 | 47.2% | 51.8% | 52.8% |
| GPT 5.6 Sol, SWE-bench Verified | 84.4% | 82.4% | 88.8% |
| GPT 5.6 Sol, Terminal-Bench 2.1 | 87.6% | 84.3% | 88.8% |
Why it matters: Context length is a cost driver, not just a feature
Retail API prices are flat per million tokens, so users rarely see that late tokens in a long context are much more expensive to generate. If agents work well with short contexts, providers and teams running their own models could serve the same workloads with less memory and fewer GPUs. The authors argue this rivals or exceeds savings from methods such as aggressive quantization.
The study is broad. It covers 13 benchmarks, two frontier closed models, five open-weight models and two agent harnesses. It also documents what a useful compaction summary contains: a verbatim copy of the task, the current state and plan, relevant artifacts and completion criteria. A brief for the next step works better than a narrative of what happened.
Method in brief
- Regimes: Full-history baseline, compaction at fixed thresholds, and single-action contexts that carry only a semantic state.
- Harnesses: mini-swe-agent v2.4 for software tasks and a minimal in-house agent with file tools such as grep and sed for long-input tasks.
- Models: Claude Opus 4.5 and GPT 5.6 Sol as main models, plus Qwen 3.6 27B, Qwen 3 Coder Next, Gemma 4 31B, Step 3.7 Flash and MiniMax M2.7.
- Costs: Cloud serving measured at $3.85 per H100-hour, and an “estimated optimized retail cost” model that scales API prices with context length.
What remains open
- Savings are partly hypothetical: The headline savings (2.2× to 8.8× for Opus 4.5 on long-horizon tasks) use the authors’ price model, not real bills. At today’s nominal API prices, compaction lowered Opus 4.5’s SWE-bench Verified cost from $420.00 to $295.75 but raised GPT 5.6 Sol’s from $167.68 to $188.96. Long-input tasks were cheaper even at nominal prices, for example LOONG with Opus 4.5 fell from $1,367.50 to $502.10.
- Apples and oranges on long inputs: The big long-input gains compare full-context reading against an agent that searches files. That tests a different workflow, not only a shorter context.
- Single runs: Results come from single runs without confidence intervals, so small differences of 1 to 2 points may be noise.
- Not all tasks: The authors concede that their results do not rule out tasks that truly benefit from long context.
- Industry paper: All authors work at NVIDIA. There is no code release, no limitations section and no conflict-of-interest statement. It is a preprint without peer review.
Context: From bigger windows to smarter memory
Model makers such as Anthropic and OpenAI have pushed context windows ever higher, while coding agents increasingly rely on compaction to run for hours. Earlier i10X coverage showed the risks of that step, with agents laundering approvals during compaction. The NVIDIA team now proposes “semantic state space models”: models post-trained to compress their own state and hand it to a fresh instance. More research is collected under Efficiency & Training.
What it means for teams building agents
- Try compaction before buying context: For coding and research agents, a 16K to 32K working window with good summaries may perform about as well as a full history.
- Put long inputs into files: Let the agent grep and read selectively instead of pasting a whole document into the prompt.
- Write structured hand-offs: Include the task verbatim, the current plan and the completion criteria in every summary.
- Test open models carefully: Some open-weight models break down under tight limits, so check your model before you cut context.
About the analysis
Researched and written with AI assistance under the editorial responsibility of the i10X News team. The title image is an AI-generated illustration. Read our AI Use Policy. Spotted an error? Request a correction.
This article is based on the full text of the preprint (arXiv:2611.05306v1, submitted November 3, 2026), including the appendix. All numbers come from the paper; i10X did not rerun the benchmarks. The chart was drawn by i10X from the appendix tables, because the paper carries an all-rights-reserved notice. AI tools assisted with research and drafting; the selection, fact-checking and final editing were done by the i10X editorial team.
i10x Perspective
The paper is self-interested in one way: NVIDIA benefits if more AI runs on local hardware like the DGX Spark. Still, the data are hard to ignore. For users of Claude and other frontier agents, smarter memory management may deliver more than another jump in context length.