Quick Take
- The finding: On-policy distillation that extrapolates an implicit output-space reward is unstable because the LM head attenuates representation changes anisotropically.
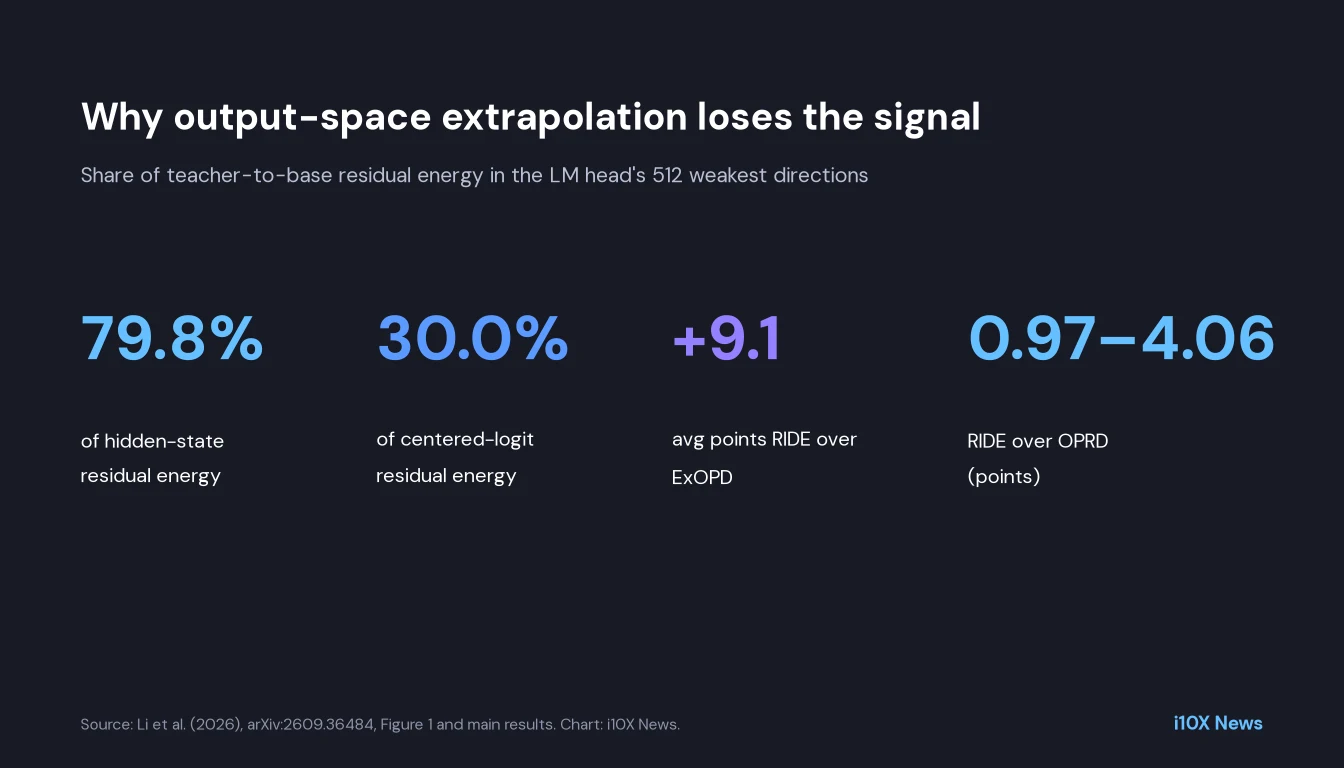
- The fix: RIDE extrapolates the RL-induced residual in hidden space at every layer. It improves over OPRD on every pair and over ExOPD by 9.1 points on average.
- The smoking gun: The head’s 512 weakest directions carry 79.8% of the teacher-to-base residual’s hidden energy but only 30.0% of its centered-logit energy.
On-policy distillation trains a student on its own trajectories to match a teacher. Generalized variants try to surpass the teacher by extrapolating an implicit reward in output space — and often become unstable. Researchers from USTC, Rutgers, Zhejiang University and collaborators propose doing the extrapolation where RL actually moved the model: in representations.
What the study shows
Across four base/RL-teacher pairs, ExOPD can fall below its teacher and even below untouched students when the teacher moved little. RIDE steadily improves for λ in 0.75–1.35 with format scores of 94–97%.
- Margin over OPRD isolates the idea: Because RIDE shares OPRD’s protocol and differs only in target, its 0.97–4.06 point gains attribute to residual extrapolation.
- ExOPD fails when RL moved a lot or a little: On an R1-Distill pair where RL moved the teacher 16.3 points, ExOPD underperforms output-space matching baselines; on small-move pairs it can fall 14.1 points below the student.
Why it matters: distill where the update lives
If RL rewires mid-layers but the head squashes that signal, matching logits alone under-supervises the student.
Method in brief
Measure RL-induced direction vs base at every layer; extrapolate with coefficient λ; compare Avg@16 against OPD, OPRD and ExOPD.
What remains open
- Teacher must be RL-shifted: Method assumes a measurable residual from a base checkpoint.
- Hyperparameter λ: Too large λ eventually hurts ExOPD-style runs; RIDE’s safe band is reported but still tuned.
Context
Related distillation work in Reasoning and Efficiency & Training.
What it means for distillation stacks
- Keep base checkpoints: You need them to estimate the RL direction.
- Prefer representation targets: When extrapolating past the teacher.
- Monitor format collapse: A sign λ is too aggressive.
About the analysis
Researched and written with AI assistance under the editorial responsibility of the i10X News team. The title image is an AI-generated illustration. Read our AI Use Policy. Spotted an error? Request a correction.
This article is based on the full text of the preprint “The Teacher Is a Direction, Not a Destination: Extrapolating RL-Induced Representation Residuals in On-Policy Distillation” (arXiv:2609.36484v2, submitted September 29, 2026). All numbers are taken from the paper’s text, tables and figures; i10X did not rerun the experiments. The paper is distributed under arXiv’s non-exclusive license, so i10X does not reproduce its figures; the chart was drawn by i10X from numbers reported in Figure 1 and main results.
i10x Perspective
RIDE’s metaphor is right: the teacher is a direction, not a destination. Extrapolating that direction in the space where RL left fingerprints is a cleaner idea than amplifying noisy token-level reward ratios.