Quick Take
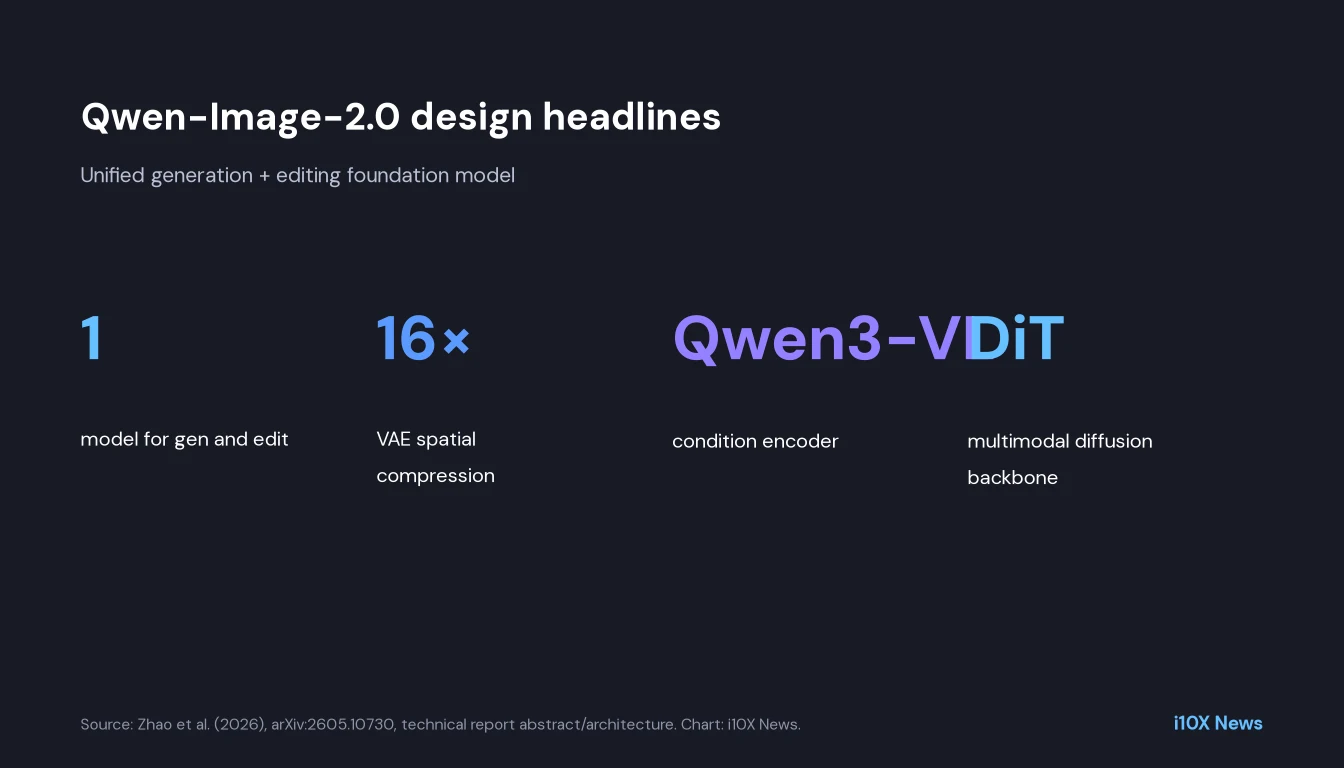
- The finding: Qwen-Image-2.0 is an omni image foundation model that unifies generation and editing in one framework conditioned by Qwen3-VL.
- Compression: A custom VAE with 16× spatial downsampling (vs typical 8× open VAEs) hits SOTA reconstruction metrics on ImageNet-1k at 256 while accelerating DiT training.
- What it targets: Ultra-long text, complex multilingual typography, high-res photorealism, robust instruction following and efficient deployment.
Most image systems either generate or edit well — rarely both at frontier quality in one checkpoint. The Qwen Team’s Image-2.0 report argues creative workflows need a single model that keeps semantic accuracy, typography and layout coherent.
What the study shows
Multimodal Diffusion Transformer with interleaved multi-image inputs; multi-stage training from 256p through high-res SFT and RL. Residual autoencoding, enlarged latent channels and semantic alignment loss balance compression and fidelity.
- RL stage: Qwen-Image-2.0-RL improves texture fidelity and realism for T2I and editing scenarios per authors.
- Data filters: Broken-file, resolution, similarity and token-length filters shape training corpora.
Why it matters: workflow without switches
Creative tools lose users at pipeline boundaries. A unified gen/edit model is the product shape studios want.
Method in brief
Qwen3-VL encoder + MM-DiT; customized multi-stage training; ImageNet VAE evals.
What remains open
- Vendor report: Independent third-party benches needed for absolute ranking.
- Compute footprint: High-res training details matter for reproducers.
Context
Related image generation in Multimodal.
What it means for creative AI stacks
- Evaluate editing and T2I together: Same checkpoint.
- Watch typography suites: Long multilingual text is the differentiator.
- Consider 16× VAEs: Training speed vs detail trade-off.
About the analysis
Researched and written with AI assistance under the editorial responsibility of the i10X News team. The title image is an AI-generated illustration. Read our AI Use Policy. Spotted an error? Request a correction.
This article is based on the full text of the preprint “Qwen-Image-2.0 Technical Report” (arXiv:2605.10730v1, submitted May 11, 2026). All numbers are taken from the paper’s text, tables and figures; i10X did not rerun the experiments. The chart was redrawn by i10X from technical report abstract/architecture of the paper, which is published under a CC BY 4.0 license.
i10x Perspective
Qwen-Image-2.0 is another step in the omni-model trend: stop shipping a generator and an editor. If the unified quality claims hold outside Alibaba’s benches, pipeline switching becomes a legacy UX.