Quick Take
- The finding: YuE2 first writes a readable symbolic score, expands to semantic tokens, then renders full-song audio via an AR–NAR Mixture-of-Transformers.
- Planning helps: With the same checkpoint, experts prefer symbolic planning for overall quality 49.3% vs 34.6% without planning (rest ties).
- Leaderboard: WildSongBench SongBench Global Avg 6.73; best-of-8 reaches 6.96, highest mean among evaluated systems.
Symbolic models compose but stop before a recording; audio models finish songs but hide structure. A multi-lab team (HKUST, Tokenwave, HKGAI, NYU, M-A-P, Stanford, MBZUAI, ACE Studio) unifies both through symbolic planning.
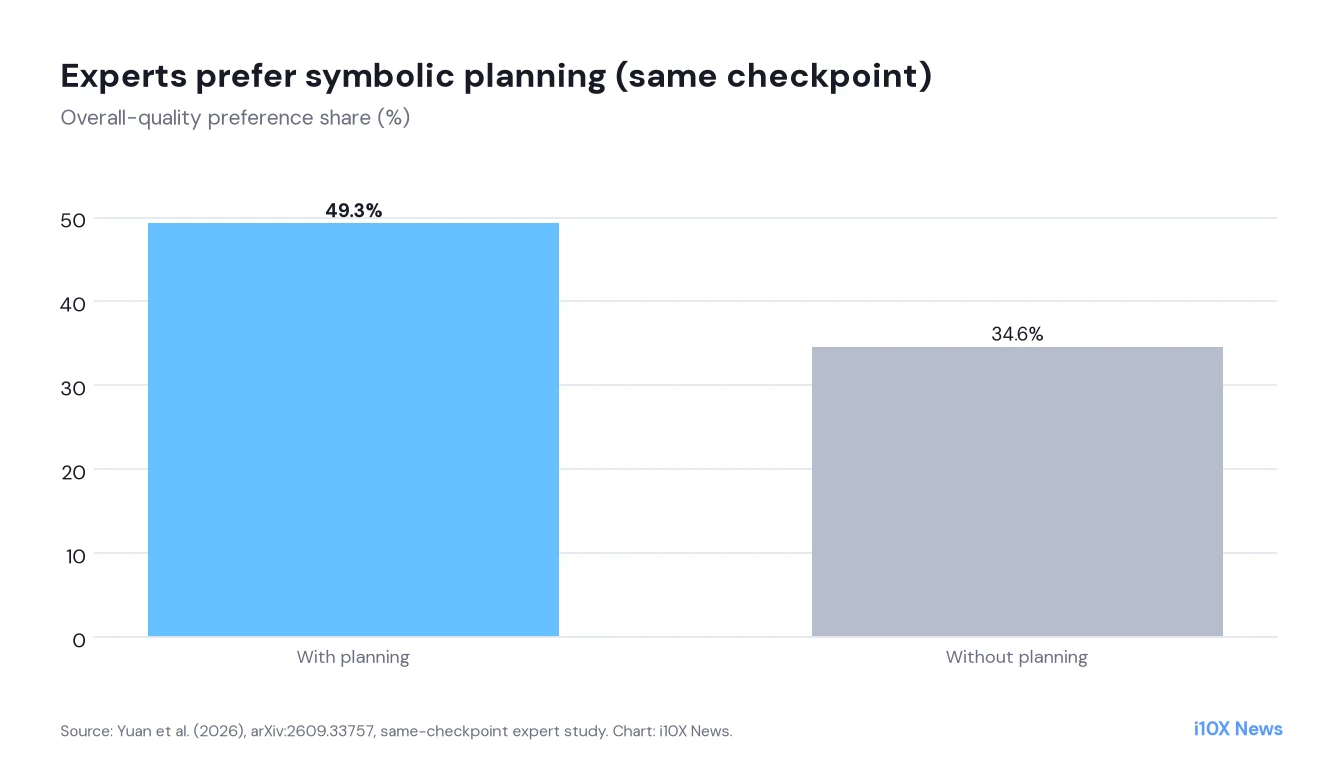
What the study shows
Experts also favor the unified model over a separate LM+DiT stack. Against proprietary systems, best-of-8 YuE2 gets 57.3% overall preference vs Suno v4.5’s 30.5%; nearly tied with Suno v5; trails Suno v6 on preference despite higher SongBench.
- Audio quality strength: Mean tie-adjusted preference 58.9% across six proprietary baselines.
- Codebook health: Utilization exceeds 99% on validation.
Why it matters: readable plans
A score users can inspect is a control surface audio-only generators lack — and experts hear the difference.
Method in brief
Frozen SheetSage2 / MERT / VAE analysis paths; expert listening tests; WildSongBench.
What remains open
- Preference vs automatic scores: Suno v6 preferred more despite lower SongBench.
- Best-of-8 compute: Selection budget matters.
Context
Related audio generation in Multimodal.
What it means for music AI products
- Expose symbolic plans: Users edit melody/harmony.
- Offer best-of-N: 6.96 needs selection.
- Track both prefs and SongBench: They can disagree.
About the analysis
Researched and written with AI assistance under the editorial responsibility of the i10X News team. The title image is an AI-generated illustration. Read our AI Use Policy. Spotted an error? Request a correction.
This article is based on the full text of the preprint “YuE2: Unifying Symbolic and Audio Music Generation at Frontier Quality” (arXiv:2609.33757v1, submitted September 27, 2026). All numbers are taken from the paper’s text, tables and figures; i10X did not rerun the experiments. The paper is distributed under arXiv’s non-exclusive license, so i10X does not reproduce its figures; the chart was drawn by i10X from numbers reported in same-checkpoint expert study.
i10x Perspective
YuE2’s 15-point preference swing for planning is a clean A/B: same weights, more structure up front, better music. Composition does not have to stay implicit to sound finished.