Quick Take
- The finding: In strong-to-weak distillation, on-policy rollouts offer no consistent accuracy edge: best means are 72% (OnPD) vs 73% (OffPD).
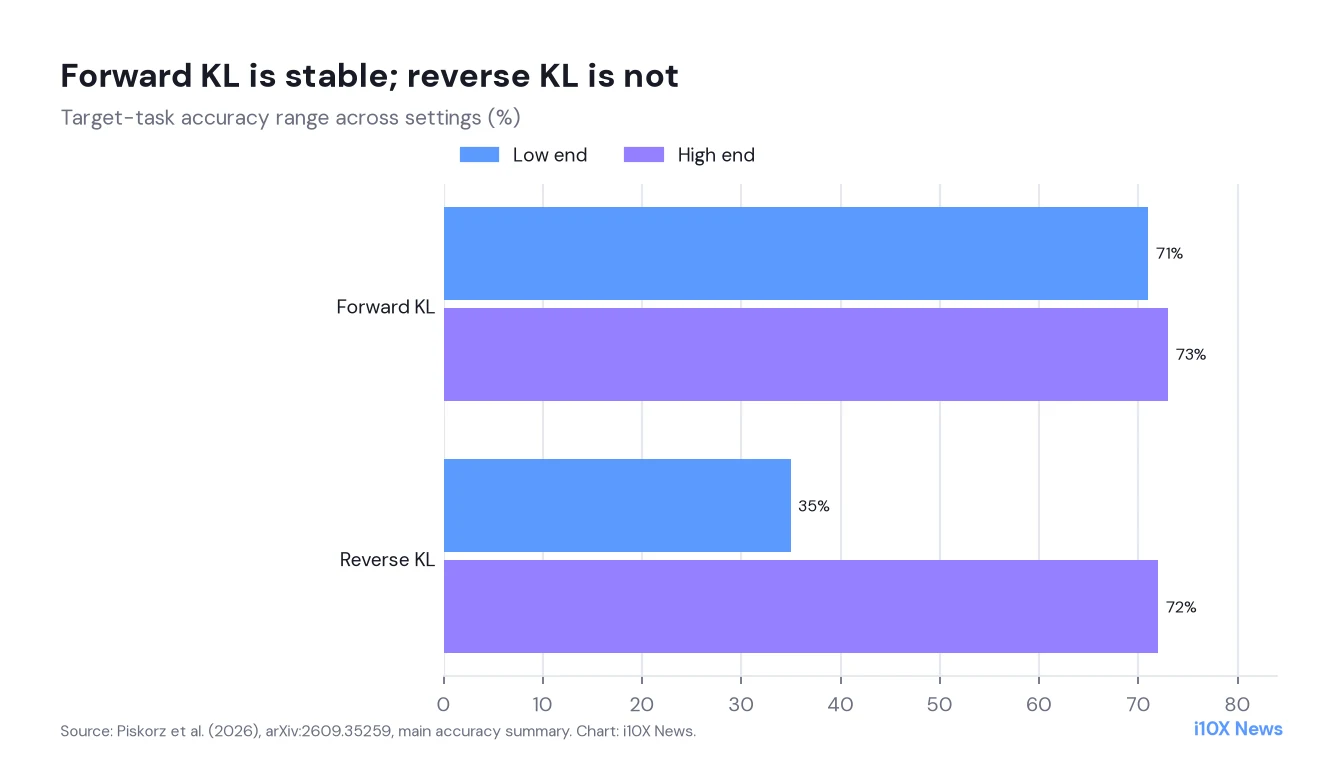
- KL direction dominates: Forward KL holds 71–73% across settings; reverse KL ranges from 35% to 72% and is learning-rate sensitive.
- LR governs forgetting: OOD drops ≤1.3 pp at low LR but 11.2–14.0 pp at high LR; update sparsity falls from ~85–90% to ~52–60%.
On-policy learning is often credited with less forgetting, sparser updates and better generalization. Cambridge researchers note that prior SFT-vs-RL comparisons entangle many factors. They isolate rollout policy in controlled distillation on Llama 3 and Qwen2.5 families.
What the study shows
Independently vary rollout policy, token-level KL direction and learning rate (1e-5 or 5e-5) across scientific, medical and arithmetic reasoning tasks. Also sweep a continuous student–teacher rollout mixture via λ.
- Forward KL is robust to rollout policy: Performance stays strong despite policy changes.
- Reverse KL prefers student-like rollouts: More sensitive overall.
- Sparsity tracks LR almost perfectly: R²≈1.00 between LR and update sparsity on Countdown-3.
Why it matters: stop over-crediting on-policy
Teams pay for on-policy sampling assuming it is the key ingredient. This study says check KL direction and learning rate first.
Method in brief
Controlled factorial design on Llama 3 and Qwen2.5; KL gradient analysis; continuous rollout spectrum.
What remains open
- Distillation setting: Strong-to-weak; may differ from RLVR from scratch.
- Task set: Reasoning domains tested.
Context
Related distillation dynamics in Efficiency & Training and Reasoning.
What it means for distillation pipelines
- Default to forward KL: More robust.
- Keep LR low if OOD matters: Forgetting is LR-driven.
- Do not assume on-policy is required: Measure it.
About the analysis
Researched and written with AI assistance under the editorial responsibility of the i10X News team. The title image is an AI-generated illustration. Read our AI Use Policy. Spotted an error? Request a correction.
This article is based on the full text of the preprint “On-Policy or Off-Policy Learning? A Systematic Study of Distillation Dynamics” (arXiv:2609.35259v1, submitted September 28, 2026). All numbers are taken from the paper’s text, tables and figures; i10X did not rerun the experiments. The chart was redrawn by i10X from main accuracy summary of the paper, which is published under a CC BY 4.0 license.
i10x Perspective
A careful negative result is still a result. On-policy distillation’s folklore advantages largely fail to appear once other knobs are controlled. Sometimes the boring hyperparameters were the story all along.