Quick Take
- Summary: A newly released paper by Google researchers reveals a striking phenomenon across the AI landscape: despite vast differences in architecture, open versus closed licensing, and creator paradigms, today’s leading Large Language Models exhibit highly converged inference and reasoning patterns.
- What happened: By deploying standardized prompts, identical decoding settings, and cross-model agreement metrics across benchmarks like MMLU and GSM8K, the Cross-LLM Study found that different AI models consistently follow the same logic pathways—and more alarmingly, make the exact same mistakes.
- Why it matters now: The AI industry relies heavily on ensembling, multi-agent frameworks, and “LLM-as-a-judge” systems under the assumption of cognitive diversity. If models universally share inference patterns, combining them yields an echo chamber rather than a robust safety net, disrupting current approaches to scaling synthetic intelligence.
- Who is most affected: Engineering teams building multi-LLM routers, enterprise procurement officers evaluating API lock-in, and safety researchers modeling adversarial attack vectors.
- The under-reported angle: Algorithmic monoculture introduces systemic infrastructure risk. If different frontier models share reasoning habits, they implicitly share zero-day vulnerabilities. An adversarial exploit that breaks one model will likely break them all, centralizing the risk of AI deployment.
🧠 Deep Dive
Have you ever watched two very different models reach the same odd conclusion on a tricky prompt? Beneath the marketing battles between OpenAI, Google, Anthropic, and Meta lies a quiet, structural convergence. The “Cross-LLM Study,” initially surfaced via arXiv and the Google AI Blog, introduces standardized evaluation frameworks to quantify what many developers have intuitively felt: contemporary LLMs are beginning to think exactly alike. Stripped of temperature variance and stochastic noise, different foundation models demonstrate intense inter-model agreement.
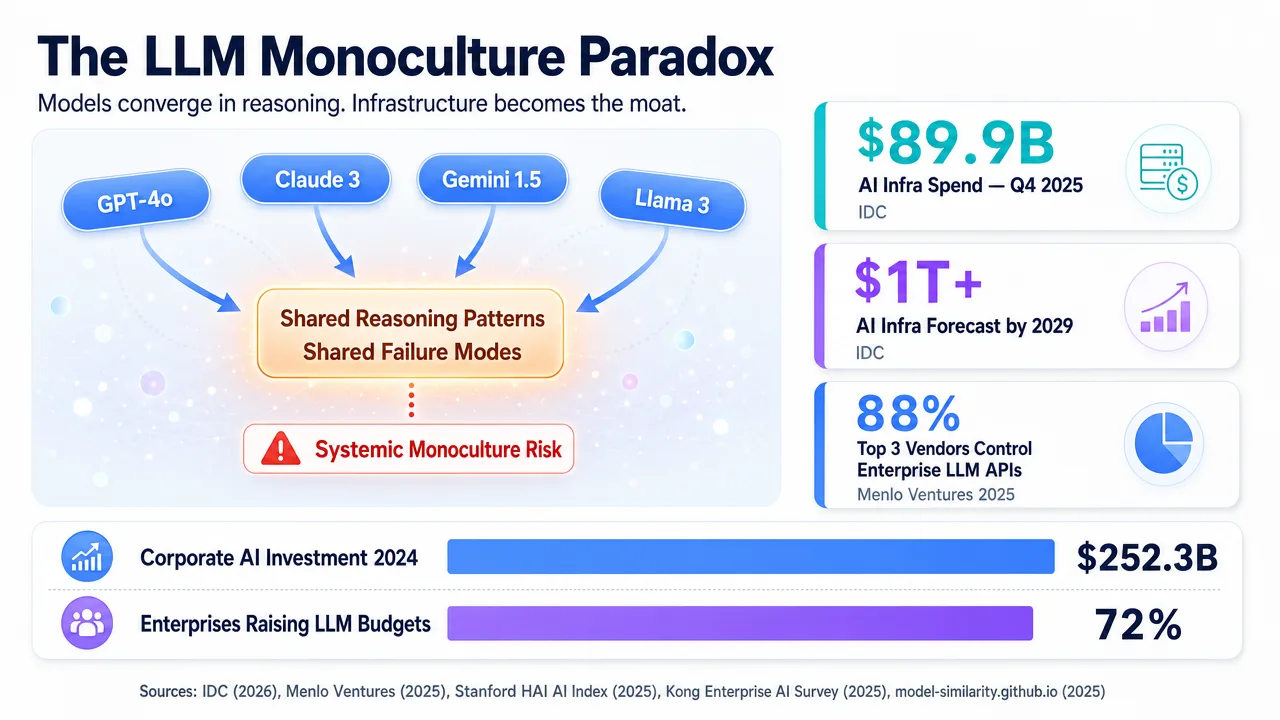
From what I’ve seen, this convergence forces a radical reframing of how we manage AI infrastructure. The typical enterprise playbook advocates for multi-model architectures—routing tasks to different providers to avoid vendor lock-in and mitigate individual model hallucinations. Platforms like Towards Data Science have spent months pushing ensembling, self-consistency sampling, and “majority voting” as the gold standard for MLOps reliability. But here’s the thing: this study suggests that cross-model ensembles may be statistically redundant. If Claude and Gemini share the same logical blind spots as GPT-4, utilizing them to cross-check one another does not compound reasoning capability. It simply compounds token costs and inference latency.
The data reveals a deeper tension surrounding pre-training distributions. Community analyses from hubs like LessWrong have seized on a critical side effect of this research: shared inference implies shared failure modes. Because nearly all frontier models are trained on overlapping massive datasets—the sum total of human internet output—they internalize the same systemic biases and fragility. This cognitive monoculture means that adversarial attacks and red-teaming exploits are increasingly cross-compatible. A successful jailbreak for one model instantly becomes a weaponized payload capable of breaching the broader AI ecosystem.
For the physical AI infrastructure market, the implications are massively deflationary for software and inflationary for hardware. If intelligence generation is structurally uniform across vendors, “model quality” ceases to be an intellectual moat. Procurement teams will shift their focus from the model’s brand name to its underlying delivery infrastructure. The winning LLM will simply be the one with the highest GPU availability, the lowest energy overhead, and the fastest API routing. As AI shifts from an exotic capability to a standardized utility, the real war will be fought at the level of data centers, power grids, and silicon orchestration.
📊 Stakeholders & Impact
| Stakeholder / Aspect | Impact | Insight |
|---|---|---|
| AI / LLM Providers | High | Differentiation becomes harder. Moats shift from model architecture to raw access to compute, inference speed, and ecosystem integration. |
| MLOps & Infrastructure | High | Multi-model routers will prioritize latency and cost (GPU availability) over “model logic” since reasoning patterns are overwhelmingly shared. |
| Safety & Red-Teamers | Significant | The discovery of shared failure modes means single exploits can compromise multi-vendor AI pipelines, requiring broader systemic defenses. |
| Enterprise Procurement | Medium-High | Reduces the fear of vendor lock-in. Companies can swap out proprietary models for cheaper open-source alternatives without breaking logical workflows. |
✍️ About the analysis
Researched and written with AI assistance under the editorial responsibility of the i10X News team. The title image is an AI-generated illustration. Read our AI Use Policy. Spotted an error? Request a correction.
This independent research analysis synthesizes scientific preprints, MLOps practitioner discourse, and AI safety critiques to map the real-world implications of cross-LLM convergence. It is designed for CTOs, AI infrastructure leads, and developers trying to navigate model selection, benchmarking evaluations like MMLU/GSM8K, and the shifting economics of intelligence scaling.
🔭 i10x Perspective
The Cross-LLM Study is the canary in the coal mine for the commoditization of foundational intelligence. If all models ultimately regress to a shared mean of reasoning, the “genius” of AI is no longer a localized product, but a universal property of scale. Over the next five years, expect the competitive landscape to pivot violently from pure algorithm design to physical infrastructure optimization; whoever commands the cheapest gigawatt of power and the densest cluster of GPUs controls the market, because the algorithms themselves have already converged. Watch closely how regulators and alignment researchers address this emerging monoculture—when machines all think the same, a single point of failure can collapse the entire grid.